Preloader

Technology

Show HN: Mini-AGI – Dynamic continual learning model trained on 8GB VRAM

mini-AGI

mini-AGI – is a continual learning byte-level language model that assembles its own architecture, trains from scratch on a single 8 GB VRAM GPU, and keeps learning from everything it reads.
It stores its weights as ordinary files on disk and pages them onto the card as it needs them, so the parameter count is bounded by free disk space rather than by VRAM. It grows new capacity while training when it runs short, prunes what nothing asks for, and reads through exactly the same code path it serves on. Targeted at a PC or laptop with at least an 8 GB VRAM GPU on the board.

NOTE: as of now this is a small toy-level model. Do not expect a frontier level capabilities. This is rather a small experiment to show, that continual learning from the single stream of data without catastrophic forgetting is possible. Furthermore it is possible on a modest hardware. Which means that almost everyone could train their own version of the model (or simply continue training this one) exactly as they see it fit. And the capabilities would be bounded by the actual hardware, scale and quality of the data available and the amount of time one willing to spend on training the model.

dashboard
Here is how min-run dashboard looks like. The model is pointed to the corpus to constantly read and learn from.

History – here is the samples from the whole training run history so far. You can inspect them yourself to see how the model improved over the course of training/reading the corpus.

The weights are not published yet. The run is still reading its first pass over the corpus, the weights go up once it has been through all of it, which is a couple of weeks away at the current rate.

Motivation

Every language model you can actually own today is a model somebody else trained and then froze. You can fine-tune around the edges of it, but you cannot train one from scratch on your own hardware, and you cannot keep training it on what you do day to day – the moment you try, it forgets what it knew before. The result is that a personal model is always somebody else’s model with a thin layer of you on top, and it stops learning the day it ships.

mini-AGI model has small enough GPU footprint that it is possible to train end-to-end on one consumer card, and it is built so that training never has to stop. It reads a stream of characters one chunk at a time, takes a gradient step on each, and the same path serves generation. There is no separate fine-tuning regime and no frozen base: reading and being trained are the same event.

Three constraints shape everything else in the design:

  • It has to fit on 8 GB. Not with quantisation – training needs gradients and optimiser state, which is roughly three times the weights again. So the weights live on disk and only the working set is resident.
  • It has to not forget. A model that learns continually and overwrites itself is worse than one that does not learn at all.
  • It has to be able to read anything. The alphabet is the 256 byte values, so there is no tokenizer to fit and no data type that needs a new vocabulary.

The model is genuinely yours: trained on your hardware, on your data, that keeps learning from every conversation you have with it, and that nobody else can take it away or switch it off.

How the architecture works

Characters (bytes) does not pass through a fixed stack of layers as it would be in a traditional LLM. Instead, it passes through two dense prelude blocks and then through one recurrent block applied up to 24 times, each application choosing its own experts from a shared pool. The latent state between applications is never decoded – it is merged with the embedded input by an adapter each time round, so the loop cannot drift away from the text it is reading.

Three distinct blocks, up to 26 block-applications per character.

  • Adaptive depth. A halting head scores every character at every row, and the character stops as soon as another row would not change the answer. Easy characters take one row, hard ones take many. This is the PonderNet recipe: while training, every depth is computed and weighted by its halting probability, so the halting head learns through those weights.
  • Routing per block-application, not per character. Each of the 26 applications picks its own top-8 experts, so one character touches far more of the pool than “top-8” suggests, and the same expert can be selected several times at different depths. What varies is which eight at each point.
  • No expert is assigned a subject. There are no labels anywhere. Soft top-k routing distributes capability across the pool by itself, and a character can combine fragments from several experts. The cost is that capabilities share parameters and so can interfere.

how the model processes one character

This is the architecture assembling itself, one character at a time, captured from the live model – nothing here is drawn by hand.

Each tile on the left is one expert; colour is expert identity and stays the same for the whole clip. A row is one application of the recurrent block, and the eight tiles in it are the eight experts that row actually ran. The stack grows downward as the model keeps going, and the amber line is where halting stopped it – the grey rows below are computation the model declined to spend.

The trace on the right is how many rows each character took. It moves constantly between 4 and 14 against a ceiling of 24, and the caret under the text shows which character is being read.

Positions are rotary and carry no learned parameters, which is why the context window can be extended by continued training rather than by re-initialising anything.

…and the same thing while it writes

how the model generates text

The clip above is the model reading – every character is held-out text it is being shown. This one is the model writing: it was primed with 2,500 characters of a held-out story and then continued on its own, so the grey text is what it was given and the green text is entirely its own. Greedy decoding, no sampling anywhere – run it twice and you get the same sentence.

Two things are worth watching. The stack behaves the same way, because generating and reading are the same forward pass in this model – the only difference is whether the next character comes from a file or from the model’s own argmax. And writing costs more depth than reading: about 9.9 rows a character against 8.0 on the same subject. The dotted lines mark where the working set was re-chosen, which happens every 64 characters; in this clip nothing swapped, because the prompt had already pulled the right experts onto the card.

What it produced, continuing a story about a cherry tree:

They worked together and saw their favorite shore. One day, they wanted to play with their favorite shore. They wanted to play with it, but

Grammatically correct and on-topic. It does repeats itself for now – which is a fair picture of where the model is at 243M characters.

How paging works

Every expert is a file on disk holding its weights and its Adam moments. Above disk sit two caches and a working set:

key what it is
disk — every expert the model has; bounded by free space
RAM ram_cache recently wanted experts, least-recently-used evicted
VRAM resident the working set – what a character may route through

Before every chunk the model is asked what the text about to be read wants, and the answer becomes the working set. Demand is scored on the hidden states the call sites actually routed on while reading the previous chunk – an embedding carries no context, so scoring on raw embeddings would have every subject asking for the same experts.

Two rules the project holds to:

  • Adam’s moments travel with the expert. They belong to the expert, not to the slot of VRAM it happened to occupy. Leaving them behind would hand one expert’s momentum to whatever took its place, and training would carry on looking healthy while every swapped expert inherited a stranger’s history.
  • An expert already on the card stays in the slot it is in. Demand comes back sorted, so the order churns while the set itself barely moves. Matching by identity rather than by position is what keeps the number of loads equal to how much the set really changed.

Because the choice is made from the previous chunk, it cannot see the text it is about to predict. What keeps the working set from churning on noise is hysteresis – a candidate has to beat a resident by margin to displace it, and a newcomer is safe for dwell_chars of reading.

How growth and pruning work

The pool grows when it is short of capacity and shrinks when parts of it stop being asked for.

New experts are added on speculation, at a small gate so they change almost nothing, and kept only if something goes on asking for them. A new expert is built by recombination – whole hidden units taken from several existing experts – because a clone of one parent is not novel enough to be worth routing to, and a random expert computes nothing worth routing to. What works is novelty assembled from trained parts.

Growth is refused unless every brake agrees:

  • room – disk and VRAM can take it
  • used – the capacity already added is being asked for
  • earning – the previous cohort survived its trial
  • fits – not too many experts are already inside their trial
  • honest – train and held-out have not separated

Dead means unaddressed. Both the growth brake and the pruner read how long it has been since anything asked for an expert, and never its gate. This is the single most useful finding in the repository: the gate is not merely uninformative here, it is anti-predictive. The smallest gates belong to the busiest experts – one that behaves as a sink, chosen constantly and contributing little per character, reads as dead on a gate test, while a high-gate expert nothing has wanted in hundreds of thousands of segments reads as alive.

A new expert is safe for a full survival window no matter what, so it cannot be judged before it has had a chance to be chosen. When the model grows an expert a new file appears; when it prunes one, that file is deleted.

How continual learning works

Training on a single stream, one subject at a time, is the classic recipe for catastrophic forgetting. Reading half a million characters of chess at the experts’ own learning rate takes the other seven subjects from 1.12 to 3.73 nats.

The trunk learning rate is the mechanism. The trunk – embeddings, attention, routers, the halting head – is the part every character passes through, and it carries 97.6% of the squared gradient norm. Running it at 0.1x the experts’ rate takes forgetting from +2.2300 to +0.0067 nats, which is 99.84% of progress retained against chance.

configuration unread subjects retained vs chance
working set frozen, trunk LR = expert LR +2.5871 42.88%
swapping, trunk LR = expert LR +2.2300 50.68%
swapping, trunk at 0.1x – what the run uses +0.0067 99.84%
control: all seven subjects read -0.0077 –

Forgetting under three configurations

This is the measurement the whole design rests on. The model reads 524,000 characters of chess and nothing else, at batch 1, and the y-axis on the left is what happened to the seven subjects it did not read – zero means nothing was forgotten, up means worse. Three lines, one variable each. Two of them climb to +2.2 and +2.6 nats, which is the model losing most of what it knew. The third, at a trunk learning rate one tenth of the experts’, never leaves the floor: +0.0067 nats after half a million characters of a single subject.

The grey dashed line is the control – the same probe with all seven subjects read, where forgetting is impossible by construction.

The right panel converts the same three arms into progress retained against chance. The gap between 50.68% and 99.84% is one number in a config file.

Two readings matter here, and the second one corrects this project’s own earlier account:

  • The expert pool is not what prevents forgetting. Freezing the working set – removing the one property that makes the pool a pool – costs only 0.3571 nats, 13.8% of the effect. In that arm 93 of 136 experts received no gradient at all and the model still collapsed. Preserving most of the weights is not sufficient.
  • The damage is displacement, not destruction. Damage the model badly and then read everything again: three quarters of it comes back in 131,000 characters, against the ~50M characters it took to learn those subjects the first time. Knowledge that had to be relearned does not come back 380x faster. “Catastrophic” describes how it looks at the bottom of the curve, not what happened to the weights.

Every subject during a massed read, and how much of the pool was touched

What that same read looks like from the inside. This is the working configuration – trunk at 0.1x – during the identical 524,000-character chess probe. On the left, every subject plotted against where it started. Chess, the subject actually being read, improves by 0.013 nats. The shaded band is the range across the seven subjects that are not being read, and it stays within ±0.02 nats for the whole probe: learning one thing did not cost anything measurable anywhere else. That is the claim in the first paragraph of this README, drawn rather than asserted.

The right panel is why that is possible at all. Over the whole probe only 54 of 136 experts received any gradient – 60% of the model was structurally untouched, because routing never selected it. This is the pool doing exactly what a pool is for: confining an update to the part of the model that the text actually addressed.

The learning rate is not scheduled. A cosine schedule asserts that the run ends, which for a model that reads continually is false. Instead a controller watches held-out loss and moves the rate in both directions: clear improvement buys a little more, no evidence eases it down, and a confirmed jump in held-out steps it back up.

Reading your own files

This is the shortest path to a model that knows something you care about.

python3 train.py read ~/notes                     # a dry read - nothing kept
python3 train.py read ~/src ~/docs --passes 3 --save

Point it at files or directories. There is nothing to prepare: the alphabet is the 256 byte values, so a file is already written in the only vocabulary the model has. Directories are walked, binaries are skipped by sampling their contents rather than trusting the extension, and each file is read from its beginning to its end because a document has an order.

It is the same path training uses: same chunking, same cache, same gradient step.

flag
--passes N read the whole set N times
--save keep what it learned; without it weights/ is untouched
--lr default 5e-5, below a training run: reading should adjust the model, not overwrite it
--mix "" skip the before/after scoring

Two defaults worth knowing. Nothing is saved without --save, so a read is a dry run until you decide otherwise. And it scores the held-out mixture before and after, then says plainly if reading your files cost the model ground elsewhere – the forgetting question measured per-read rather than assumed away.

Benchmarks

The numbers below are for tracking purposes and move as the run continues. Held-out loss is reported with its standard error, and the size of the evaluation is what sets that error – a difference smaller than it is the instrument rather than a result.

There is a second variance underneath these figures. The same configuration run twice lands about 0.014 apart, because the expert dispatch is not deterministic on CUDA. Treat about 0.03 as the threshold for a real difference, not the error bar printed beside one score.

Where the model is (318.1M characters read, 169 experts):

nats/char bits/byte
held-out, all eight subjects 0.8336 ± 0.0331 1.2026
train 0.6809 0.9823

Held-out loss per subject:

Subject nats/char bits/byte
chess 0.552 0.796
stories 0.637 0.919
arithmetic 0.657 0.948
code 0.739 1.066
reasoning 0.794 1.145
chat 0.831 1.199
chat_hermes 1.178 1.699
wikipedia 1.280 1.847

Data Scaling

Data scaling against published byte-level and subword models

Every point on this chart is a model with a published bits-per-byte – the only loss unit that survives a change of tokenizer, which is why a byte-level model can be put beside GPT-3 at all.

Three held-out sets are involved – PG19, Pile-CC and this project’s own mixture – so the vertical positions are not strictly comparable across colours. MambaByte-353M is the closest like-for-like, same parameter class and essentially the same FLOPs per byte, and it read 94x more data than this model has. Transformer-320M read 251x more.

The results so far are promising. The red line is the fitted power law, L ∝ D^-0.239 with R² 0.96 over every point past the warmup – a clean, healthy exponent, between Kaplan’s 0.095 and Chinchilla’s 0.28, and it has held for more than a decade of data. How steep it looks depends on where the fit starts: windows from 40M to 150M give 0.21 to 0.32, and the band on the chart spans that range rather than pretending to one number.

Read straight off that trend, and remembering that the target is this model’s own mixture rather than PG19:

held-out bytes needed days at ~778 char/s
1.10 BPB 0.51B ~3
1.00 BPB 0.75B ~6
0.93 BPB 1.02B ~10
0.80 BPB 1.92B ~24

Those are days to weeks of reading on one laptop GPU, not years, and all of them sit inside a single pass of the 7.87B-character corpus.

The right panel shows which subjects are still moving. Code, chat, stories and reasoning are the steep ones; wikipedia and chat_hermes carry the most loss and have the shallowest slopes, which is the honest counterweight – the expensive domains are not the fastest ones.

Running it

  1. Make sure you have a CUDA-capable GPU with at least 8 GB of VRAM, and Python 3.10 or newer. The reference machine is an RTX 3070 Laptop GPU with 8 GB.
  2. Clone the repository:

    git clone <repository-url>
    cd mini-AGI
  3. Install the dependencies:

    pip install torch numpy pyyaml matplotlib      # the model, and its graphs
    pip install flask                              # serve.py
    pip install tokenizers chess zstandard         # building corpora
    pip install scipy                              # a few of the analysis tools

    PyTorch has to match your CUDA version – see the PyTorch install page. The reference environment is torch 2.6.0+cu124 with numpy 1.24.4. Only the first line is needed to train.

  4. Build the corpus. One command downloads the four public datasets and generates the other four lanes:

    python3 -m corpora all                  # all eight subjects, a few GB
    python3 -m corpora all --limit 5000     # a small slice first, to try it
    python3 -m corpora all --full           # entire datasets: tens of GB, hours

    Lanes already on disk are left alone, so an interrupted build can simply be run again. Individual lanes are available too – python3 -m corpora lists them – or skip this entirely and point the model at your own files.

  5. Start reading. The weights directory is created from config.yaml the first time, so there is nothing to set up:

    python3 train.py read data/train --save --weights-dir weights 
        --held-out data/val --sample-every 10
  6. Serve it:
    python3 serve.py --port 8080            # then open http://127.0.0.1:8080

The run writes a sample log, redraws its graphs as it goes, and checkpoints every few minutes. It is meant to be left alone for days.

Everything else

python3 -m minagi.store weights                    # what the model is right now
python3 -m corpora                                 # every corpus target
python3 -m corpora all --only wikipedia stories    # rebuild particular lanes
python3 -m corpora expand                          # .bin -> the text files read

python3 train.py read --help                       # every knob the reader has
python3 train.py stream --steps 140000 --lr 2e-4   # the packed-corpus path
python3 train.py ponder-probe --ckpt weights       # depth against difficulty

Every tool takes --ckpt weights – the directory is the model, and there are no .pt files to keep track of.

Initialization

A fresh model starts small and grows into its shape. The context window begins at model.context_start and extends one character at a time, but only when the model is still getting something out of the far end of the window it already has. The expert pool begins at pool.experts and grows from there.

This means the first hours of a run look nothing like the rest of it. Loss falls fast, the pool churns, the window is short, and the learning-rate controller has not gathered enough evaluations to act. None of that is a problem to fix.

If a run diverges, it repairs itself: when held-out exceeds the best by more than --revert-factor (default 1.5x) the run reloads weights/, halves the learning rate, pulls the context back and continues. After --max-reverts it stops rather than thrash.

Layout

minagi/          the model. no command lines here.
  config.py        reading config.yaml, which building and training both use
  precision.py     what the model computes in, and how moments are stored
  tokenizer.py     bytes in, bytes out - 256 values plus structural markers
  model.py         the transformer: RMSNorm, rotary positions, SwiGLU, flash attention
  decode.py        how a character is chosen, without a random number generator
  ingest.py        turning a pile of files into something to read
  pool.py          the expert pool, and the rules by which it grows and shrinks
  paged.py         the same pool spread over disk, RAM and VRAM
  recur.py         latent recurrence with adaptive depth
  stream.py        reading a corpus behind a KV cache, one chunk at a time
  store.py         the weights directory, which IS the model
  optim.py         how much of a gradient is signal
  plasticity.py    the learning rate, governed by held-out loss
  live.py          serving a model that is being trained underneath
  report.py        the model reading statistics off its own weights
  create.py        writing a fresh weights directory from config.yaml

train.py         read | stream | ponder-probe
serve.py         local web UI
config.yaml      the settings worth changing
corpora/         python3 -m corpora all - the whole corpus, downloaded and made
weights/         one file per expert. this directory is the model.

weights/ is written on the first run and data/ by corpora; neither is in
the repository. Everything else above is.

The weights directory is the model

weights/
  manifest.json     what exists, its shape, and where it came from
  core.npz          embeddings, attention, norms, adapter, halting head
  routers.npz       the gate, the segment router, one row per expert per site
  optim.npz         Adam moments for the trunk and the routers
  experts/          one file per expert: w1, w3, w2 and its own Adam moments
    e00000.npz ...

Training resumes from it – weights, Adam moments and step count – and advances it whenever a run improves on what is there, so a session run only to check something still contributes if it finds anything. The directory holds the best state the model has reached, not the most recent one. Writes are atomic: every file is written to a .tmp and renamed, so an interrupted save cannot leave a half-written weight behind.

The directory is written on the first run.

The model

Byte level – vocabulary 265: the 256 byte values plus 9 structural markers (<think>…</think> scratchpad, <user>/<bot> turns, <g> for games, and end-of-text). Context 4,096.

body RMSNorm, RoPE, SwiGLU, flash attention via scaled_dot_product_attention
depth 3 distinct blocks, up to 26 block-applications per character
recurrence one weight-shared block applied up to 24 times; the latent is never decoded
halting PonderNet – each character halts independently, so hard ones get more depth
routing top-8 experts per block-application, chosen per character
paging 32 experts resident on the card; the rest live on disk

The parameter count moves, because the pool grows and prunes itself while training. python3 -m minagi.store weights prints what it is now. At the time of writing:

core        8.27M   embeddings, attention, norms, adapter, halting head
routers     0.17M   one row per expert per call site, plus depth embeddings
experts   531.6M    169 x 3.15M each  (3 x 512 x 2048)
--------------------
total     540.1M

VRAM is set by the working set, not by the pool. Only 32 experts are resident at a time – about 109M parameters of the 540M – which is why the pool can keep growing on an 8 GB card. Per byte the model costs about 2.4 GFLOPs to train, which puts it in the same compute class as a dense 400M byte-level transformer.

AI usage

This project was assisted by “Claude Opus 5” model. The model did implemented most of code of this project, verified and debugged it when it was necessary. The model was searching for published papers related to the problems that the project were trying to solve, build tests and experiments, and help with brainstorming the complex problems that arose along the way. The animations, graphs and other media you see here are all done by Claude as well form the real data traces. While I myself provided main ideas, steering, intuition, rejections when thing went in a wrong direction, code monitoring and verification, as well as decisions and strong opinions of how everything should be wired together and work in principle. Documentation was written in tandem.

Acknowledgments

PyTorch does the arithmetic, NumPy holds the weights on disk, and Matplotlib draws every graph.

The parts the model is built out of:

Outrageously Large Neural Networks: The Sparsely-Gated Mixture-of-Experts Layer – Shazeer et al., 2017. The entire expert pool, and the load-balancing auxiliary loss.
Switch Transformers – Fedus et al., 2021. The capacity-based batched dispatch, which is what lets the pool run as three matrix multiplies.
PonderNet: Learning to Ponder – Banino et al., 2021. The adaptive depth mechanism.
RoFormer: Rotary Position Embedding – Su et al., 2021. Why the context window can grow by continued training.
GLU Variants Improve Transformer – Shazeer, 2020. SwiGLU.
Root Mean Square Layer Normalization – Zhang & Sennrich, 2019.
FlashAttention – Dao et al., 2022. Reached through PyTorch’s scaled_dot_product_attention.
Decoupled Weight Decay Regularization – Loshchilov & Hutter, 2017. AdamW.
Training Deep Nets with Sublinear Memory Cost – Chen et al., 2016. Gradient checkpointing, which on 8 GB is not optional.

ZeRO-Offload – Ren et al., 2021, and ZeRO-Infinity – Rajbhandari et al., 2021. Training a model larger than the card it sits on is not a new capability.
Dynamic Mixture of Experts Against Severe Distribution Shifts – Kim et al., 2025. Adds experts to a live MoE, and reports the failure this project spent a week fixing.

Training Compute-Optimal Large Language Models – Hoffmann et al., 2022. Chinchilla, and the ratio any efficiency claim has to be tested against.
The Pile – Gao et al., 2020. Bits per UTF-8 byte, chosen there for invariance to tokenisation.
Transformer-XL – Dai et al., 2019, and Compressive Transformers – Rae et al., 2019. The character-level benchmarks to aim at.
An Empirical Model of Large-Batch Training – McCandlish et al., 2018. The gradient noise scale.
The AdEMAMix Optimizer – Pagliardini et al., 2024. Implemented for the trunk and available, though at the paper’s settings it hurt this model and it is not the default.

The corpus: TinyStories, OpenHermes-2.5, OpenThoughts-114k and the Lichess open database. Wikipedia and the source-code portion come from public dumps and public repositories.

Citation

If you use this project in your research or work, please cite it as:

@software{Borsky_mini_AGI_2026,
  author = {Borsky, Alexey},
  month = {9},
  title = {{mini-AGI: A Continually Learning Byte-Level Language Model}},
  url = {https://github.com/volotat/mini-AGI},
  version = {1.0.0},
  year = {2026}
}

Source: Hacker News

One-Electron Universe

Page semi-protected
From Wikipedia, the free encyclopedia


The one-electron universe is the hypothesis that all electrons and positrons are actually manifestations of a single entity moving backwards and forwards in time. It was proposed by theoretical physicist John Wheeler in a telephone call to Richard Feynman in the spring of 1940.
A similar “zigzag world line description of pair annihilation” was independently devised by E. C. G. Stueckelberg at the same time.[1]

Overview

The idea is based on the world lines traced out across spacetime by every electron. Rather than have myriad such lines, Wheeler suggested that they could all be parts of one single line like a huge tangled knot, traced out by the one electron. Any given moment in time is represented by a slice across spacetime, and would meet the knotted line a great many times. Each such meeting point represents a real electron at that moment.

At those points, half the lines will be directed forward in time and half will have looped round and be directed backwards. Wheeler suggested that these backwards sections appeared as the antiparticle to the electron, the positron.

Many more electrons have been observed than positrons, and electrons are thought to comfortably outnumber them. According to Feynman he raised this issue with Wheeler, who speculated that the missing positrons might be hidden within protons.[2]

Feynman was struck by Wheeler’s insight that antiparticles could be represented by reversed world lines, and credits this to Wheeler, saying in his Nobel speech:

I received a telephone call one day at the graduate college at Princeton from Professor Wheeler, in which he said, “Feynman, I know why all electrons have the same charge and the same mass” “Why?” “Because, they are all the same electron!” (…) I did not take the idea that all the electrons were the same one from [Wheeler] as seriously as I took the observation that positrons could simply be represented as electrons going from the future to the past in a back section of their world lines. That, I stole![2]

Feynman later proposed this interpretation of the positron as an electron moving backward in time in his 1949 paper “The Theory of Positrons”.[3] Yoichiro Nambu later applied it to all production and annihilation of particle–antiparticle pairs, stating that “the eventual creation and annihilation of pairs that may occur now and then, is no creation nor annihilation, but only a change of directions of moving particles, from past to future, or from future to past.”[4]

See also

References

  1. ↑ Silvan S. Schweber, QED and the Men Who Made It, p. 388, Princeton University Press, 1994, ISBN 0691033277.
  2. 1 2 Richard Feynman (11 December 1965). “Nobel Lecture”. Nobel Foundation.
  3. ↑ Feynman, Richard (1949). “The Theory of Positrons” (PDF). Physical Review. 76 (6): 749–759. Bibcode:1949PhRv…76..749F. doi:10.1103/PhysRev.76.749. S2CID 120117564.
  4. ↑ Nambu, Yoichiro (1950). “The Use of the Proper Time in Quantum Electrodynamics I”. Progress of Theoretical Physics. 5 (1): 82–94. Bibcode:1950PThPh…5…82N. doi:10.1143/PTP/5.1.82.


Source: Hacker News

ChatGPT now knows what you do on other websites via ad collector

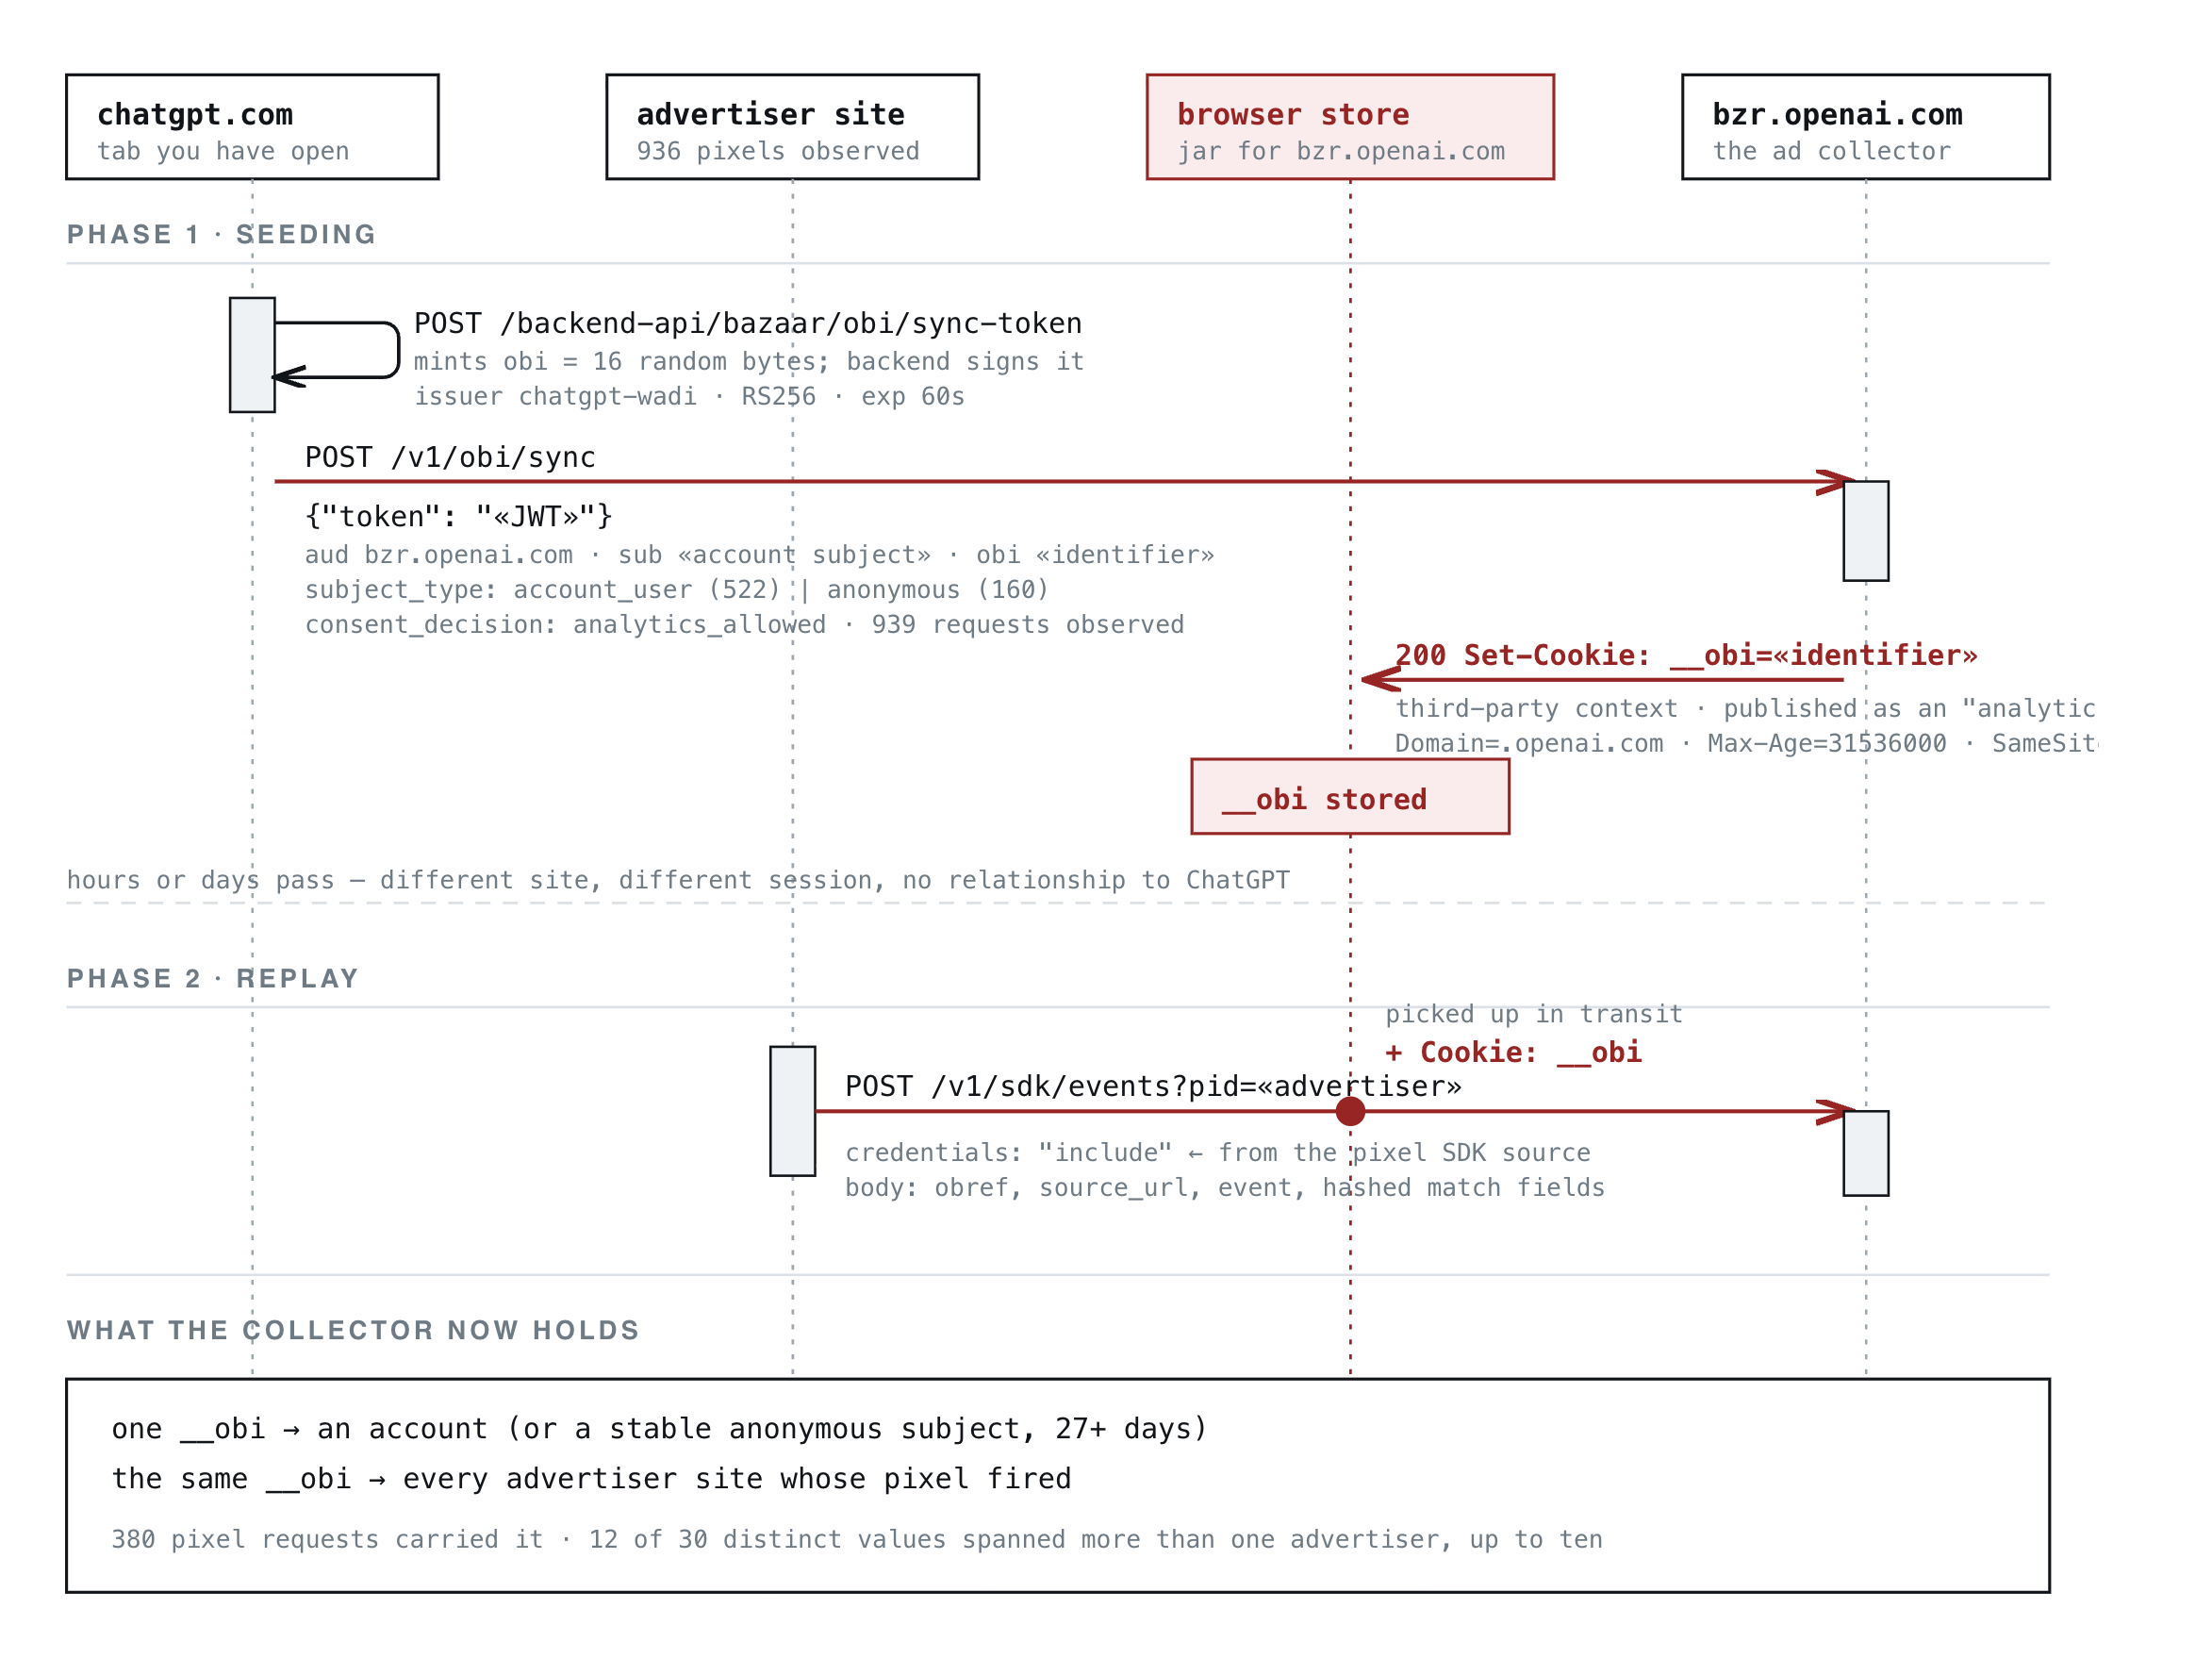
OpenAI’s ad collector at bzr.openai.com sets a cookie called __obi, scoped to .openai.com. The value is while you are on ChatGPT and tied to your ChatGPT account. __obi is then sent to OpenAI from ordinary websites you visit.

Any company that buys ads on ChatGPT installs a small piece of OpenAI code on its own site, the same way retailers already install Meta and Google tracking code. Loading that code, sends __obi to OpenAI along with data about the page you are browsing. This includes products you are searching for, articles you are reading, and purchase behaviors.

The bottom line is that OpenAI can connect what you do on those sites to your ChatGPT account.

I reproduced the full mechanism on my own phone, verified with two independent capture methods, and cross-checked against several months of observed traffic covering 936 distinct advertiser pixels across 1,029 hostnames.

How it works

Step 1. ChatGPT creates an identifier and signs it.

On chatgpt.com, the client generates 16 random bytes and calls POST /backend-api/bazaar/obi/sync-token (or /backend-anon/ when signed out). The backend returns an RS256 JWT:

{
  "iss": "chatgpt-wadi",
  "aud": "bzr.openai.com",
  "purpose": "obi_sync",
  "operation": "set",
  "consent_decision": "analytics_allowed",
  "consent_policy_version": "user_granular_consent_v1",
  "sub": "«redacted: 64-hex account subject»",
  "subject_type": "account_user",
  "obi": "«redacted: 22-char identifier»",
  "exp": "«iat + 60s»"
}

sub is the account. obi is the identifier. The token binds them, is scoped to the collector, and expires in 60 seconds. bzr stands for bazaar, OpenAI’s internal name for the ads platform; wadi is the issuing service.

Step 2. The identifier becomes a cookie on OpenAI’s domain.

The client POSTs {"token": "«JWT»"} cross-site to bzr.openai.com/v1/obi/sync. The response:

Set-Cookie: __obi=«redacted»; Domain=.openai.com; HttpOnly;
            Max-Age=31536000; Path=/; SameSite=none; Secure

SameSite=none with Secure is the configuration a cookie needs to be sent on cross-site requests. Max-Age is one year. The obi value in the JWT and the value in the cookie are identical.

Step 3. Advertiser sites send it back.

Three request classes go from an advertiser’s page to OpenAI’s hosts. On a phone with __obi in the jar, all three carried it:

Request Carried __obi Notes
GET bzrcdn.openai.com/sdk/oaiq.min.js yes the script load itself
POST bzr.openai.com/v1/sdk/events with obref yes conversion events
POST bzr.openai.com/v1/sdk/events, bare body yes the SDK’s “no credentials” path
GET bzrcdn.openai.com/pixel-config/… no cookie header at all control

The first row is particularly interesting. The pixel SDK has a code path that omits credentials, and it does not help: the browser attaches cookies to the <script src> request that loads the SDK before any of OpenAI’s code runs. By the virtue of loading the tag the identifier is disclosed.

What travels with it

The same SDK also collects identity from the advertiser’s page. The payload separates four sources, labelled by OpenAI itself: in for values the advertiser passes deliberately, and fm, ht, js for values the SDK scrapes from form fields, rendered page text, and the tag-manager bus. In observed traffic, scraped identity outnumbered advertiser-supplied identity 685 events to 255.

The tag-manager bus is the largest source of email. The SDK replaces window.dataLayer.push with its own function, also reads adobeDataLayer, and locates renamed GTM layers by parsing the l= parameter off the gtm.js script tag. Current versions take email and phone from it. Version 0.1.31 also took names and geography before the scope was narrowed on 27 August.

Email, phone, first and last name are SHA-256 hashed before transmission. Country, region, city and postal code are sent in the clear. Postal code was the most-harvested form field, 100 events across 28 sites.

URLs are reduced to origin plus path before sending; none of 23,929 observed carried a query string. Paths survive, and paths reaching the collector included a medical condition, a debt-solutions funnel and a litigation intake form.

Automatic matching was enabled for 638 of 881 pixels with a known setting, including every credit and lending advertiser observed. It is controlled from OpenAI’s Ads Manager. A denylist excludes passwords, one-time codes, card numbers, SSN, date of birth, medical history, diagnosis and court fields.

On the same advertiser-page requests, every other OpenAI cookie was blocked by the browser:

Cookie Outcome
oai-did, oaicom-stable-id blocked, SameSite=Lax
oai-client-auth-info, session cookies blocked, domain mismatch
__obi sent

__obi is the only OpenAI identifier configured with SameSite=None.

Observed reach

On my device, one __obi value was sent to OpenAI from 12 commercial websites under 13 distinct pixel IDs, including Chewy, Wayfair, ThriftBooks, Eventbrite, HelloFresh, Coursera and SeatGeek. Every request was accepted with 202.

In the broader traffic, 12 of 30 distinct __obi values appeared under more than one advertiser, one under ten.

It works when you are logged out

Across 932 decoded sync tokens, 736 carried subject_type: account_user and 196 carried anonymous. The anonymous subject is as stable as the account subject: one per device, persisting at least 27 days.

OpenAI’s cookie policy lists __obi under Analytics cookies, one year, on chatgpt.com and openai.com. It is the only entry in that section. The policy describes analytics cookies as helping OpenAI understand how its services perform and are used.

OpenAI runs analytics and marketing as two separate consent choices, oai_consent_analytics and oai_consent_marketing, and every sync token I decoded carried consent_decision: analytics_allowed. Someone who allows analytics and refuses marketing gets this.

OpenAI’s response

I sent the mechanism and two questions to press@openai.com and privacy@openai.com on 14 September: why __obi is classified as an analytics cookie, and whether a user who grants analytics consent and refuses marketing consent still receives it. The reply came from OpenAI Support. It acknowledged the inquiry, said the observations would be shared internally for review, and did not answer either question. The script-load observation above was made after the inquiry was sent. I will update this post if OpenAI responds.

Limits

Browsers. Observed on Chrome for Android. Safari’s Intelligent Tracking Prevention blocks all third-party cookies, and Chrome on iOS runs on WebKit, so the mechanism does not operate on any iOS browser. Desktop Chrome is untested.

Gating. Roughly one ChatGPT session in five produced a sync token. ChatGPT’s mobile web client serves ads without syncing at all. Someone following the steps below may see the pixel fire with no cookie attached.

The join is not observed. 202 means the collector accepted the event with the cookie attached. That OpenAI resolves it to the account server-side follows from the design; I did not watch it happen.

Meta built the structural equivalent years ago. A logged-in account, third-party cookies on pixel fires, off-site conversions resolved to a profile. The mechanism is standard adtech. What has no precedent is running it on an AI chat product. People tell these products things they would not put on a social network, and these products increasingly act on their behalf.

The pixel’s other cookie does not do this. __obref is set on the advertiser’s own domain. Each site gets a different value and no site can see another’s. Of 2,860 values observed, 2,828 appeared under exactly one advertiser.

Advertisers cannot see this. __obi belongs to a domain their scripts cannot read. They installed a conversion pixel and have no way to know their visitors are being resolved to a ChatGPT identity.


Source: Hacker News

New evidence for hidden chambers beyond Tutankhamun's tomb

Enjoying our latest content?
Log in or create an account to continue

  • Access the most recent journalism from Nature’s award-winning team
  • Explore the latest features & opinion covering groundbreaking research

or

doi: https://doi.org/10.1038/d41586-026-02621-2

References

  1. Eldamaty, M., Abbas, A. M., Ballard, G. & Reeves, N. Occasional Papers of the Amarna Royal Tombs Project No. 8 (2026).

  2. Reeves, N. Occasional Papers of the Amarna Royal Tombs Project No. 1 (2015).

  3. Fischanger, F. et al. J. Cult. Herit. 36, 63–71 (2019).

    Article 

    Google Scholar
     

Download references

Subjects

Latest on:

Nature Careers

Jobs


Source: Hacker News

Weeping whales: Stillborn humpback whale grieving documented

Weeping whales: Stillborn humpback whale grieving documented

Gaby Clark

Scientific Editor

Robert Egan

Senior Editor

humpback whale
Credit: Elianne Dipp from Pexels

Humpback whale mothers may experience grief when their calves die, a rare research observation led by Griffith University and Sea World Foundation has found.

In 2025, a female humpback whale—along with an escort whale—was observed off the southern Gold Coast after giving birth to a presumed deceased calf. She remained with it for several hours and possibly even days.

Dr. Olaf Meynecke, from Griffith University’s Whales and Climate Research Program, said postmortem attentive behavior in cetaceans had been documented predominantly among toothed whales and delphinids (known as odontocetes), but remained largely absent from research published on baleen whales, like humpback whales.

“Unlike reports of toothed whales where mothers have been observed lifting their dead calves to the surface, this humpback whale mother showed prolonged postmortem behavior and attention toward her deceased calf under the surface,” Meynecke said.

*May cause distress to viewers* This video, taken in 2025 off the southern Queensland coast in Australia, shows a humpback whale mother returning to the seafloor to her stillborn calf. Credit: Andy Mulville

A rare view beneath the surface

“She remained close to the calf, maintaining eye contact and positioning herself next to her calf over several hours and maybe even days.

“These observed behaviors were consistent with caregiving or nurturing actions and postmortem attentive responses documented in socially complex mammals, and indicated an inherent, strong maternal attachment to the calf.”

Cetaceans are among the most charismatic marine species receiving widespread public attention.

Rescue boat Capt. Andrew Mulville from Sea World Foundation, who witnessed the event, said, “When I actually worked out what was happening, I was totally surprised.

“At first sight, I thought it was just two whales resting on the surface, but their behavior was unusual.

“It was definitely not what I was expecting to see out at sea that day.”

A case that expands the record

Meynecke said this observation in 2025 and others involving deceased calves were incredibly sad, rare and added to the limited current understanding of the cognitive and emotional dimensions of death-related responses in baleen (filter-feeding) cetaceans.

“This case study highlights the need for continued systematic documentation of rare neonatal mortality events to better understand the cognitive, emotional and evolutionary significance of postmortem behavior in large whales,” he said.

“Understanding how nonhuman animals responded to death provides insight into their emotional lives, social bonds and cognitive capacities.”

The study “First documentation of humpback whale (Megaptera novaeangliae) postmortem attendance of a stillborn” has been published in Discover Animals.

More information

Discover Animals (2026). DOI: 10.1007/s44338-026-00232-9

Key concepts

animal behaviorrorqualshumpback whales

Who’s behind this story?

Gaby Clark

Gaby Clark

MA in English, copy editor since 2021 with experience in higher education and health content. Dedicated to trustworthy science news.

Full profile →


Robert Egan

Robert Egan

Bachelor’s in mathematical biology, Master’s in creative writing. Well-traveled with unique perspectives on science and language.

Full profile →

Citation:
Weeping whales: Stillborn humpback whale grieving documented (2026, September 16)
retrieved 20 September 2026
from https://phys.org/news/2026-09-whales-stillborn-humpback-whale-grieving.html
This document is subject to copyright. Apart from any fair dealing for the purpose of private study or research, no
part may be reproduced without the written permission. The content is provided for information purposes only.

Source: Hacker News

Suzanne Ciani's Buchla Cookbook

This digital edition presents the original text alongside the 1976 tape examples provided by Suzanne Ciani. Where the original typewritten edition includes hand-drawn diagrams and musical illustrations, this digital edition relies on several elements for each musical idea described in the document:

Both the diagrams and the musical illustrations follow the original hand-drawn material closely, with additions based on descriptions from the text or on historical research.All audio examples other than the ones provided by Suzanne Ciani are intentionally simple, built by replicating the original signal path with software-equivalent modules in VCV Rack.The diagrams and the VCV Rack videos use an arbitrary color code for cables:

The original document by Suzanne Ciani can be purchased on her website:

Tell us about the context in which you wrote the Cookbook. Were you documenting for yourself, for a community, or for posterity? What does it mean to you today that it still functions as a reference for Buchla practitioners, fifty years later?

As a “starving artist,” I would apply for grants and this paper was written to satisfy a composer grant from the National Endowment for the Arts. I didn’t think anyone would ever understand it, but I needed to describe my compositional practice.

Tell us about what drew you to the 248 in the first place. It was a piece of gear unknown to the world, and you may have been among the first users, with the Cookbook written before the release of the official 1977 manual. When did you acquire it? Did you have a working relationship with Don Buchla while developing your approach on the MARF? Did you consider it as a means to realize your musical ideas, or did those ideas emerge from the practice of the instrument?

At the time, I was totally focused on the Buchla. I had come to New York City to give a live performance in the Bonino Gallery for a sculptor friend of mine, Ron Mallory. I wanted to make a career as a Buchla performer. From photographs from this period, I notice that my Buchla system was constantly modifying…the consoles that held it, the road cases that transported it, the ever-increasing number of modules. I imagine that Don would have told me about the MARF, and I always wanted to get the first one of anything that came out. I did have a working relationship with Don, but our thoughts about the MARF were quite different. I adored it and couldn’t live without it. He once said to me that it was a “failed” concept. I think we had very different ideas about what it was.

The Cookbook references serialism, acousmatic space, and cybernetic self-playing systems, which were all important matters in 1970s avant-garde music. How did you position yourself in relation to the dominant musical ideologies of the time, and has that positioning changed?

I think that as an artist, I lived in my own world to a great extent. I had studied composition and basically rebelled against the systems I encountered, like serialism. I thought music should come from an emotional starting point. However, I have to admit that my work with the Buchla does reference some “systems” approach to composition. I once wrote a paper on Boulez and his use of musical note modules. In some ways, those ideas were better manifested by machines than note scribes.

Clearly conscious of these ideas, you may have been the only avant-garde composer making diatonic music with a Buchla 200 in the mid-1970s, and yet that music could not have been performed on a more tonally oriented system such as a Moog or ARP. Did you feel isolated in that practice?

Yes, it was very lonely to speak a language that no one else was speaking. It was because of that musical loneliness that my first album, Seven Waves, was not a pure Buchla album, but a synthesis of my electronic language with my classical root system.

The four sequencer rows are designed to work melodically and harmonically. Tell us about your composition process and how these sequences came to be. Was there a moment you decided they should not change and follow you throughout your whole career?

Laughing out loud. In those days, I had a great big sequencer with 4 rows of 16 knobs, and I could design the sequences in situ, listening to them as I made them. Because of the National Endowment paper, those particular sequences got documented. Other than that paper, I never documented anything. So, oddly, when I came back to live performance, I referenced the paper and adopted those sequences. I call them “raw material.” They get transformed so much in a performance that I’ve never felt the need to change them. Also, they work really well together.

Buchla was notoriously agnostic about control interfaces, building touch plates, touch keyboards, and mechanical keyboards. As a trained pianist, how did you receive this? What was your relationship with the 237 Polyphonic Keyboard, which is involved in the Cookbook?

Buchla trained me early on that the traditional keyboard was “an inappropriate interface.” I took that to heart and hardly touched a piano in those years. I was very conscious of the difficulty he had presenting his ideas to the community…that people didn’t understand and you had to be very clear about things. The traditional keyboard was the enemy. I became a staunch proponent of communicating his ideas. The 237 came about, I think, because Buchla wanted to show polyphony…he created the possibility of polyphony, though it wasn’t true polyphony. I never used the keyboard to play chords but found other interesting ways to use the design.

The Cookbook is unusual in that it documents patches and transitions between them, as a blueprint for live performance. Was the idea of live electronic performance being discussed in the avant-garde circles around you, or were you working that out largely alone?

There was no awareness of electronic live performance in my “avant-garde circles.” I thought Phillip Glass should be using a Buchla to perform his mechanistic patterns that humans played like machines. He wasn’t adaptable to it. Steve Reich thought that such electronic instruments should be “sent to the moon.” Vladimir Ussachevsky came to my concert at Phil Niblock’s loft. Ilhan Mimoroglou gave me my first American record deal at Atlantic/Finnadar. These were both electronic composers, but we were using different media

By 1976, Suzanne Ciani had been working with Buchla instruments for close to a decade, since meeting Don Buchla as a graduate student at UC Berkeley in the late 1960s. She arrived in New York in 1974 with, by her own account, little more than her Buchla system and a suitcase of cables, and spent her first years there in the city's downtown avant-garde — for a time sleeping on the floor of Philip Glass's studio while moving in circles that included Steve Reich, John Cage, Ornette Coleman and Merce Cunningham. Out of that period came a National Endowment for the Arts Composer Grant, and the document this article concerns — a report Ciani submitted to satisfy it, which over the years has become known as The Buchla Cookbook.

The instrument at the center of that report was Don Buchla's Series 200 "Electric Music Box," and in particular its most notorious module: the Model 248, or Multiple Arbitrary Function Generator — the "MARF."

A 16-stage memory that can be approached as a sequencer, an envelope generator, an oscillator, anything in between, addressable in almost any order, the MARF had already acquired a reputation among Buchla owners as the system's most flexible and most unusual tool.

What makes Ciani's cookbook valuable is that it is not a description of the MARF's features in the abstract, but a tested, practical account — tone rows, patch diagrams, and performance actions — of how to actually play it musically. That practice didn't emerge in a vacuum. The Buchla instruments carried a set of assumptions distinct from the East Coast, Moog-associated tradition: touch-plate control rather than piano-style keyboards, a vocabulary built on voltage-controlled processes rather than fixed notes, design suited as much to improvisation as to composition. This "West Coast" sensibility traced back to the San Francisco Tape Music Center and figures like Morton Subotnick and Pauline Oliveros. Ciani's cookbook, written by a classically trained pianist and composer, is in part a negotiation with an instrument that wasn't originally built to favor either of those backgrounds — and the techniques it catalogues, including what she called "Melodic-Rhythmic Reliefs" and the "Vertical Sequencer," read as field notes on the vocabulary she had used the year before in two unissued concerts later reissued as Buchla Concerts 1975. Read alongside those recordings, the cookbook functions almost as a score after the fact, in a practice — live modular improvisation — that otherwise left little paper trail

Ciani's relationship to the document didn't end with its submission in 1976. When she returned to live Buchla performance in the 2010s, after decades largely spent in commercial sound design and recording , she has said in interviews that she went back to this same paper to relearn her own techniques and to adapt them on modern Buchla 200e Instruments— still calling it, fifty years on, "a cookbook for how to play the Buchla." That makes it a rare case of a historical document remaining, for its author, an instruction manual rather than only an artifact.

The MARF itself has had a comparable afterlife. Scarce even in its own era, the original Model 248 existed for decades mostly as a catalog item among Buchla owners, until Tiptop Audio — working from schematics and Buchla's 1977 manual, in the absence of a working original, and in official partnership with Buchla USA — released a Eurorack recreation, the 248t, in early 2026, marketed around its reputation as "the holy grail of West Coast signal creation." Its return is one sign of a larger shift: much of the 200 series is now available again, original and clone alike, to a generation of musicians who never had access to it the first time. That generation is the reason this document matters now.

The modular synthesis "renaissance" of the past decade, driven by Eurorack but returning again and again to Buchla's ideas about voltage control and live-generated form, has revived exactly the questions this report was written to answer — not what a patch sounds like, but how to build one, live inside it, and move between musical ideas in front of an audience. Ciani has been an essential, active part of that revival rather than a distant reference point for it: For the last 10 years  she as been performing regularly on Buchla modular systems, giving workshops around the world, after-shows Q&A with the audiences, being involved in academia as a visiting scholar at Berklee College of music, releasing quadraphonic LPs, and collaborating with younger Buchla-identified artists such as Kaitlyn Aurelia Smith, thus becoming, for a new wave of musicians discovering non-keyboard instruments for the first time, something closer to a living bridge to the scene the cookbook came out of. Written forty years before that scene existed, The Buchla Cookbook already answers many of its open questions. Part of this edition's purpose is simply to make that visible.

Following is an outline of a “Basic Performance Patch” which I designed for Buchla Series 200 instrument, and a brief description of some of the musical ideas that evolved as a result of working with this patch.

For the sake of clarity, I give each of the musical ideas a distinct and descriptive name: “Keyboard Rotations,” “Melodic-Rhythmic Reliefs,” “Vertical Sequencer,” and “String Patch.” The first three of these are concerned primarily with permutations of given ordered sets of pitches, accomplished either by means of the sample and hold of the polyphonic keyboard, or by means of a matrixing of the sequencer rows by the AFG: (Multiple) Arbitrary Function Generator. The “String Patch” illustrates a completely different use of the AFG.

Also given are step by step examples of how to go from one of these ideas to another in a performance situation. These are only rough maps, but they do illustrate the characteristic facility for musical metamorphosis that the instrument possesses; and they also show the kind of playing technique that one has to develop for live performance. In the practiced performer, a kind of instinct comes into play, and making a transition from one musical idea to another is almost a matter of reflex — and somewhat difficult to describe in detail.

Also given are a few techniques for rhythmic improvisation, which I generally keep for the “climax” of a performance, and some techniques for discrete spatial rhythms.

I find that the best performances combine the competence of pre-planned and well-rehearsed playing with the magic of being able to follow one’s inspiration when inspired by the audience and the moment. To do the latter, a performer must be familiar with his patch to the point of not having to “think twice” (at least not more than once) about what effect or series of consequences will be produced by a given action.

Every mention of the "AFG" in this document refers to Buchla's Model 248 Multiple Arbitrary Function Generator, or M.A.R.F. This module holds an unusual interface and feature set, directly derived from computer music thinking. Back in 1971, the Buchla 500 system was controlled by a minicomputer in which one could program "stages" as sets of data: voltage, duration, interpolation, and a role within a sequence. This could be seen as a sequencer, a complex envelope, a low-frequency oscillator, or an addressable memory. The 248 came in 1974 as a more commercially viable alternative: a module based on newly available C-MOS components to replace the software, with a bank of faders and spring-loaded switches with LEDs to replace the keyboard and screen. After a few years, and probably fewer than 10 units built, the project was abandoned due to component failure, and the rise of the microcomputer opened up new technical possibilities. Future iterations of the MARF concept found their way into the Buchla 300 series as software-controlled hardware devices. Yet this "in-between solution" produced a unique situation: for once, a sophisticated sequencer was both programmable and performable. It is no wonder it found its most important representative in Suzanne Ciani, who focused her use of the MARF on live performance. In recent years, the 248 has enjoyed an interesting afterlife: surviving units were, per owners' testimonies, recovered from dumpsters, garage sales, or music centers. Technicians such as Marc Verbos, Richard Smith, and members of the M.E.M.S. project have documented their restoration work. Clone builders, such as Roman Filippov, based their versions on schematics and former users' testimony. These new units are now used live by Suzanne Ciani. Buchla USA has since announced on social medias an official reissue, and the Eurorack adaptation by TipTop Audio, in partnership with Buchla, is now in commercial production.

At the center of Suzanne Ciani's practice of the MARF is one feature: any fader value for each stage could be replaced by 4 different external voltage sources, making the 248 a highly sophisticated sequential switch even by today's standards. This is the core idea behind her use of the MARF: a performable processor for pitch CV signals from a 4-row sequencer. She would later name her performances "improvisation on 4 sequences." While the 246 sequencer holds the 4 invariable sequences at the heart of her career, improvisation is carried through the MARF.

The “Basic Performance Patch”* outlined describes the fundamental signal and control voltage routing for a patch which I have used in performance. The following is a general survey of features of this patch and the considerations taken in designing it.

Diagram 1 : Basic Performance Patch

The signal sources are primarily two oscillators, with a third oscillator available for the part of the performance called “Keyboard Rotations” (described later), and a white noise source used mainly in the percussion improvisation. One of the frequency control voltage inputs of each of oscillators 1, 2 and 3 is controlled by the keyboard – all tuned in unison, diatonically. Oscillators 1 and 2 are also frequency controlled by the AFG 248-1602 outputs 1 and 2 respectively, so that the limited range intervals are octaves. These two oscillators are also controlled, via the AFG “external” mode, by the 246 16-stage sequencer.

Note on the Range switches and Buchla tuning:

This document often refers to the MARF's "range" feature. The 2 AFGs voltage outputs have a full range of 0 to 10V for both sliders and external sources. The "limited" range switches compress this to a 2V band. The quantize switch divides this range into 12 equal intervals. Though never stated on the panel or manual (in keeping with Don Buchla's well-documented agnosticism on musical genres), this allows diatonic playing on a 2V/octave norm. The 248 may thus be among the first tools to offer live diatonic pitch quantization outside computer music. This 2V window is then offset by the switch used: 0 to 2V (+0), 2 to 4V (+2), and so on. In a diatonic context, these switches act as octave transposition. This is why the labels +2, +4, +6, +8 read as +1 oct, +2 oct, +3 oct, and +4 oct, respectively. While Buchla instruments are best known for a 1.2V/oct norm, exceptions and variations abound. The 258 oscillators in this system have an input attenuverter, so the difference between the +0 and +2 switches can be tuned to an octave.

Additional Diagram 1.1 : Pitch Control

The AFG in “external” mode and the sequencer are a powerful combination for pitch control. First, the AFG allows quantization of the sequencer voltages via the “quantize” mode of the AFG, for easy setting of pitches. Note that the first stage of each sequencer row is set at the lowest note of the row, or “0” volts, to provide a tuning convenience as well as a stopping position in order that the keyboard can take over as sole pitch controller. (To take advantage of this, a single pulse from the subsection of the keyboard can be assigned to both stop the sequencer and select stage 1.) Second, the AFG allows a totally flexible matrixed access to the sequencer voltages, horizontally, vertically, and obliquely, and the rows have been designed with that consideration: to work in any direction and combination, melodically, harmonically, and contrapuntally.** Third, the AFG allows instant octave transposition of any row or any part of any row.

The rhythmic possibilities of this combination will be discussed later.

All of the oscillators are routed directly to a matrix mixer, oscillators 1 and 2 detouring as well through a frequency shifter. At times in the performance when oscillators 1 and 2 are tracking at a unison or an octave, the frequency shifter provides a timbral enrichment, as in the “String Patch,” for instance, which we will look at later. At other times, non-harmonic sonorities are produced, which I use percussively. (In some cases, I can get an immediate cue as to whether the two oscillators are on the same stage of the AFG, being able to display visually only one at a time, because of the dramatic difference between shifted unisons or octaves and any other intervals.)

Additional Diagram 1.2 : Audio Path

All of the signals are routed through a matrix mixer for distribution to any of three filters or no filter. Since the filters are tied to gate positions, selection of a filter also selects a gate. The envelope control for the gate is a quad V.C. 284. In a performance, I choose freely among trigger sources for each envelope by having at least three banana patch cords already plugged into the pulse input, and then making the connection to the pulse output of the AFG, sequencer, or keyboard — or looping back to the envelope pulse output — depending on the needs of that part of the performance. In general, with this patch, I use the pulse outputs of the AFG series 1 and 2 because of the rapidity with which they can be programmed or “played,” and because of the rhythmic possibilities and combinations available. Sometimes no envelope is used, the gate simply opened. For quick variation of the envelope, I bridge all of the control voltage inputs and route an offset voltage from the 256 Adder (which gives me the option of adding in other or varying control voltages as well). This one offset voltage allows me variously to shrink or expand any envelope very quickly in a performance, the direction and amount individually controlled by each of the four control voltage input knobs.

Additional Diagram 1.3 : Gates and Modulations

Finally, the signals are routed to a spatial locator and then out to four amplifiers and four speakers. (Use of a voltage-controlled reverb is optional.) I consider the spatial characteristics — where a sound is placed and the way it moves — to be an integral part of the music, and I plan and “play” the space of each part of the performance. In the future, I expect that this will be one of the most refined aspects of electronic music; but given the present state of electroacoustics and the deficiencies of performance halls in this regard, I find it most effective to use clearly delineated types of spaces such as the following:

I use a slow continuous curved space for the “String Patch,” the arc related to the “bowing” envelope.

(Please see the graphic description.) In this type of space, the sound comes very precisely from one speaker at a time, the duration in each speaker precisely controlled. Two features of this type of space are: firstly, continuous tones can be given rhythmic impulse defined solely by spatial placement (I use this with sequencer Row A alternate, for instance, where there is little melodic rhythm); and secondly, there is no masking effect for the audience since the sound is completely in only one given speaker at a given instant.

In percussive passages, I route the trigger pulses to a 265 stored random voltage source pulse input and drive the X and Y C.V. inputs of the 227 with the resultant control voltages.

Use the 265 continuous random voltage source.

I think of these as spatial phrases or sentences, and find the 257 Dual Control Voltage Processor very useful.

Ciani's live, gestural approach to spatial control sits within a much longer history of composers treating sound placement as a musical parameter in its own right. — from Stockhausen's rotating-speaker Kontakte through John Chowning's computed quadraphonic trajectories at Stanford, to Ambisonics, 5.1, Wave Field Synthesis, and today's object-based formats — Ciani's real-time approach remains a pioneering reference point in its performative, live approach to this sonic, technical parameter.

Multichannel sound was not a peripheral concern in early electronic music — for several of the field's founding figures, it was close to the point of the enterprise. Stockhausen's Kontakte (1958–60) is often cited as the first fully quadraphonic composition, its four-channel image built by physically rotating a loudspeaker on a turntable, ringed by microphones, to capture sounds orbiting the listening space — spatial movement produced mechanically, by hand, before any electronic means of doing so existed. By the early 1970s, quadraphonic playback had also become a short-lived consumer format, and this is the moment both Chowning and Ciani enter the picture, from very different directions.

At Stanford, John Chowning's 1971 paper "The Simulation of Moving Sound Sources" set out an algorithmic method for placing and moving sounds within a quadraphonic field using amplitude panning, simulated Doppler shift, and the ratio of direct to reverberant signal — the last of these being, at the time, a genuinely novel insight: that a listener's sense of a sound's distance depends less on its loudness than on how much of what they hear is early reflection versus room reverberation. His 1972 composition Turenas was the demonstration piece, its sound trajectories entirely computed and fixed onto tape in advance, note by note and path by path, on a PDP-10 at Stanford's Artificial Intelligence Lab. It is spatialization as composition: precise, mathematically derived, and — crucially — decided once, off-line, before anyone hears it.

Ciani's approach in this document could hardly be more different in method while pursuing a strikingly similar goal. Where Chowning computes a trajectory, Ciani performs one, live, with her hands, using the Buchla 227 Spatial Locator and a vocabulary of "continuous," "discrete," and "random" spatial types that she can mix and cross-fade in real time, the same way she treats pitch or timbre. There is no notation, no offline pass, no fixed path to be reproduced identically twice — spatialization here is a musical paramenter, played with the same reflexes as the oscillators and filters, and subject to the same demand for improvisational fluency she asks of every other part of the patch. It's telling that she considered a quadraphonic PA a precondition for performing at all, to the point of refusing at least one prominent engagement without one: for Chowning, quad was a canvas for a fixed piece; for Ciani, it was closer to a fourth instrumental voice.

Both belong to a wider mid-century turn — running through Stockhausen, the Groupe de Recherches Musicales' multichannel diffusion practice in Paris, and Chowning's own later founding of CCRMA — toward treating spatial position as a compositional parameter in its own right, on equal footing with pitch and timbre, rather than as a mixing decision made after the music itself was finished. What's specific to Ciani's contribution is doing this live and gesturally, inside a performance practice, at a moment when almost everyone else working seriously on spatialization — Chowning very much included — was doing so through offline computation.

The subsequent history of multichannel sound largely continues to split along that same line. Michael Gerzon's Ambisonics, developed in the UK in the early-to-mid 1970s, offered a format-independent, mathematically rigorous model of a full sound field — closer in spirit to Chowning's precision than to Ciani's gesture, though eventually adaptable to live use. Commercial quadraphonic hardware collapsed by the late 1970s under competing incompatible formats, but the underlying idea resurfaced repeatedly: 5.1 surround for cinema in the 1990s, Wave Field Synthesis research at IRCAM and TU Delft in the 2000s aiming to physically reconstruct a sound field rather than simulate one psychoacoustically, and, in the past decade, object-based formats like Dolby Atmos and Ambisonics-native tools that finally let a sound's position be authored as an independent, movable parameter rather than baked into a fixed channel — which is, in effect, the studio finally catching up to what a spatial locator let a Buchla performer do live in 1976. The current boom in Ambisonics-based live-performance tools and immersive-venue systems (bringing real-time, gestural spatial control back into modular and hybrid performance setups) makes Ciani's approach in this document feel less like a historical curiosity and considerably more like an early instance of where the field was eventually headed.

Diagram 2, Musical Illustration 2, Example 3 on tape

Although a single row of 16 ordered pitches is the basis for this idea, the constant shifting of emphasis as it moves along creates an “aural illusion” that conceals its simple origin. A constant pulse is the basis for the rhythm, and larger rhythmic units are created by timbral emphasis and registral displacement. In some ways this musical technique is related to serialism; however, it was actually born from the seemingly inevitable consequences of an Arbitrary Function Generator meeting a Sequencer.

AFG Output 1 (Osc. 1) is set on External Row A (alternate) at +0 range. (Usually I would give this simple alternation of pitches a “spatial rhythm” by routing the pulse output of the 246 to the 265 stored random voltage input, and the 265 output to a spatial locator. Or I might give it a more discrete and regular rhythm by using a 264 Sample and Hold and a small sequencer, as described in attached Diagram 5.)

AFG Output 2 (Osc. 2) is being strobed by the sequencer pulse, and with an external control voltage from the 265 Uncertainty Source such that a new stage of the AFG is jumped to with each pulse. By driving the AFG in “strobe” mode, I free the “Interval time” output to be used for other than timing control, in this case, for waveshape control. Since all of the AFG voltage sliders except the first one are set at External Row B, AFG 2 will be for the most part looking at a regularly recurring pitch sequence: no matter which stage is strobed to, AFG 2 will see the next pitch of Sequencer Row B. But other variables can be individually programmed at each stage, such as octave transposition, waveshape, or output pulse, resulting in registral, timbral, and rhythmic variations upon the given pitch sequence. The effect is to produce an illusion of several lines going on at once, each one with its own perceived continuity.

* The tape example includes a white noise “click track” and gated/filtered white noise on the 11th pulse of the sequencer.

Note On pre-digital randomness:

This setting allows Suzanne Ciani to set a random probability of accenting a note, using a smooth random voltage sourced from noise to address a stage reading. This analog process lies outside the scope of calculated algorithms based on seeds or pseudo-randomness, which would later become commonplace in software. With each stage having a virtually equal chance of being addressed, the probability of an accent equals the number of stages holding this accent data, out of the total number of stages. A single stage carrying accent data therefore gives a probability of 1-in-16 chance of an accented note. It is worth noting that this randomness is sampled and strobed to the rhythm of the melody, not generated continuously: the result is closer to a shuffled deck than to noise, which is exactly what gives it musical shape rather than chaos.

Diagram 2 : Melodic-Rhythmic Reliefs

Diagram 3, Musical Illustration 3, Tape Example 2

This idea is also the product of the AFG and the Sequencer. The four pitches at each stage of the sequencer are arpeggiated by the AFG, which then advances the sequencer to its next stage, and so on. This produces a regular harmonic rhythm and a musical texture characterized by an interweaving of melodic lines.

The External Output Voltage Levels of the AFG are distributed among Rows A, B, C and D at various octave levels.

A series 2 pulse is programmed at stage 16 of the AFG to advance the 246 Sequencer. (The pulse “2” output of AFG 1 is patched into the “advance” input of the sequencer.)

AFG 1 is driving AFG 2 from its “all pulse” output. At first the two AFG output units track the 16 stages in unison. Then AFG 2 is manually advanced to separate from AFG 1, producing a distinctly separate voice.

At each pass of the 16 stages, a different set of four pitches from Rows A, B, C and D of the sequencer will be played at various transpositions resulting in a harp-like melodic-harmonic texture.

Feel free to change the limited range switches and the output voltage sliders to different external positions, or to manually advance the AFG 2 output in order to bring out different melodic contours in this texture.

Diagram 3 : Vertical Sequencer

This patch produces extremely rich string-like tones and a distinct impression of “bowing.” It is also an example of a patch that “plays” itself.

The two AFG outputs work together, at a unison or an octave, being strobed simultaneously by a rapid pulse from the sequencer, along with a very slowly changing external control voltage. Since the “sloped” function, however, is at slightly different rates in AFG 1 and 2, every time there is a movement, always to an adjacent stage, left or right, the frequencies of the two oscillators separate somewhat, and the frequency shifter for a moment sees two signals not in integral relationship and produces a timbral or “bowing” inflection.

In a performance, I will change the overall range of the “strings,” finding that the sound works equally effectively from bass to violin range.

The Black and White Keyboard gives an illusion of polyphony — up to three voices — by means of a sample and hold circuit, but rather than use this feature to play chords, I prefer to use it as a contrapuntal device, by gating all three oscillators together, to produce shifting melodic patterns.

The basic patterns I show in the illustration are produced by playing an ostinato figure on the keyboard, which is controlling the three simultaneously-gated oscillators, and changing the “number of voices” to 1, 2 or 3.

In our basic Keyboard-AFG-Sequencer Patch, if the sequencer is stopped on stage one, where all the rows are conveniently set at “0” volts, and the AFG is in “external” mode, then the keyboard alone can control the frequency of the oscillators. By taking advantage, however, of the potential control of Osc. 1 and 2 by the AFG-Sequencer combination (waveshape, transposition), further developments of this idea are easily achieved in a performance situation, as we will see in the following performance example.

* The Keyboard Rotations idea could also be accomplished with a monophonic keyboard and a sample and hold or with a sequencer and a sample and hold.

Note On early polyphony in Buchla systems:

The early 1970s saw several attempts at polyphonic keyboards, mainly relying on early digital solutions for voice distribution, before Sequential Circuits proposed a compelling solution in 1977 with the Prophet 5. Most of these attempts are predated by the rather elegant solution of Don Buchla: the 237 keyboard used in this patch was equipped with a set of 3 parallel Sample & Hold systems, each sourcing the same CV from a mono keyboard. When set in unison, they are sampled with the same trigger from the mono keyboard. The polyphony happens when, by activating a switch, this trigger gets distributed in a sequential way to the 3 circuits, so each circuit holds the note attributed by the trigger distribution, while also making its trigger available for each voice's envelope. A similar effect can be achieved with 4 voices using the 219 keyboard, or a mono keyboard combined with the 264 quad Sample & Hold. While this solution lacks flexibility, its limitations are put to musical use in this specific patch.

Additional Diagram 6 : Keyboard Rotations

As a performance example, let’s assume we are going from the “Melodic-Rhythmic Reliefs” patch to the “Keyboard Rotations.”

I have said nothing about the gating and filtering possibilities available in this patch, which is not meant to imply that they are not an important aspect of the musical treatment of any idea. The matrix mixer is a handy routing network that I “play” constantly to get timbral multiples of individual voices and an ever-changing variety of amplitude shapes. These methods of differentiating a sound source from itself are in large part responsible for the illusion that “so much is going on” when in fact the actual sound sources are few. 

* I find that I have to limit the voltage range of this output somewhat, by detouring it through an Adder.

I find that because of the degree of rhythmic responsiveness afforded by the AFG, both alone and in combination with the sequencer, as in our basic patch, a rhythmic improvisation or “cadenza” will be the climax of a performance. Basically, one must be completely familiar with the rhythmic options of a patch before being able to extemporize. With practice, one can develop the mental and physical reflexes to “stay on top” in a performing situation and to play the sound and the space with total control and expressiveness.

The following is a list of some of the rhythmic possibilities of our AFG-Sequencer patch, which are so numerous that I mention only a few:

Program pulses on four stages of AFG series 1 pulse output: stages 1, 6, 9 and 12, for instance. Strobe AFG 1 with a regular pulse from the sequencer and with a randomly changing external control voltage fast enough to cause movement on each pulse. Drive AFG 2 with a regular pulse from the sequencer by bridging the “start” “stop” pulse inputs with the sequencer pulse output. The result will be a regularly repeating rhythmic pattern in one voice with random metrical accents in the other.

Additional Diagram 7 : Rhythmic Improvisation example 1

Strobe both AFG 1 and 2 simultaneously with the sequencer pulse output, both with the same randomly changing external voltage fast enough to cause movement on each pulse. (The two outputs will exactly track each other.) Put the AFG into “enable” mode by holding up the “enable” switch while sweeping across with the “stage no” switch. Take pulses from stages 9 and 15, for instance, of the sequencer and patch into the AFG “start” jacks. If the AFG has an internal rate faster than the sequencer, for instance .02 vs. .5, then the result will be a rhythmic ornament. Different ornamental rates can be set for each of the AFG’s: they will always track each other except when receiving the “start” pulse.

Additional Diagram 8 : Rhythmic Improvisation example 2

Rhythmic functions like the pulse output series can be freely programmed in and out while the AFG is in “display,” or via the “stage no” switch. I find that if I sweep the “stage no” through the 16 stages of the AFG, I am able to “pick off” any stage on which I might want to program a pulse — this can even be done with one hand — or a “sust” or “enable.”

I might also add that the “sloped” function of the AFG is very handy in percussive passages for introducing a tabla-like pitched drum quality, whether in “external” or “internal” modes.

Additional Diagram 8 : "Complete" Performance patch

The following diagram extends the Basic Performance Patch to a complete setup allowing to perform all techniques and transitions mentioned in this document.

One could assume the interest of this document would stop at its historical value, given how rare the instruments involved have become. Yet in recent years I have observed scanned versions of the 1976 grant circulating out of universities circle into electronic music communities. While many of the Buchla modules required are now replicated, I don't think it is enough to explains this renewed interest.

Live electronic music was a genuinely complex task in 1976. It has since become common, thanks to affordable, stable technology and shared synchronization standards. This empowerment came with a highly automated ecosystem in which performers negotiate their own degree of freedom. The practice described by Suzanne Ciani is live-generated electronic music, which has now found new life in the modular synthesis renaissance, reaching audience that seems increasingly drawn to it after years of automated performances. It is no wonder that this document inspires a new generation of performers with years-ahead answers to questions on how to organize and improvise live-generated music, how to build a patch and practice it as a musical instrument.

During my first collaboration with Suzanne Ciani, I replicated the Basic Performance Patch on VCV Rack software. While applying the guidelines on transitioning from one idea to another (video linked here), I realized the nature of each musical idea was in fact defined by the intent to transition between them in front of an audience, and these metamorphoses were the blueprint of a narrative structure within a live performance.

This is why we would like to propose translations of these musical ideas into modern tools, for anyone to explore and extend. Many of these ideas emerge from combinations of Buchla modules. Transitions depend on features specific to the 248 and would demand a patch too convoluted to remain instructive. We therefore decided to isolate the musical idea on its own, for a better adaptation to the expandable software ecosystem. The following videos treat each idea within VCV Rack 2, a free, open-source platform inspired by the Eurorack paradigm, using open-source third-party modules from the VCV Rack library. The patch files are available to download.

The following patches use a recurring structure revolving around the Sickozell 16-stage 8-track sequencer. Each track has independent reading modes and clock sources. The 4 lower rows of the sequencer behave exactly like the Buchla 246 sequencer, which holds the 4 sequences read in a linear way. The 4 top rows replace the MARF, with varying roles depending on the patch. In many cases, two of them control 2 sequential switches distributing the 4 sequences to the two main voices, to reproduce the behavior of the MARF's external inputs. Any binary data from the MARF are reproduced with the sequences' min and max knob values. Unlike the MARF, the Sickozell sequencer doesn't have multiple playheads. For the sake of exercise, the sequences are duplicated to reach the same result. Readers are encouraged to pass over this fictional limitation with creativity.

A16-step sequencer is used to replicate the "pulses2" section of the MARF, advancing the sequencer.

The sequencer can be replaced by a keyboard played by the user, taking the MIDI to CV module V/oct output as source and the gate output as trigger.

The four channels are rendered binaurally. Please use headphones.Equipped readers can route the four outputs to a quadraphonic system through the AUDIO 8 module for the intended result.

This gallery shows copies of the original hand-drawn diagrams and musical illustration provided with the 1976 grant.

this gallery shows pictures of original Buchla 200 modules involved in the making of the Basic Performance Patch.

With gratitude to Ryan Gaston and Rick Smith of the Buchla Archives, Gur Milstein and Piero Fragola of Tiptop Audio, Rachel Aiello, and Suzanne Ciani, all of whom gave their time and knowledge generously.

https://doi.org/10.47041/OSNP9356

ECHO journal by Orpheus Instituut uses cookies to optimise your user experience. By clicking on 'I agree' or by continuing to use this website, you agree to the placing of these cookies. More information


Source: Hacker News

English: A vs. An

Blog post:
16 Sep 2026

In English, there is an “indefinite” article a that can go before a word. For example, a raccoon. But for some words, we use an. For example, an apple.

When procedurally generating text, I want a function
a_or_an("apple") that tells me which article to use. That seems
like it’d be easy. We can check the first letter to see if it’s a
vowel. But that would mean we output an unicorn, not a unicorn.

The actual rule is not whether the written word starts with a
vowel letter, but whether the spoken word starts with a vowel
sound. The word <unicorn> starts with vowel letter (<u>) but a
consonant sound (cmudict Y, ipa /j/). The word <hour> starts with a consonant letter (<h>) but a vowel sound (cmudict AW, ipa /aʊ/).

Tree style visualization of the first two letters of a word
Visualization showing whether the first two letters of a word are enough to determine whether it should have “a” or “an”

I was curious how often these exceptions occurred, and whether they can be grouped together, so I spent a day looking at the data and building some visualizations and wrote up the results.
I was surprised that only 129 of the 32,455 words in my list needed exceptions.

[LLM note: I did not use LLMs to write any of this code, but in hindsight, I should have. This is one-off code to answer a question. It doesn’t need to be clean or maintainable. It only needs to be correct. I would’ve spent more time on the trie simplification algorithm and less time on parsing cmudict and re-learning d3.js.]


Source: Hacker News