Abstract:Rasterization is the process of determining the color of every pixel drawn by an application. Powerful rasterization libraries like Skia, CoreGraphics, and Direct2D put exceptional effort into drawing, blending, and rendering efficiently. Yet applications are still hindered by the inefficient sequences of operations that they ask these libraries to perform. Even Google Chrome, a highly optimized program co-developed with the Skia rasterization library, still produces inefficient instruction sequences even on the top 100 most visited websites. The underlying reason for this inefficiency is that rasterization libraries have complex semantics and opaque and non-obvious execution models.
To address this issue, we introduce $mu$Skia, a formal semantics for the Skia 2D graphics library, and mechanize this semantics in Lean. $mu$Skia covers language and graphics features like canvas state, the layer stack, blending, and color filters, and the semantics itself is split into three strata to separate concerns and enable extensibility. We then identify four patterns of sub-optimal Skia code produced by Google Chrome, and then write replacements for each pattern. $mu$Skia allows us to verify the replacements are correct, including identifying numerous tricky side conditions. We then develop a high-performance Skia optimizer that applies these patterns to speed up rasterization. On 99 Skia programs gathered from the top 100 websites, this optimizer yields a speedup of 18.7% over Skia’s most modern GPU backend, while taking at most 32 $mu$s for optimization. The speedups persist across a variety of websites, Skia backends, and GPUs. To provide true, end-to-end verification, optimization traces produced by the optimizer are loaded back into the $mu$Skia semantics and translation validated in Lean.
arXivLabs: experimental projects with community collaborators
arXivLabs is a framework that allows collaborators to develop and share new arXiv features directly on our website.
Both individuals and organizations that work with arXivLabs have embraced and accepted our values of openness, community, excellence, and user data privacy. arXiv is committed to these values and only works with partners that adhere to them.
For a long time, running NumPy in the browser meant running it without an accelerated BLAS. Matrix multiplications fell back to plain loops (portable, but blind to cache and SIMD).
That just changed. The Emscripten-forge NumPy package now links OpenBLAS in WebAssembly, and at n = 1024 square np.matmul jumps to about 30.92× faster (float32) and 14.90× faster (float64). The next OpenBLAS release, already available as an experimental package on Emscripten-forge, with kernels contributed by QuantStack, pushes it further, and an optional Relaxed SIMD build adds another step on engines that support it.
Emscripten-forge is a software distribution for WebAssembly. Together with conda-forge, it rebuilds the conda ecosystem for WebAssembly, so compilers, runtimes, and shared libraries ship as redistributable conda packages with a coherent ABI (not Python wheels, not R packages, but native libraries that any language ecosystem can link).
Bringing a scientific language to the browser is hard enough that, so far, it has mostly happened one language at a time. Pyodide pioneered it for Python. Later on, WebR did it for R, on the same premise. Each is a self-contained, language-specific distribution. Emscripten-forge takes a different shape: a language-agnostic distribution. It builds on the foundational work of the Pyodide and WebR projects, and goes further, covering not only Python and R, but also C++, OCaml, Lua, compiler toolchains, and many more tools (and shipping with a package manager).
Fortran sits at the core of foundational scientific packages: LAPACK, historically much of SciPy (although this is changing as SciPy has made strides to become Fortran-free), and R’s compiled statistical routines are all Fortran underneath. Bringing any of them to WebAssembly therefore means bringing a Fortran compiler that can target wasm32.
For a while, Pyodide worked around the absence of such a compiler: its SciPy build was produced with f2c, a Fortran-to-C translator, so the Fortran source was transpiled to C and compiled with the existing Emscripten toolchain. That workaround enabled SciPy to run in the browser, but it was not enough for R, whose distribution could not sidestep a real Fortran compiler. That constraint is what started the work on Flang (LLVM’s Fortran frontend) for WebAssembly, in the context of bringing R to the browser on Emscripten-forge.
OpenBLAS is a widely used, optimized implementation of BLAS (Basic Linear Algebra Subprograms). BLAS is organized in three levels: Level 1 covers vector–vector operations (for example AXPY and dot products); Level 2 covers matrix–vector operations (for example GEMV, as in A @ x); Level 3 covers matrix–matrix operations (for example GEMM, as in np.matmul), which dominate large dense linear algebra. OpenBLAS also ships LAPACK (Linear Algebra PACKage): higher-level routines for solving linear systems, factorizations, and eigenproblems, and most np.linalg calls ultimately delegate to those LAPACK entry points.
But even with a working Flang, the toolchain alone was not enough to bring OpenBLAS to the browser. The first OpenBLAS and LAPACK builds could not be used immediately: WebAssembly enforces stricter calling conventions than native targets, and additional patches were needed to make the library compile, archive, and link under Emscripten. Ian Thomas adapted OpenBLAS for Flang and Emscripten; those patches live in the Emscripten-forge OpenBLAS recipe (the bridge between upstream OpenBLAS and the NumPy builds measured in this post).
The rest of this post walks the last mile: what changed when NumPy could finally call BLAS, and what OpenBLAS 0.3.34 and the upcoming 0.3.35 deliver.
The final step was linking NumPy to an accelerated BLAS. The previous Emscripten-forge NumPy package (2.5.2 on emscripten-forge-4x) shipped without OpenBLAS, so np.matmul, @, and np.linalg fell back to portable C loops: naive implementations blind to cache hierarchy and SIMD. Matrix products spent most of their time on memory traffic rather than arithmetic. This is our no-BLAS baseline.
As of emscripten-forge/recipes#6310, the default NumPy on emscripten-forge-4x (2.5.3, build 3) links OpenBLAS 0.3.34 with WASM SIMD (TARGET=WASM128_GENERIC). This is now a stable, main-channel release. Calls to np.matmul, @, and np.linalg.solve now dispatch to the accelerated BLAS in WebAssembly.
The packaging model is what makes this powerful. Emscripten-forge is, in effect, a conda-forge for WebAssembly: packages are built from recipes, published on conda channels, and installed with a package manager under a shared ABI: the same workflow as on linux-64, but targeting emscripten-wasm32. On that model, OpenBLAS is a separate conda package. NumPy dynamically links libopenblas at runtime, so you can upgrade OpenBLAS without rebuilding NumPy. This benefits the entire ecosystem: Scientific Python projects like SciPy and scikit-learn, as well as non-Python stacks such as xtensor-blas, all share the same library. PyPI NumPy wheels, by contrast, vendor a BLAS snapshot at build time. The same NumPy 2.5.3 package will thus automatically use OpenBLAS 0.3.35 once it’s published.
Relative to the same Emscripten-forge stack without a BLAS implementation, square np.matmul at n = 1024 reaches about 30.92× (float32) and 14.90× (float64) (28.0 / 14.6 GFLOPS versus 0.90 / 0.98 GFLOPS). Full size grids and a single-thread linux-64 reference are in Appendix F; focused graphs and tables for this comparison are in Appendix B.
Geometric mean over both dtypes and the size grid (OpenBLAS 0.3.34 time in the denominator). Matrix products benefit most. Some np.linalg.* APIs see smaller gains (1.08–1.65× versus no BLAS) because they delegate to LAPACK, whose implementation in OpenBLAS is not yet optimized or specialized for WebAssembly. A @ x and vector np.dot remain near 1×: OpenBLAS 0.3.34 does not provide a fast column-major GEMV for that layout. OpenBLAS 0.3.35 adds that kernel.
Without BLAS, np.matmul throughput decreases with n (naive GEMM, cache misses). With OpenBLAS 0.3.34 it increases with n. Operations implemented on top of GEMM (@, two-dimensional np.dot, np.tensordot, np.linalg.multi_dot) follow the same trend. Speedup versus n and the associated numbers are in Appendix B.
On np.linalg at n = 1024 (float32), median times drop by about 1.2–2.1× versus no BLAS (solve 2.11×, cholesky 1.88×, qr 2.03×, inv 1.66×, eigh 1.60×, svd 1.21×; float64 agrees to within a few percent). For matrix–vector products, x @ A already uses a Level-2 kernel in 0.3.34 (14.86× at float32, n = 1024), while A @ x stays near the no-BLAS ~4 GFLOPS (1.02×).
The next OpenBLAS release includes WASM SIMD work already on develop. The numbers below use the openblas-experimental packages published by emscripten-forge/recipes#6761 (0.3.35.dev0, develop @ 539bb47, still TARGET=WASM128_GENERIC): portable simd128_hbf81ecf_3 (default) and opt-in relaxed_simd_h13a9a80_3. WebAssembly Relaxed SIMD is an engine extension that allows slightly looser floating-point semantics (notably fused multiply-add) in exchange for faster vector math; OpenBLAS can use those opcodes when the build enables them. Unless noted, 0.3.35 in this post means the portable SIMD128 build.
QuantStack contributed the WASM SIMD kernels upstream to OpenBLAS (Julien Jerphanion, Matthias Meschede), with review and integration by Martin Kroeker. That work covers Level-3 GEMM/TRMM, Level-1/2 AXPY and GEMV, numerical CBLAS tests for Node/Emscripten, and the optional Relaxed SIMD path. Portable SIMD128 remains the default: Relaxed SIMD FMA stays off unless you opt into the relaxed_simd build. The headline float32 GEMM step from 0.3.34 is an 8×4 microkernel; the optional Relaxed SIMD variant is covered in the next subsection.
Versus WASM OpenBLAS 0.3.34 at n = 1024, np.matmul improves by 1.79× (float32, 28.0 → 50.0 GFLOPS) and 1.41× (float64, 14.6 → 20.5 GFLOPS). Graphs and numbers for this comparison are in Appendix C; the complete grid is in Appendix F.
Geometric mean over both dtypes and the size grid (OpenBLAS 0.3.35 time in the denominator). The largest relative gains versus WASM 0.3.34 are not only in GEMM: A @ x jumps from the no-BLAS ~4 GFLOPS to 23.1 GFLOPS (float32, n = 1024) via the GEMV kernels (5.52× versus 0.3.34; x @ A is 1.73×). Vector np.dot improves similarly. Square np.matmul is 1.58× in geometric mean (and 1.79× at n = 1024float32 from the 8×4 SGEMM). On np.linalg at n = 1024float32, median times improve by about 1.3–1.9× versus 0.3.34 (solve 1.38×, cholesky 1.32×, qr 1.49×, inv 1.33×, eigh 1.64×, svd 1.90×).
Engines that implement WebAssembly Relaxed SIMD can load the relaxed_simd OpenBLAS build (WASM_RELAXED_SIMD=1), which uses FMA-style v_muladd from #6001 / #6020. On Chromium 153 in this bench, that is another 1.17× (float32) and 1.43× (float64) on np.matmul at n = 1024 versus portable 0.3.35 (50.0 → 58.7 GFLOPS and 20.5 → 29.4 GFLOPS). Geometric-mean gains versus SIMD128 are largest on matrix products (~1.3×); Level-2 and most of np.linalg move by about 1.0–1.2×. Graphs and numbers for this comparison are in Appendix D.
Chrome ≥114 and Firefox ≥146 expose the feature; Safari needs the JavaScriptCore flag useWebAssemblyRelaxedSIMD or the module fails to instantiate. The portable simd128 package remains the default for that reason (emscripten-forge/recipes#6761 down-prioritizes the Relaxed SIMD variant). Current engine support is tracked at webassembly.org/features.
Putting the steps together (linking OpenBLAS 0.3.34, then picking up the 0.3.35 SIMD128 kernels, then optionally Relaxed SIMD) is the speedup path from the previous no-BLAS Emscripten-forge NumPy.
Geometric mean over both dtypes and the size grid (no-BLAS time in the numerator). Each API shows three bars: OpenBLAS 0.3.34, OpenBLAS 0.3.35 (SIMD128), and OpenBLAS 0.3.35 (Relaxed SIMD). Matrix products gain the most; Level-2 A @ x and vector np.dot finally move once the 0.3.35 GEMV kernels land; np.linalg.* sits in a smaller but still clear band above 1×, limited by LAPACK routines that are not yet WASM-specialized in OpenBLAS. NumPy as published on Emscripten-forge already delivers the OpenBLAS 0.3.34 half of that path; portable 0.3.35 (simd128_hbf81ecf_3 from emscripten-forge/recipes#6761) is on the experimental channel today, with the optional Relaxed SIMD build (relaxed_simd_h13a9a80_3) for supporting engines. End-to-end np.matmul at n = 1024 reaches about 64.89× (float32) and 30.07× (float64) versus no BLAS with Relaxed SIMD. Speedup versus n for this end-to-end comparison is in Appendix E; the complete size grid, including linux-64, is in Appendix F.
NumPy linked against OpenBLAS is on the main emscripten-forge-4x channel (as of emscripten-forge/recipes#6310). No experimental channel is required for that combination: install numpy and it pulls in OpenBLAS 0.3.34.
OpenBLAS 0.3.35 (0.3.35.dev0) is on emscripten-forge-4x-experimental as the dual-variant packages from emscripten-forge/recipes#6761 (openblas-0.3.35.dev0-simd128_hbf81ecf_3 and openblas-0.3.35.dev0-relaxed_simd_h13a9a80_3). Add the experimental channel when you want the newer OpenBLAS without rebuilding NumPy, and pin the build string explicitly if you need Relaxed SIMD:
The portable simd128 default does not require WebAssembly Relaxed SIMD. The relaxed_simd package does: Chrome ≥114 and Firefox ≥146 work; Safari needs the JavaScriptCore flag useWebAssemblyRelaxedSIMD or the environment fails to load.
NumPy on Emscripten-forge can now call an accelerated BLAS in WebAssembly: linking OpenBLAS 0.3.34 already delivers large gains on matrix products and np.linalg, and the upcoming 0.3.35 kernels (with an optional Relaxed SIMD build) push further. Because that work landed upstream in OpenBLAS and as redistributable conda packages, the same improvements can benefit other WebAssembly Python stacks, including Pyodide, when they adopt an OpenBLAS build and the Fortran toolchain pieces from Emscripten-forge.
Julien Jerphanion (QuantStack) contributed the WebAssembly kernels upstream to OpenBLAS, designed and ran the benchmarks in this post, added numerical tests upstream, and packaged and tested NumPy and SciPy in the Emscripten-forge OpenBLAS recipe.
Matthias Meschede (QuantStack) contributed to OpenBLAS to ensure that the WebAssembly kernels were indeed used, and provided help with package management.
Ian Thomas (QuantStack) authored the initial patches to OpenBLAS that enabled its use by SciPy and other Emscripten-forge packages, some of which may be upstreamed into the OpenBLAS project.
Appendix E: All changes: OpenBLAS 0.3.35 (Relaxed SIMD) versus no BLAS
End-to-end speedup from the no-BLAS Emscripten-forge NumPy baseline to OpenBLAS 0.3.35 with Relaxed SIMD (the full path: linking OpenBLAS, portable 0.3.35 kernels, then Relaxed SIMD).
Appendix F: Full benchmark results (including linux-64)
Absolute throughput and speedups for OpenBLAS 0.3.34, OpenBLAS 0.3.35 (SIMD128), the optional 0.3.35 Relaxed SIMD build, and a single-thread conda-forge linux-64 OpenBLAS 0.3.34 reference on the same machine. Speedup is baseline time divided by featured time (>1 means the featured stack is faster).
Sensitive UK police data vulnerable to ‘compromise’ by US government and foreign actors
Exclusive: Official UK security assessment found Microsoft cloud platform storing files was at potential risk from hostile hackers
Vast troves of highly sensitive police data are lying on Microsoft cloud platforms which an official UK security assessment deemed to be vulnerable to “compromise” by foreign actors and the US government, a Guardian investigation can reveal.
The files include criminal records, victim statements, internal emails and sensitive information held by more than 40 police forces across the UK.
Some files exceed “official” classification, according to a policedocument seen by the Guardian, raising the possibility the information could be classed as “secret” or “top secret”.
The cloud platform is Microsoft Azure, one of the main commercial offerings of the US tech company. It is used by businesses and governments globally and rests on a web of IT infrastructure – datacentres, networking gear, fibre optic cables – that spans more than 100 countries.
In recent years, doubts have surfaced about how cloud platforms store data and whether they are truly secure.
British police decided to put some of their most sensitive data on the Microsoft platform in a 2017 meeting, a record of which was examined by the Guardian.
In doing so, officers accepted that “US government insiders” would be able to see the data, and that it could be “transmitted worldwide”, with “the extent of this … unknown”.
According to five specialists who reviewed the Guardian’s findings, the risks identified in that document persist today. Almost every UK police force now depends on Microsoft Azure, and the UK government spends at least £1.9bn on Microsoft software each year.
“There’s no evidence that this has been properly understood,” said one source who has held senior roles in UK policing. The data is “some of the most sensitive that exists”, he added. “You’re talking about information that, if it gets into the wrong hands, or if the information is incorrect, [means] people can get hurt or may die.”
When the Guardian approached the police about the possibility that sensitive information was not secure, they appeared to wave aside these risks, saying Britain’s contracts with Microsoft meant US authorities could not view data without express permission and that the data it stored on Microsoft remained in the UK.
These statements appeared to contradict public admissions by Microsoft, which said in a disclosure to Police Scotland in 2023 that data “can go outside the UK” and that it “cannot guarantee data sovereignty”.
Microsoft said it “does not provide any government with direct or unfettered access to customer data”, and that it had not provided UK data in response to a US government request. It added that, like all US-based tech companies, it responded to US government requests made through valid legal processes.
The threat of ‘US government insider attackers’
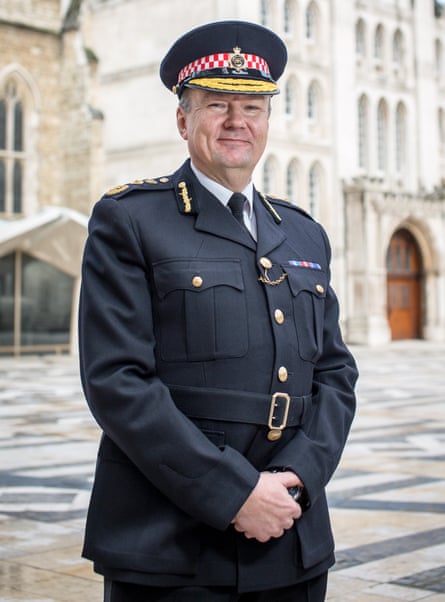
In 2017, a senior police officer, Ian Dyson, chaired a meeting in which stakeholders considered15 risks the UK would face if police forces decided to transfer their data to Microsoft’s global cloud.
Ian Dyson, pictured in 2016. Photograph: Jamie Smith
That meeting considered both the police’s use of Microsoft’s software, such as Office 365, and the reliance on the cloud that underpins these services, Azure. Those risks, and the resulting police decisions, were set out in a summary document seen by the Guardian and signed off by Dyson.
This was four years after the advent of a policy called “cloud first”. Introduced by the Cabinet Office in 2013, it became a government-wide effort to push almost all departments to migrate their data on to the “public cloud” – commercial offerings by tech companies, often based in the US. Departments that did not want to do this had to jump through burdensome administrative hoops.
Dyson was the police commissioner of the City of London at the time, but he held another title: senior information risk owner for all of Britain, or the SIRO. It was his job to set the norms for how British police could safely handle their data.
In their assessment, officers came to startling conclusions about what would happen if they put police data on Azure. Firstly, they considered it would be vulnerable to hackers: Microsoft’s software “carries vulnerabilities which will be exploited by cybercriminals and other threat actors in due course”.
Separately, it added: “Police forces cannot be certain where their data will be processed or stored.
“The hyper-scale and global nature of the Microsoft cloud means that police data, and metadata relating to police data could be transmitted and stored worldwide by Microsoft, and the extent of this will be unknown.”
The document specifically identified the potential risk from what it described as “US government insiders”. It said: “There is a risk of compromise of sensitive data shared by, or taken from, Microsoft by the US government being released by US government insider attackers.”
The document explained that the data intended for migration was sensitive. In fact, “a significant volume” of it exceeded the classification “official”. In the UK, this suggests it was either “official sensitive”, “secret”, or “top secret”.
The assessment also suggested Microsoft’s platform was unable to guarantee this data would be secure. “This places sensitive data, inadequately protected in an environment which then becomes a significantly more attractive target for attackers,” it said.
As well as risks, the report also listed mitigations. On the problem of cyber-attacks, it mandated that police servers should be repaired promptly, kept up to date and have antivirus software.
To address the risk of “US government insiders” and the concern that Microsoft might store UK policing data “worldwide” it suggested “applying Microsoft’s ‘out-of-the-box’ native encryption” and leaving the final decision about using Microsoft up to individual police chiefs.
Several experts interviewed by the Guardian, including cloud computing specialists and engineers working for Microsoft, suggested these mitigations were inadequate. Microsoft’s internal encryption does not prevent its employees accessing UK police data; nor would it stop the US government obtaining British policing files.
The National Police Chief’s Council (NPCC) said access to data stored on the cloud is limited to those with a genuine need to access it and that this is subject to strict controls. Despite that claim, a Microsoft engineer who reviewed the Guardian’s findings said the information “could be viewed by hundreds of people around the world, some of them not vetted, many of them not directly employed by Microsoft”.
Despite the risks identified by the assessment, every police force in the UK put its data, wholly or in part, on Microsoft’s cloud. Some began migrating their information in 2017. A few forces, such as Police Scotland, are still finalising their adoption of the technology.
The files cover the “full gamut of data: intelligence, body-worn video, digital evidence and case files, as well as the non-law enforcement data any organisation has”, said the source who held senior roles in UK policing.
‘We do not expect any sharing … without permission’
The UK government spends billions each year on services offered by three US tech companies: Amazon, Google and Microsoft.
Up to 60% of its IT infrastructure is hosted on cloud platforms. Britain’s intelligence data is hosted on Amazon’s cloud services, as is its customs data. The Ministry of Defence uses Azure. There is “a deep dependency on US hyperscalers”, said Dave Michels, a researcher with the Cloud Legal Project, at Queen Mary University of London.
This is the result of 13 years of decisions like Dyson’s. It is unclear if the potential consequences are broadly understood.
When the Guardian approached the NPCC over the document signed by Dyson, it said: “UK policing as standard requires the use of UK-only datacentres,” but added that “on occasion” Microsoft employees could access the data “to provide support”.
Asked whether the US government could access the data, a police spokesperson said they could not comment on the phrase “US government insiders”, because “terminology … changes continuously” and the document was “outdated”.
“In line with the contract signed with Microsoft, we do not expect any sharing with the US government without the express permission of the UK government,” they added.
Microsoft said: “The suggestion that use of Microsoft cloud services means customer data is inherently insecure or automatically exposed to foreign governments is inaccurate.” It said it had “never provided UK government data in response to any US or global authority request”.
Two legal experts, as well as several Microsoft engineers who spoke anonymously to the Guardian, suggested these assertions did not give an accurate picture of the potential risks.
By default, Microsoft’s cloud was “a global network of datacentres”, said Michels. It had facilities on every continent and this meant, generally, that data stored on it was stored everywhere: pieces of a single file could be held across multiple countries, from Sweden to Ethiopia.
In recent years, Michels said, Microsoft had begun to offer clients in Europe greater assurances about where their data was stored, including assuring some customers that their data would remain within EU borders. But “the focus on data location is a bit of a red herring”, he said.
This was because thousands of engineers from more than 100 countries maintained Microsoft’s systems. Some were directly employed by Microsoft, others worked for subcontractors in countries potentially hostile to the UK, from Israel to Egypt, China and Kazakhstan. “You’ve seen the list of their sub-processors of people who have access to customer data,” said Michels. “It’s a long list.”
Some of the engineers could access data, such as UK police data, directly as part of customer support. Many more could see key features of what the data included.
A Microsoft datacentre in the Netherlands. Photograph: Ramon van Flymen/EPA
Microsoft said it had “strong guardrails” around data access by engineers.
Douwe Korff, a professor of international law at London Metropolitan University, said the police statement that “we do not expect any sharing [of our data] with the US government” was “typical lawyers’ wriggling”.
“The risk is obvious, even though the providers of the cloud and the government both have an interest in talking it down,” he said.
Michels said: “As a cloud customer, if you’re relying on a contractual commitment from a cloud provider not to hand over data when forced to under foreign law, that is not worth much more than the piece of paper it’s written on.”
US law, including the Cloud Act, allows US authorities to access any data held by US cloud companies, including data held abroad. US authorities do not need a warrant to do this, and they can require US companies to not disclose such access to cloud customers.
Microsoft, Amazon and Google have insisted they would fight such requests, said Korff. But there is “nothing that is legally binding” that would prevent them from sharing other governments’ data if US authorities demanded it.
In response to a query from the Guardian, Microsoft said it “has never provided UK government data in response to any US or global authority request”. It added in a follow-up that it was bound by its “contractual commitments”.
“If UK law prohibits us from turning over data to another government, that is a binding law that would govern our response to any hypothetical demand,” it said.
‘The security guys expected a big breach by now’
The Guardian spoke to six people who have closely followed the country’s data storage arrangements over the past decade. Several of them said that senior leaders did not view dependence on US tech companies as a concern, and trusted them not to give data to US authorities.
“Government security departments are painfully aware of all the risks,” said Mark Butcher, a cloud expert who acts as a strategic adviser across government. “But the way that most senior leaders talk about it is: ‘Well, we’ve been reassured by Microsoft that it would never happen.’”
But the source who has held senior policing roles said: “All the security guys I worked with when this policy came in expected a big breach by now, and we know it will take that to change the police’s position.
“The truth is, however, the level of logging and information in the cloud systems would not necessarily tell us if there was a problem. We really don’t know if the data has been breached or not.”
An experiment to design a cute PCB (without touching any tools) in plain English
hardwarepcbkicadaiclaude 8 min
The board I will be journaling about.
I have been wanting to design a simple PCB for the last couple of years now. The thought of converting a design idea into a physical board and programming it to do things is fascinating to me. Long story short, I procrastinated until I tried to vibe-generate a dead simple PCB with Claude Opus 4.8 and it was terrible ! It had no idea about the orientation of the components, it did not do any proper routing. I was disappointed and accepted the fact that these tools were not there yet.
Then arrived the Fable 5. At first I was not that hopeful. One Thursday evening, around 10 hours before my weekly reset for Claude, I decided to give it another try; this time with Fable 5.
I had two rules:
No manual edits or verification of the board.
Every problem I face before manufacturing will be solved by Fable.
This meant I was going to trust Fable with my wallet. I decided to describe the board I want it to generate, and I was not going to be involved in the design phase. I was the end customer.
This is the prompt I gave it:
That was it, a short description of a RPI 2350 based development board which can drive an E-ink display. After working autonomously for a couple of hours it came up with the design shown in the video below.
<!– YOUTUBE: when the video is up, replace this
Everything else in this figure — the frame, the caption — stays. –>
The board as it freshly came out of Kicad ⃰.
Board
31.8 × 37.32 mm, 4 layer
MCU
RP2350A
Display
1.54″ E-ink, 200×200
Flash
8 MB QSPI
Cost
26€ per board
A closer look to some errors
The design process was not error free of course. When I showed the initial design (Claude was still working on it) of the PCB to my colleague, the first thing he wanted me to check (after recovering from the pain of seeing them tracks) was the DRC (Design Rule Checking) errors. I did not know what it was, and when we looked at it, there were indeed 65 DRC errors. Following the rule, I only mentioned the errors to Fable and did nothing else.
Front: Beautiful placement, with two mistakesBack: horrendous tracks
Fable was amazing at component selection, except for the two components I highlighted above. The big one on the top left is the SPI flash which stores the firmware and other data that you want to save. The SPI flash memory Claude chose was W25Q128JVS. It comes with the SOIC-8 wide package, but the pads designed for the memory was for a SOP-8 package, meaning the chip is too big for the pads. The bottom left component on the other hand is the transistor that switches the boost converter for the E-ink driver circuitry. As you can see it also chose the wrong package, as it is too small for the pads. I did not realise these until I uploaded the required files to JLCPCB. There I could see the issues, and I discussed it with Claude. For the W25Q128JVS it insisted that there was a SOP-8 package but I could not find it in LCSC’s library. Eventually we settled at the P25Q64SH chip.
But wait a minute, how did it even route ?
The design had 65 footprints, 54 nets and 118 unconnected lines. It is not a complex PCB by any means :P. Fable decided to use the Freerouting open-source project. The tool worked for 2 minutes, and after seventeen passes it plateaued at sixty nine connections, leaving 49 disconnected, and it could not finish the job. The remaining connections were hand-routed by Claude.
Freerouting doing its job
After I ordered the board my colleague mentioned to me the KiCadRoutingTools open-source project. It ran for 1.25 seconds and it could route all the connections with no problem. I will try this tool out for my upcoming hardware projects.
Same placement, two routers
Ordering with JLCPCB
I had never ordered anything from a PCB manufacturer before. It seemed complex and I was reluctant to take the first step. Upon Claude’s compilation of the project, I asked it to prepare the required files for JLCPCB, and tell me what to select on their GUI. Man am I satisfied with JLCPCB. It was so straight forward, easy to interact with and there was no bloat. I uploaded the files, some components Claude selected were not available, we did a back and forth and voila we were done. For five fully assembled boards I paid 130 Euros, ordered the E-ink displays from a local shop and now it was the waiting game.
Some cool animations while we are waiting for the PCBs
The four layers, pulled apart.Assembly of our board
The boards have arrived !!!
I received the PCBs and the first thing I wanted to do was to plug it in to my laptop. I have broken multiple USB modules for my Framework earlier, hence I thought checking for a short between 3v3 and ground was a no-brainer, although my colleague was suggesting me to just yeet it since this was a fully vibe-generated board. There was no short and I just plugged it in. There it was, the board was recognized and it was ready to be used.
What do I do with it ?
I already wrote some proof-of-concept apps, and they worked perfectly fine. I can read on that beautiful 1.54 inch display 😀 Stopwatch is quite handy if i need some focusing, and the album is my favourite feature since even after powering the board off, the images stay on the display thanks to E-ink.
The watch face. The menu. Two buttons used for up and down, and the other two used for select and back.The e-reader. You can read .txt files stored on the SPI flash.The album. Pictures dithered to one bit.
Hands on with the finished board.
How do I feel all about this ?
Great and meh. I love how I was able to just describe the board I want in plain English, send the files overseas and then receive a fully functional board without knowing any proper PCB design knowledge. The possibilities are limitless here, and I will certainly continue doing this in the future.
That said, I was not feeling much of an accomplishment, rightfully so. I used to enjoy the learning and the struggle that came with it. Although we are in the best era to learn about something, the fact that you can make things without knowing anything about a subject puts you in an uncomfortable spot.
The future I wish to have
Yes it does suck that the joy we had while building has been sucked out of us and now we are told to enjoy building from a higher abstraction level. I am trying to adjust to this, especially at work. At work I can’t just YOLO stuff so I meticulously review all the time. It is tiring but knowing the fact that my input still matters, is rewarding. For my hobby projects tho, I will continue to YOLO it and build stuff fast without necessarily knowing about the details.
I hope one day JLCPCB or PCBWAY will have a chat-box where I can dump all my ideas and some of my illustrations, and two days later they will ship me the board. I want them to remove the middle man, and make PCB generation so much simpler and safer.
Sneak Peek
I already started working on my next project. Using Fable 5.1 with KiCAD and KiCADRoutingTools I am building an NVIDIA Jetson Orin Nano based tablet. The same rules I mentioned earlier will apply and I will let you know about the results(if I get to order it :P) .
NVIDIA Jetson Orin Nano based Tablet
Thank you for reading my journal, sharing is the most fun part of tinkering and building. I appreciate that you are part of this fun journey 🙂
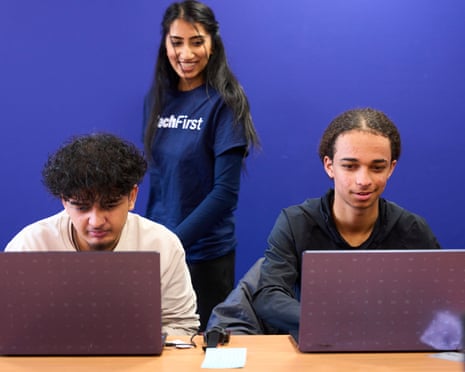
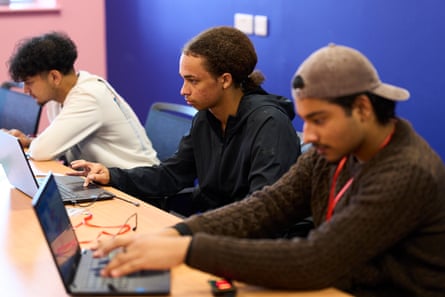
The course has ‘changed my opinion’ on AI, says Remy Simms, right, who is interested in applying for the content creator apprenticeship. Photograph: Christopher Thomond/The Guardian
The course has ‘changed my opinion’ on AI, says Remy Simms, right, who is interested in applying for the content creator apprenticeship. Photograph: Christopher Thomond/The Guardian
‘Really helpful’: the AI bootcamps aimed at addressing UK youth unemployment
Pilot project in Preston comes with apprenticeship offer for Neets at end of three-week course
In a youth centre opposite Preston bus station, the UK government is trying to address two of the greatest challenges facing the national economy: AI and youth unemployment.
The hope is that one will solve – rather than cause – the other. In a room at the recently opened Vault, a community hub in the Lancashire city, an “AI bootcamp” is under way – part of a trial in the north-west to give 16- to 24-year-olds AI training.
The bootcamp tutor is standing in front of a video screen and guiding the five attenders sitting around a long table on laptops through a task designed to emphasise the importance of glitch-free data in AI models.
“Does that make sense?” he asks. The room nods.
The three-week pilot boot camps are open to 70 young people who are classified as Neet or at risk of becoming so. Photograph: Christopher Thomond/The Guardian
Everyone attending these sessions is either a 16- to 24-year-old not in education, employment or training – Neet, for short – or likely to join that bracket.
Youth unemployment is a problem in the UK. Nearly a million young people are Neet – just over one in 10 people in that age group. The advent of AI, either a threat or boon to the job market depending on your perspective, is now another factor to take into consideration when tackling the youth joblessness crisis.
Khudeija Rafique, who is attending the course, sees potential in the new tech. “It would be really helpful with whatever job I would like to go into,” the 18-year-old from Burnley says.
These taxpayer-funded bootcamps are a pilot scheme, open to 70 people who will undergo a three-week programme specially designed for Neets to learn how to build AI tools, understand how businesses use AI, and learn to use the technology responsibly. The retailer JD Sports, food company Heinz and IT firm Agilysys are among the partners offering AI apprenticeships specifically designed for the attenders to join at the end of the course.
There are two types of apprenticeship available: one for aspiring content creators to become AI marketing specialists, another to join IT helpdesks that need AI expertise. If a boot-camp trainee gets an apprenticeship, they will be going to an organisation that wants these skills and has an AI-focused role to fill.
‘This is an opportunity to bridge a gap, to improve productivity and bring AI into organisations,’ says Lauren Monks. Photograph: Christopher Thomond/The Guardian
“This is an opportunity to bridge a gap, to improve productivity and bring AI into organisations,” says Lauren Monks, an executive at IN4 Group, the company contracted to run the programme.
Amid general concerns about the availability of entry-level jobs and whether AI is stifling that market, being on top of the technology can be an advantage if you’re seeking your first job.
This is common advice from graduate recruiters, but experts say it can apply to Neets as well, depending on what sector of the economy they are joining.
Remy Simms, 17, is interested in applying for the content creator apprenticeship and says the Preston course has “changed my opinion” on AI. “It shows that you can work with AI and you don’t have to work against it,” he says. “I’ve got a better understanding of it and I know more about how it works.”
Remy Simms, 17, says the Preston course has given him a ‘better understanding’ of AI. Photograph: Christopher Thomond/The Guardian
Alan Milburn, a former Labour cabinet minister, warned in a recent report that the country was “at risk of a lost generation” without government action on the Neet crisis. Milburn’s prescription goes a lot further than AI bootcamps – he calls for reform of the welfare system, for instance – and his report points out that work programmes by successive governments have failed to answer the problem.
Concerns about AI’s impact on employment have focused on the graduate job market so far, not on school leavers and non-graduates, amid expectations that it will be able to do the “grunt work” associated with junior employees in areas such as banking, consulting and law.
The impact on non-graduate work was unclear, according to Dr Bouke Klein Teeselink, who is researching AI and the future of work at King’s College London.
“We don’t have really good insights into how AI affects the non-graduate market compared to the graduate market,” he says, but suggests this scheme could help answer the puzzle of getting more young people into the labour market.
The key test of the bootcamps and ensuing apprenticeships, Teeselink says, would be the thoroughness of the AI training and whether these newcomers made a real difference to their employers’ productivity. “I hope the policy will be rolled out in a way that allows the government to answer both those questions,” he says.
Hamid Muhammad-Asif, 16, says he would be happy with a content creator or IT helpdesk apprenticeship. Photograph: Christopher Thomond/The Guardian
So will the bootcamps make a difference to Neet numbers? Experts say there is no single cause of the crisis and any comprehensive solution must be multi-faceted.
Chris Goulden, the deputy chief executive of the Youth Futures Organisation, a non-profit that researches how to help young people find employment, says he does not believe AI is a driver of Neet numbers. The country still needs to increase the amount of apprenticeships it offers, and guide children who are not on a pathway to university into vocations, he says.
“Our sense is that AI is not driving the increase in Neets since the [Covid] pandemic,” he says. “It’s more to do with mental health issues and a general slowdown in the economy. But that’s not to be complacent, because AI is doing new things every day and it’s going to affect lots of jobs.”
Goulden says if the “first rung of the ladder” is being taken away by AI, it is logical to give young people a foothold in the technology. “Teaching young people to use AI is part of how we prepare them for the future,” he says.
In Preston, the bootcamp attenders are keen to take the next step.
Asked whether he wants the content creator or the IT helpdesk apprenticeship, 16-year-old Hamid Muhammad-Asif, from Blackburn, says: “I’m happy with both.”
The physicist, in his study of natural phenomena, has two methods of
making progress: (1) the method of experiment and observation, and (2)
the method of mathematical reasoning. The former is just the collection
of selected data; the latter enables one to infer results about
experiments that have not been performed. There is no logical reason
why the second method should be possible at all, but one has found in
practice that it does work and meets with reasonable success. This must
be ascribed to some mathematical quality in Nature, a quality which the
casual observer of Nature would not suspect, but which nevertheless
plays an important role in Nature's scheme.
One might describe the mathematical quality in Nature by saying that the
universe is so constituted that mathematics is a useful took in its
description. However, recent advances in physical science show that
this statement of the case is too trivial. The connection between
mathematics and the description of the universe goes far deeper than
this, and one can get an appreciation of it only from a thorough
examination of the various facts that make it up. The main aim of my
talk to you will be to give you such an appreciation. I propose to deal
with how the physicist's views on this subject have been gradually
modified by the succession of recent developments in physics, and then I
would like to make a little speculation about the future.
Let us take as our starting-point that scheme of physical science which
was generally accepted in the last century – the mechanistic scheme.
This considers the whole universe to be a dynamical system (of course an
extremely complicated dynamical system), subject to laws of motion which
are essentially of the Newtonian type. The role of mathematics in this
scheme is to represent the laws of motion by equations, and to obtain
solutions of the equations referring to observed conditions.
The dominating idea in this application of mathematics to physics is
that the equations representing the laws of motion should be of a simple
form. The whole success of the scheme is due to the fact that equations
of simple form do seem to work. The physicist is thus provided with a
principle of simplicity, which he can use as an instrument of research.
If he obtains, from some rough experiments, data which fit in roughly
with certain simple equations, he infers that if he performed the
experiments more accurately he would obtain data fitting in more
accurately with the equations. The method is much restricted, however,
since the principle of simplicity applies only to fundamental laws of
motion, not to natural phenomena in general. For example, rough
experiments about the relation between the pressure and volume of a gas
at a fixed temperature give results fitting in with a law of inverse
proportionality, but it would be wrong to infer that more accurate
experiments would confirm this law with greater accuracy, as one is here
dealing with a phenomenon which is not connected in any very direct way
with the fundamental laws of motion.
The discovery of the theory of relativity made it necessary to modify
the principle of simplicity. Presumably one of the fundamental laws of
motion is the law of gravitation which, according to Newton, is
represented by a very simple equation, but, according to Einstein,
needs the development of an elaborate technique before its equation can
even be written down. It is true that, from the standpoint of higher
mathematics, one can give reasons in favour of the view that Einstein's
law of gravitation is actually simpler than Newton's, but this involves
assigning a rather subtle meaning to simplicity, which largely spoils
the practical value of the principle of simplicity as an instrument of
research into the foundations of physics.
What makes the theory of relativity so acceptable to physicists in spite
of its going against the principle of simplicity is its great
mathematical beauty. This is a quality which cannot be defined, any
more than beauty in art can be defined, but which people who study
mathematics usually have no difficulty in appreciating. The theory of
relativity introduced mathematical beauty to an unprecedented extent
into the description of Nature. The restricted theory changed our ideas
of space and time in a way that may be summarised by stating that the
group of transformations to which the space-time continuum is subject
must be changed from the Galilean group to the Lorentz group. The
latter group is a much more beautiful thing than the former – in fact,
the former would be called mathematically a degenerate special case of
the latter. The general theory of relativity involved another step of a
rather similar character, although the increase in beauty this time is
usually considered to be not quite so great as with the restricted
theory, which results in the general theory being not quite so firmly
believed in as the restricted theory.
We now see that we have to change the principle of simplicity into a
principle of mathematical beauty. The research worker, in his efforts
to express the fundamental laws of Nature in mathematical form, should
strive mainly for mathematical beauty. He should still take simplicity
into consideration in a subordinate way to beauty. (For example
Einstein, in choosing a law of gravitation, took the simplest one
compatible with his space-time continuum, and was successful.). It
often happens that the requirements of simplicity and of beauty are the
same, but where they clash the latter must take precedence.
Let us pass on to the second revolution in physical thought of the
present century – the quantum theory. This is a theory of atomic
phenomena based on a mechanics of an essentially different type from
Newton's. The difference may be expressed concisely, but in a rather
abstract way, by saying that dynamical variables in quantum mechanics
are subject to an algebra in which the commutative axiom of
multiplication does not hold. Apart from this, there is an extremely
close formal analogy between quantum mechanics and the old mechanics.
In fact, it is remarkable how adaptable the old mechanics is to the
generalization of non-commutative algebra. All the elegant features of
the old mechanics can be carried over to the new mechanics, where they
reappear with an enhanced beauty.
Quantum mechanics requires the introduction into physical theory of a
vast new domain of pure mathematics – the whole domain connected with
non-commutative multiplication. This, coming on top of the introduction
of new geometries by the theory of relativity, indicates a trend which
we may expect to continue. We may expect that in the future further big
domains of pure mathematics will have to be brought in to deal with the
advances in fundamental physics.
Pure mathematics and physics are becoming ever more closely connected,
though their methods remain different. One may describe the situation
by saying that the mathematician plays a game in which he himself
invents the rules while the physicist plays a game in which the rules
are provided by Nature, but as time goes on it becomes increasingly
evident that the rules which the mathematician finds interesting are the
same as those which Nature has chosen. It is difficult to predict what
the result of all this will be. Possibly, the two subjects will
ultimately unify, every branch of pure mathematics then having its
physical application, its importance in physics being proportional to
its interest in mathematics. At present we are, of course, very far
from this stage, even with regard to some of the most elementary
questions. For example, only four-dimensional space is of importance in
physics, while spaces with other numbers of dimensions are of about
equal interest in mathematics.
It may well be, however, that this discrepancy is due to the
incompleteness of present-day knowledge, and that future developments
will show four-dimensional space to be of far greater mathematical
interest than all the others.
The trend of mathematics and physics towards unification provides the
physicist with a powerful new method of research into the foundations of
his subject, a method which has not yet been applied successfully, but
which I feel confident will prove its value in the future. The method
is to begin by choosing that branch of mathematics which one thinks will
form the basis of the new theory. One should be influenced very much in
this choice by considerations of mathematical beauty. It would probably
be a good thing also to give a preference to those branches of
mathematics that have an interesting group of transformations underlying
them, since transformations play an important role in modern physical
theory, both relativity and quantum theory seeming to show that
transformations are of more fundamental importance than equations.
Having decided on the branch of mathematics, one should proceed to
develop it along suitable lines, at the same time looking for that way
in which it appears to lend itself naturally to physical interpretation.
This method was used by Jordan in an attempt to get an improved quantum
theory on the basis of an algebra with non-associative multiplication.
The attempt was not successful, as one would rather expect, if one
considers that non-associative algebra is not a specially beautiful
branch of mathematics, and is not connected with an interesting
transformation theory. I would suggest, as a more hopeful-looking idea
for getting an improved quantum theory, that one take as basis the
theory of functions of a complex variable. This branch of mathematics
is of exceptional beauty, and further, the group of transformations in
the complex plane, is the same as the Lorentz group governing the
space-time of restricted relativity. One is thus led to suspect the
existence of some deep-lying connection between the theory of functions
of a complex variable and the space-time of restricted relativity, the
working out of which will be a difficult task for the future.
Let us now discuss the extent of the mathematical quality in Nature.
According to the mechanistic scheme of physics or to its relativistic
modification, one needs for the complete description of the universe not
merely a complete system of equations of motion, but also a complete set
of initial conditions, and it is only to the former of these that
mathematical theories apply. The latter are considered to be not
amenable to theoretical treatment and to be determinable only from
observation.
The enormous complexity of the universe is ascribed to an enormous
complexity in the initial conditions, which removes them beyond the
range of mathematical discussion.
I find this position very unsatisfactory philosophically, as it goes
against all ideas of the unity of Nature. Anyhow, if it is only to a
part of the description of the universe that mathematical theory
applies, this part ought certainly to be sharply distinguished from the
remainder. But in fact there does not seem to be any natural place in
which to draw the line. Are such things as the properties of the
elementary particles of physics, their masses and the numerical
coefficients occurring in their laws of force, subject to mathematical
theory? According to the narrow mechanistic view, they should be
counted as initial conditions and outside mathematical theory. However,
since the elementary particles all belong to one or other of a number of
definite types, the members of one type being all exactly similar, they
must be governed by mathematical law to some extent, and most physicists
now consider it to be quite a large extent. For example, Eddington has
been building up a theory to account for the masses. But even if one
supposed all the properties of the elementary particles to be
determinable by theory, one would still not know where to draw the line,
as one would be faced by the next question – Are the relative abundances
of the various chemical elements determinable by theory? One would pass
gradually from atomic to astronomic questions.
This unsatisfactory situation gets changed for the worse by the new
quantum mechanics. In spite of the great analogy between quantum
mechanics and the older mechanics with regard to their mathematical
formalisms, they differ drastically with regard to the nature of their
physical consequences. According to the older mechanics, the result of
any observation is determinate and can be calculated theoretically from
given initial conditions; but with quantum mechanics there is usually an
indeterminacy in the result of an observation, connected with the
possibility of occurrence of a quantum jump, and the most that can be
calculated theoretically is the probability of any particular result
being obtained. The question, which particular result will be obtained
in some particular case, lies outside the theory. This must not be
attributed to an incompleteness of the theory, but is essential for the
application of a formalism of the kind used by quantum mechanics.
Thus according to quantum mechanics we need, for a complete description
of the universe, not only the laws of motion and the initial conditions,
but also information about which quantum jump occurs in each case when a
quantum jump does occur. The latter information must be included,
together with the initial conditions, in that part of the description of
the universe outside mathematical theory.
The increase thus arising in the non-mathematical part of the
description of the universe provides a philosophical objection to
quantum mechanics, and is, I believe, the underlying reason why some
physicists still find it difficult to accept this mechanics. Quantum
mechanics should not be abandoned, however, firstly, because of its very
widespread and detailed agreement with experiment, and secondly, because
the indeterminacy it introduces into the results of observations is of a
kind which is philosophically satisfying, being readily ascribable to an
inescapable crudeness in the means of observation available for
small-scale experiments. The objection does show, all the same, that
the foundations of physics are still far from their final form.
We come now to the third great development of physical science of the
present century – the new cosmology. This will probably turn out to be
philosophically even more revolutionary than relativity or the quantum
theory, although at present one can hardly realize its full
implications. The starting-point is the observed red-shift in the
spectra of distance heavenly bodies, indicating that they are receding
from us with velocities proportional to their distances.* The
velocities of the more distant ones are so enormous that it is evident
we have here a fact of the utmost importance, not a temporary or local
condition, but something fundamental for our picture of the universe.
If we go backwards into the past we come to a time, about 2 x 10⁹ years
ago, when all the matter in the universe was concentrated in a very
small volume. It seems as though something like an explosion then took
place, the fragments of which we now observe still scattering outwards.
This picture has been elaborated by LemaÏtre, who considers the universe
to have started as a single very heavy atom, which underwent violent
radioactive disintegrations and so broke up into the present collection
of astronomical bodies, at the same time giving off the cosmic rays.
With this kind of cosmological picture one is led to suppose that there
was a beginning of time, and that it is meaningless to inquire into what
happened before then. One can get a rough idea of the geometrical
relationships this involves by imagining the present to be the surface
of a sphere, going into the past to be going in towards the centre of
the sphere, and going into the future to be going outwards. There is
then no limit to how far one may go into the future, but there is a
limit to how far one can go into the past, corresponding to when one has
reached the centre of the sphere. The beginning of time provides a
natural origin from which to measure the time of any event. The result
is usually called the epoch of that event. Thus the present epoch is 2
x 109 years.
Let us now return to dynamical questions. With the new cosmology the
universe must have been started off in some very simple way. What,
then, becomes of the initial conditions required by dynamical theory?
Plainly there cannot be any, or they must be trivial. We are left in a
situation which would be untenable with the old mechanics. If the
universe were simply the motion which follows from a given scheme of
equations of motion with trivial initial conditions, it could not
contain the complexity we observe. Quantum mechanics provides an escape
from the difficulty. It enables us to ascribe the complexity to the
quantum jumps, lying outside the scheme of equations of motion. The
quantum jumps now form the uncalculable part of natural phenomena, to
replace the initial conditions of the old mechanistic view.
One further point in connection with the new cosmology is worthy of
note. At the beginning of time the laws of Nature were probably very
different from what they are now. Thus we should consider the laws of
Nature as continually changing with the epoch, instead of as holding
uniformly throughout space-time. This idea was first put forward by
Milne, who worked it out on the assumptions that the universe at a given
epoch is roughly everywhere uniform and spherically symmetrical. I find
these assumptions not very satisfying, because the local departures from
uniformity are so great and are of such essential importance for our
world of life that it seems unlikely there should be a principle of
uniformity overlying them. Further, as we already have the laws of
Nature depending on the epoch, we should expect them also to depend on
position in space, in order to preserve the beautiful idea of the theory
of relativity there is fundamental similarity between space and time.
This goes more drastically against Milne's assumptions than a mere lack
of uniformity in the distribution of matter.
We have followed through the main course of the development of the
relation between mathematics and physics up to the present time, and
have reached a stage where it becomes interesting to indulge in
speculations about the future. There has always been an unsatisfactory
feature in the relation, namely, the limitation in the extent to which
mathematical theory applies to a description of the physical universe.
The part to which it does not apply has suffered an increase with the
arrival of quantum mechanics and a decrease with the arrival of the new
cosmology, but has always remained.
This feature is so unsatisfactory that I think it safe to predict it
will disappear in the future, in spite of the startling changes in our
ordinary ideas to which we should then be led. It would mean the
existence of a scheme in which the whole of the description of the
universe has its mathematical counterpart, and we must suppose that a
person with a complete knowledge of mathematics could deduce, not only
astronomical data, but also all the historical events that take place in
the world, even the most trivial ones. Of course, it must be beyond
human power actually to make these deductions, since life as we know it
would be impossible if one could calculate future events, but the
methods of making them would have to be well defined. The scheme could
not be subject to the principle of simplicity since it would have to be
extremely complicated, but it may well be subject to the principle of
mathematical beauty.
I would like to put forward a suggestion as to how such a scheme might
be realized. If we express the present epoch, 2 x 10⁹ years, in terms
of a unit of time defined by the atomic constants, we get a number of
the order 1039, which characterizes the present in an absolute sense.
Might it not be that all present events correspond to properties of this
large number, and, more generally, that the whole history of the
universe corresponds to properties of the whole sequence of natural
numbers? At first sight it would seem that the universe is far too
complex for such a correspondence to be possible. But I think this
objection cannot be maintained, since a number of the order 1039 is
excessively complicated, just because it is so enormous. We have a
brief way of writing it down, but this should not blind us to the fact
that it must have excessivly complicated properties.
There is thus a possibility that the ancient dream of philosophers to
connect all Nature with the properties of whole numbers will some day be
realized. To do so physics will have to develop a long way to establish
the details of how the correspondence is to be made. One hint for this
development seems pretty obvious, namely, the study of whole numbers in
modern mathematics is inextricably bound up with the theory of functions
of a complex variable, which theory we have already seen has a good
chance of forming the basis of the physics of the future. The working
out of this idea would lead to a connection between atomic theory and
cosmology.
* The recession velocities are not strictly proved, since one may
postulate some other cause for the spectral red-shift. However, the new
cause would presumably be equally drastic in its effect on cosmological
theory and would still need the introduction of a parameter of the order
2 x 10⁹ years for its mathematical discussion, so it would probably not
disturb the essential ideas of the argument in the text.