Preloader

Olympus Blog

In the Olympus blog you'll find the latest news about the community, tutorials, helpful resources and much more! React to the news with the emotion stickers and have fun!

VSCode's SSH Agent Is Bananas (2025)

We’re interested in getting integrated into the flow VSCode uses to do remote editing over SSH, because everybody is using VSCode now, and, in particular, they’re using forks of VSCode that generate code with LLMs.

”hallucination” is what we call it when LLMs get code wrong; “engineering” is what we call it when people do.

LLM-generated code is useful in the general case if you know what you’re doing. But it’s ultra-useful if you can close the loop between the LLM and the execution environment (with an “Agent” setup). There’s lots to say about this, but for the moment: it’s a semi-effective antidote to hallucination: the LLM generates the code, the agent scaffolding runs the code, the code generates errors, the agent feeds it back to the LLM, the process iterates.

So, obviously, the issue here is you don’t want this iterative development process happening on your development laptop, because LLMs have boundary issues, and they’ll iterate on your system configuration just as happily on the Git project you happen to be working in. A thing you’d really like to be able to do: run a closed-loop agent-y (“agentic”? is that what we say now) configuration for an LLM, on a clean-slate Linux instance that spins up instantly and that can’t screw you over in any way. You get where we’re going with this.

Anyways! I would like to register a concern.

Emacs hosts the spiritual forebearer of remote editing systems, a blob of hyper-useful Elisp called “Tramp”. If you can hook Tramp up to any kind of interactive environment — usually, an SSH session — where it can run Bourne shell commands, it can extend Emacs to that environment.

So, VSCode has a feature like Tramp. Which, neat, right? You’d think, take Tramp, maybe simplify it a bit, switch out Elisp for Typescript.

You’d think wrong!

Unlike Tramp, which lives off the land on the remote connection, VSCode mounts a full-scale invasion: it runs a Bash snippet stager that downloads an agent, including a binary installation of Node.

I think this is the source code?

The agent runs over port-forwarded SSH. It establishes a WebSockets connection back to your running VSCode front-end. The underlying protocol on that connection can:

  • Wander around the filesystem
  • Edit arbitrary files
  • Launch its own shell PTY processes
  • Persist itself

In security-world, there’s a name for tools that work this way. I won’t say it out loud, because that’s not fair to VSCode, but let’s just say the name is murid in nature.

I would be a little nervous about letting people VSCode-remote-edit stuff on dev servers, and apoplectic if that happened during an incident on something in production.

It turns out we don’t have to care about any of this to get a custom connection to a Fly Machine working in VSCode, so none of this matters in any kind of deep way, but: we’ve decided to just be a blog again, so: we had to learn this, and now you do too.


Source: Hacker News

ArXiv receives multiyear commitments to support it as an independent nonprofit

arXiv is pleased to announce that three leading philanthropic organizations have provided multimillion-dollar support for arXiv. These new multiyear philanthropic commitments from Simons Foundation International, XTX Markets, and Siegel Family Endowment will support platform development, organizational capacity, and overall provide foundational support to arXiv’s establishment as an independent nonprofit. The $17.2 million investment, spanning three to five years, will support arXiv as it transitions to independence by strengthening its technical infrastructure, supporting ongoing operations, and improving services for researchers around the world.

For three and a half decades, arXiv has been a trusted venue where researchers can share and access scientific findings. Today, we serve millions of users annually and play an essential role in scholarly communication across physics, mathematics, computer science, quantitative biology, quantitative finance, statistics, electrical engineering and systems science, and economics.

Helping Fund a New Organization

I am grateful for the commitments from Simons Foundation International, XTX Markets, and Siegel Family Endowment, which put arXiv on solid footing as we move into this next chapter. Their generous support provides a strong foundation and momentum for arXiv to continue to grow and serve the research community for the long term.” The new commitments build on previous philanthropic support for arXiv. arXiv gratefully acknowledges their community-based donors, including member organizations, foundations, affiliates, sponsors, and longstanding supporters.

penelope lewis, chief executive officer, arxiv

These new commitments will support three core areas of work:

  • General operation and ongoing improvement of arXiv’s services for the research community;
  • Continued technical development of the platform, including work related to the management of AI-generated content and other emerging challenges in scholarly communication; and
  • Strengthening of arXiv as an independent nonprofit, including investments in governance and organizational operations.

Simons Foundation International

Building on the Simons Foundation’s long-standing support of arXiv, Simons Foundation International has made a new multi-year commitment to support the organization’s next phase as an independent nonprofit.

For 35 years, arXiv has made math and science more open, transparent, accessible and collaborative. By growing into an independent nonprofit, arXiv will be positioned to evolve and modernize its systems to better serve the scientific community and to secure its future.

david spergel, president, simons foundation

XTX Markets

XTX Markets and its founder, Alex Gerko, have supported arXiv’s mission for the past two years. The firm is now making a new multi-year commitment to strengthen arXiv’s role as a trusted platform for open scientific research. 

For decades, arXiv has been an important bedrock for open science. Now, with rapid advances in AI driving changes across academia, it is even more valuable to have robust, open-source infrastructure for science. XTX Markets is delighted to continue our support for arXiv in this important endeavor.

simon coyle, head of philanthropy, xtx markets

Siegel Family Endowment 

Siegel Family Endowment has made a multi-year commitment to arXiv, advancing a shared vision for equitable digital infrastructure and open knowledge.

Open access to knowledge is a cornerstone of a healthy research ecosystem, but it is also essential to a thriving digital ecosystem and to ensuring people can equitably access and participate in the knowledge that shapes our world. We’re looking forward to supporting arXiv in its next chapter as essential infrastructure, enabling communities to share ideas, build on one another’s work, and sustain a living body of knowledge.

Joshua elder, svp & head of grantmaking at siegel family endowment

We are especially grateful to our major funders, who trust in arXiv’s important work, and are committed to our vision. Our major funders create a solid foundation of support and are an essential part of arXiv’s sustainable funding model, which is supplemented by our membership program, as well as our sponsors, our affiliates, and individual donors. Thank you for your unwavering support of arXiv!


Source: Hacker News

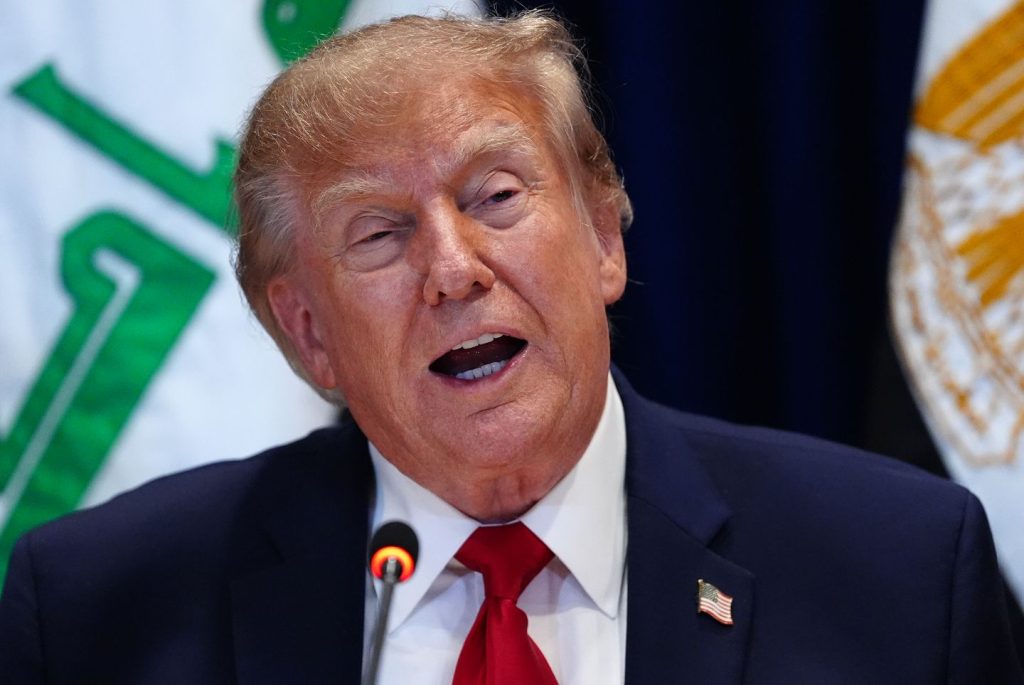
Chinese President Xi Jinping arrives in United States for state visit

Sept. 23 (UPI) — U.S. President Donald Trump greeted President Xi Jinping of China on Wednesday evening as the Chinese leader arrived at Joint Base Andrews in Maryland, marking the start of a three-day state visit.

The tarmac greeting was a rare gesture for an incumbent U.S. president to a foreign leader. Trump and first lady Melania Trump met Xi and his wife, Peng Liyuan, on a red carpet as the U.S. Air Force band performed the countries’ national anthems. The ceremony also included a cannon salute, a 21-person honor cordon, color guards and a flyover by two B1 bombers.

There will be another ceremony Thursday morning at the White House featuring more than 500 U.S. service members. The presidents will meet Thursday afternoon with a state dinner Thursday night.

Both Republicans and Democrats have criticized the visit and the lavishness of Trump’s treatment of the Chinese leader, The Hill reported. Sen. Roger Wicker, R-Miss., chairman of the Senate Armed Services Committee, said onthe Senate floor Tuesday that Trump should remember that Xi “is a brutal, unelected and oppressive dictator who seeks to dominate his neighbors and whose military arsenal is aimed directly at the United States of America.”

A statement by a group of Senate Democrats including Sens. Elizabeth Warren, D-Mass., and Chris Coons, D-Del., also criticized Trump’s red-carpet treatment of the Chinese leader.

“President Xi gets the royal treatment while President Trump hurls threats and wages trade wars on allies like Canada,” they wrote. “This is not leadership, and Americans deserve better.”

The Democrats called on Trump to end China’s access “to the advanced chips and manufacturing equipment it needs to build dangerous AI systems,” stand with Taiwan against China and press Xi to stop supporting Russia’s war in Ukraine.

The trip marks XI’s first state visit to the United States in 11 years.


Source: U.S. News

Virtio-nvgpu: Near-native Nvidia GPU access inside a KVM guest

virtio-nvgpu

Near-native NVIDIA GPU access inside a KVM guest. A guest renders within 2% of
the machine it is running on, and costs the same CPU.

virtio-nvgpu forwards NVIDIA kernel driver ioctls between a Linux guest and
the host at the driver ABI level, bypassing API-level translation entirely.
The guest runs NVIDIA’s own user-mode drivers, unmodified — the same libraries,
the same Vulkan and NVENC, talking to the same card.

The target is headless streaming: a compositor inside the VM renders,
composites and encodes frames on the GPU, then sends compressed video out. The
VM has no monitor, and the host keeps the card.

Where it stands

It works, and it has been measured. A Wayland client presents inside a
guest, the capture layer encodes on the game’s own device, and the H.264 comes
out the other side — 618 frames that ffmpeg decodes without an error.

Measured on an RTX 3060 (driver 595.99.02), guest against the same host, bare
metal
, with an identical headless Vulkan load:

what the host takes for one frame guest frame time
39 ms −0.4% faster than bare metal, within noise
9.9 ms −0.7%
2.0 ms +1.7%
0.5 ms +7.1% a wake costs ~0.02 ms, and the frame is half of one
0.05 ms +40.8%

Above about 2 ms a frame — which is every frame a game draws — a guest is
within 2% of bare metal.
Below that, the cost of waiting for the GPU starts to
show against a frame that barely exists.

CPU is the other half of it, because a shared GPU is only worth sharing if the
guests are cheap. Unpaced at ~100 fps for 12 s, one guest:

CPU used
host, bare metal 0.40 s
guest 0.37 s

A guest costs what the host costs. Nothing is spent on forwarding in a
render loop, because nothing is forwarded: NVIDIA’s user-mode driver submits
through memory it has mapped, and that memory is the host’s. Over 813,691
frames the backend served 13,792 messages — one crossing per 59 frames, nearly
all of it device setup.

Full method, raw runs and the things these numbers do not support:
BENCHMARKS.md.

Several guests on one card

Four guests on one RTX 3060, the same load in each: 25.84, 26.49, 25.57, 25.79
fps
— 103.7 together, against 102.9 for a single guest — with p50 frame times
of 39.165, 39.164, 39.168 and 39.165 ms. The total does not move as guests are
added, and the split is even to four decimal places.

All four render correctly at the same time, and four of them encode H.264 at
once
, each paced at exactly 60 Hz, with no NVENC session limit reached.

Four is what was run, not a limit found.

Driver versions

Measured on 595.99.02; an A2000 on 615.71.09 renders but is not
benchmarked. ABI profiles shipped: 535.129.03, 580.178.04, 595.71.05, matched by
range, with anything older than the first refused. Details below.

What is known to work

  • a guest enumerates the card — nvidia-smi reports real power and memory, and
    the deviceUUID is the host’s
  • Vulkan renders: vulkaninfo exits 0, offscreen draws are pixel-correct
  • a Wayland client presents through a compositor in the guest
  • NVENC through Vulkan Video, encoding on the client’s own device
  • imported buffers are the host’s memory, mapped through a shared window

What a guest can reach

Worth stating plainly, because it is the first question a security person asks
and the honest answer is not “nothing”.

There is no IOMMU boundary between guest GPU work and the host. The card
belongs to the host’s NVIDIA driver and sits in the host’s IOMMU domain; the
guest gets the driver’s ioctl interface, not the device. What separates a guest
from host memory is the GPU’s own MMU, with page tables RM programs on the
guest’s behalf — so the host NVIDIA driver is in the TCB. The guest also
authors its own command streams, which is exactly why there is no per-submission
cost.

What narrows that surface today:

  • ioctls the ABI profile does not describe are refused, not forwarded
    (--permissive-abi turns that off for diagnosis, and says so loudly)

What does not, yet:

  • RM_ALLOC classes and RM control commands are unfiltered
  • UVM and modeset ioctls have no equivalent table
  • the backend holds the host descriptors inside the VMM’s process; the
    unprivileged per-guest isolate is designed and unbuilt

This is attack-surface reduction, not hardware isolation. VFIO passthrough
with an IOMMU is strictly stronger — it constrains the device to the guest’s own
memory — and for mutually untrusted tenants that or vGPU is still the answer.

What is not done

  • more than four guests, or guests doing anything heavier than vkcube at
    720p. Four share the card evenly; eight has not been tried.
  • two cards, two driver versions. RTX 3060 / 595.99.02 is where the numbers
    come from; an RTX A2000 / 615.71.09 has rendered but is not benchmarked.
  • CUDA is forwarded but untested beyond enumeration; the jailer, per-version
    driver shares and the multi-tenant envelope are unbuilt.

Repository layout

Four components, three license zones. The split is deliberate: the guest half
must be GPL to touch kernel symbols, the host half should be permissive so that
other people can build on it, and the definitions both halves share must be
includable from both.

directory license what it is
driver/ GPL-2.0 Guest kernel module. Registers /dev/nvidia*, forwards ioctl and mmap over the virtqueue. Deliberately not ABI-aware.
device/ Apache-2.0 The virtio device, as a Rust crate with no VMM in its dependency list. Every VMM concern is a trait.
isolate/ Apache-2.0 A design note, not code yet. The sandboxed per-guest helper that will hold the real device FDs. Today the backend holds them itself, in the VMM’s own process.
gen/ — Generated ABI tables. Checked in and reproducible.
protocol/ BSD-3-Clause OR GPL-2.0+ Wire format and ABI definitions shared by both halves. Dual licensed so the GPL driver and the Apache crate can include the same headers.

The layout follows chromeos/virtio-media,
which solves the same problem — one repository holding a GPL guest driver beside
a permissively licensed, VMM-agnostic device crate.

Using it from a VMM

device/ depends on no virtual machine monitor. A VMM adopts the device by
implementing a small set of traits — descriptor chains as Read/Write, an
event queue, guest memory mapping, host memory mapping — and gets the whole
device without patching the crate. Optional capabilities degrade rather than
fail to build, so a VMM can adopt it before supporting every feature.

Buffer and window bookkeeping lives in device/. The VMM supplies raw map and
unmap and nothing more.

One thing that will not be a trait: the isolate. The intended design runs
one sandboxed helper process per guest process, so adopting it eventually means
inheriting a process model, not just a library dependency. That helper is
not written — the backend holds the device descriptors itself today — and
isolate/ is where the design lives until it is.


Why

The streaming pipeline we want

Guest VM (headless, no physical display)
──────────────────────────────────────────

  Game / application
    │ Vulkan or OpenGL
    ▼
  Wayland compositor (guest-side)
    │ composites all windows
    │ CUDA zero-copy import of composed frame
    ▼
  NVENC hardware encoder (guest-side)
    │ H.264 / H.265 bitstream (~100 KB per frame)
    ▼
  Stream to remote client

The entire render → composite → encode pipeline runs on the GPU, inside the
guest
. Only the compressed bitstream leaves. This requires the guest to have
real, driver-level access to GPU resources: buffer handles, fences, CUDA
device pointers, NVENC sessions.

Why existing approaches fall short

virtio-gpu + Venus (API-level translation). Venus serializes every Vulkan or
OpenGL call in the guest, transports it over virtio, and replays it host-side.
Three problems for this use case:

  1. Latency compounds on draw-call-heavy workloads. Games issue 1,000–5,000
    draw calls per frame plus binds, descriptor updates and render pass
    transitions, each serialized and replayed individually. At 60 fps the frame
    budget is 16.6 ms; 1–3 ms of serialization is 6–18% gone before any GPU work.
  2. CPU overhead is significant. Serialization, transport and replay burn host
    CPU the application needs. Where compute is billed and finite, that waste is
    the product.
  3. Guest-side encoding is not viable. GPU buffers are owned by the host.
    The guest compositor cannot see or import them, so there is no practical path
    to a CUdeviceptr in the guest pointing at a Venus-managed buffer — which
    means no NVENC without a full CPU readback and copy.

DRM native context (Intel / AMD). The guest runs the real Mesa driver, builds
command buffers locally, and only submissions cross the boundary. Guest-side
buffer ownership and encoding work correctly. This does not exist for NVIDIA.

VFIO passthrough. Native performance and a complete driver stack in the
guest, but it dedicates the whole GPU to one VM. In multi-tenant environments
that is often not an option.

What virtio-nvgpu does differently

Translation happens at the kernel driver level (ioctls to /dev/nvidia*),
not the graphics API level. The guest runs NVIDIA’s real user-mode libraries,
which build GPU command buffers locally in the guest — individual draw calls
are never serialized:

                    Venus                  virtio-nvgpu
                    ──────────────         ──────────────────────

Per draw call:      serialize +            local function call
                    transport +            (no VM exit)
                    deserialize +
                    replay

Per frame           ~2,000 messages        ~5–20 messages
  boundary          (one per API call)     (queue submits + allocs)
  crossings

GPU command         generated on HOST      generated in GUEST
  buffers           after replay           by NVIDIA's own compiler

CPU overhead        serialization +        near zero for rendering
                    deserialization        (only ioctl forwarding)

Guest buffer        HOST owns buffers      GUEST owns buffers
  ownership         compositor can't       compositor has full
                    track them             visibility and control

Guest NVENC         not viable             works (real CUDA interop)

How it works

Guest kernel driver. Registers /dev/nvidiactl, /dev/nvidia0…N and
/dev/nvidia-uvm. On ioctl() it serializes the request onto a control
virtqueue. On mmap() it maps the appropriate shared-memory region into the
calling process with the correct caching attributes. It copies raw bytes and
makes no ABI decisions.

Device crate. Receives requests, maps guest handles to host device file
descriptors, performs ABI-aware translation of ioctl parameters — rewriting
embedded pointers and file descriptors — and issues them against the host’s
devices. Buffer and window bookkeeping lives here.

Events. A second virtqueue runs the other way. The host watches each
descriptor it has opened and says when one becomes readable, which is how a
guest waiting for the GPU is woken. Without it the guest cannot wait at all —
it polls a descriptor the kernel reports as permanently ready, and spins.

Isolate — not built yet. The plan is a sandboxed helper per guest process,
holding the real device FDs and issuing the ioctl(2) calls unprivileged.
Today the backend does that itself, inside the VMM’s process.
isolate/ holds the design and no code.

┌─ Guest ─────────────────────────────────────────────────┐
│  Application → NVIDIA Vulkan / GL / CUDA                │
│                     │ ioctl(/dev/nvidia*)               │
│  driver/ (GPL)      ▼                                   │
│    serialize → virtqueue                                │
│    mmap → shared region                                 │
└───────────────────────────┬─────────────────────────────┘
                            │ VM exit
┌───────────────────────────▼─────────────────────────────┐
│  VMM  (implements the device traits)                    │
│                                                         │
│  device/ (Apache-2.0)                                   │
│    ├─ guest handles → host FDs                          │
│    ├─ translate embedded FDs and pointers               │
│    └─ buffer + window bookkeeping                       │
│                     │                                   │
│    └─ ioctl(host /dev/nvidia*) · mmap → shared window   │
│       (an unprivileged per-guest isolate is planned,     │
│        and is not what runs today)                       │
│                                                         │
│  Host NVIDIA driver → GPU                               │
└─────────────────────────────────────────────────────────┘

Scope

Targeted

  • Vulkan rendering, including presentation to a compositor inside the guest —
    which needs /dev/nvidia-drm and /dev/nvidia-modeset, both of which are
    implemented and neither of which is a display: they are how a buffer becomes
    shareable
  • OpenGL rendering (headless EGL)
  • CUDA device memory allocation
  • CUDA ↔ Vulkan/GL interop, zero-copy, GPU-side pointers
  • NVENC encoding from CUDA device pointers; NVDEC decoding

Out of scope

  • cudaMallocManaged() / full unified virtual memory
  • scanout. No physical display output: there is no monitor on a streaming
    box, and the frame leaves as video rather than as pixels on a wire
  • MIG, SR-IOV
  • Arbitrary NVIDIA driver versions — each supported range is explicit, as with
    nvproxy

Performance

Measured, on one card, by one synthetic load — see BENCHMARKS.md
for the method and the raw runs, and for what this does not support (it does not
support a comparison with any other hypervisor, because none was run).

virtio-nvgpu, measured Venus, by design
GPU-bound (≥2 ms a frame) 98–100% of bare metal 90–97%
Very light frames (≤0.5 ms) 93–71% of bare metal —
CPU cost of a rendering guest same as bare metal high (serialize and replay)
Host crossings per frame ~0.02 thousands
Guest-side NVENC works, zero-copy not viable

The difference is structural: Venus crosses the VM boundary per API call,
thousands of times a frame. virtio-nvgpu crosses it per ioctl — and a
render loop issues none, because submission is a write to mapped memory. What
is left at very light frames is not forwarding but waiting: the guest sleeps
for the GPU, and the wake costs ~0.02 ms however small the frame was.

The Venus column is that project’s design envelope, not something measured
here.


Driver versions

NVIDIA’s kernel driver ABI is not stable; ioctl struct layouts change between
releases. Support is explicit, and this is the whole list.

ABI profiles shipped:

profile covers
535.129.03 535.129.03 up to the next profile
580.178.04 580.178.04 up to the next profile
595.71.05 595.71.05 and newer

Profiles key off ranges, not points: a release between two profiles uses the
lower one, and anything newer than the last profile uses the last profile.
Anything older than 535.129.03 is refused rather than guessed at — forwarding
an ioctl whose layout has never been seen is how you get a plausible wrong
answer instead of an error.

A driver much newer than the newest profile is therefore accepted on the
assumption that nothing it needs has changed
. That assumption is what a new
profile exists to replace, and it is the first thing to suspect when a new
driver misbehaves.

Driver versions actually run:

version card how far it got
595.99.02 RTX 3060 everything — renders, presents, encodes, and every number in BENCHMARKS.md
615.71.09 RTX A2000 enumerates and renders; not benchmarked, and not re-tested since

Two cards, two versions, one of them thoroughly. Anything else is untested.

How a profile is built

The cost is bounded, for three reasons. Profiles key off ranges, not points,
so a release between two known versions selects the lower profile. The struct
half is derived mechanically from NVIDIA’s published open-gpu-kernel-modules
at each tag — compile a probe per field, read back sizeof and offsetof —
rather than transcribed by hand. And the judgement half, which commands exist and
which are safe, tracks nvproxy upstream.

See gen/, and supported_versions() there for the list in code —
that function, not this table, is the thing that decides.


Prior art

gVisor nvproxy — the direct inspiration. It forwards NVIDIA ioctls from
sandboxed containers to the host driver, handling ABI versioning, pointer and FD
translation, and GPU mmap management, and it supports Vulkan, OpenGL, CUDA and
NVENC in production today. Its ABI definitions (pkg/abi/nvgpu) and handler
logic (pkg/sentry/devices/nvproxy) are the primary reference. nvproxy also
demonstrates that Vulkan and NVENC work without /dev/nvidia-drm or
/dev/nvidia-modeset.

chromeos/virtio-media — the layout template. A GPL guest driver beside a
VMM-agnostic Rust device crate, with every VMM concern behind a trait.

WSL2 /dev/dxg — a production driver-level GPU proxy across a real
virtualization boundary, proving the general approach at scale. Different
problem: it targets a Windows host and a Microsoft-defined kernel abstraction.

DRM native context (Intel / AMD) — the same goal, achieved for other vendors:
the guest runs the real driver and builds command buffers locally, with only
submissions crossing the boundary. virtio-nvgpu aims at equivalent capability
for NVIDIA, where no native context exists.


License

Three zones, listed in Repository layout.
Full texts: LICENSE-APACHE-2.0,
LICENSE-GPL-2.0,
LICENSE-BSD-3-Clause.

Code ported from other projects keeps its original terms.

See also

  • BENCHMARKS.md — what it costs against bare metal, how that
    was measured, and what the numbers do not support.
  • ARCHITECTURE.md — how it works, in prose: what crosses
    the VM boundary and what does not, how memory is shared, how a buffer becomes
    shareable, how a guest waits, and what the design cannot do.

Source: Hacker News

Poll: More than 40% of Americans have positive view of socialism

Sept. 23 (UPI) — More than 40% of Americans have a positive image of socialism, a new Gallup poll released Wednesday said. The concept now ranks ahead of big business in opinions of the five economic concepts measured by Gallup.

This marks the first time a positive view of socialism has exceeded 39% in Gallup’s trend since 2010. Gallup has measured trends about public views of the economic concepts periodically since 2010.

In general, U.S. residents have become less positive about most of the concepts, Gallup said. Views of small business have remained nearly unchanged since 2010 at 95% positive. However, positive views of capitalism have fallen by six percentage points to 55%, views of free enterprise have fallen by nine percentage points to 77% and views of big business have fallen by 14 percentage points to 35%.

“Most of the increase in socialism’s positive rating through 2025 reflected increasingly positive views among Democrats, rising from 50% in 2010 to 66% last year,” Gallup said. “The latest uptick, however, comes entirely from political independents, whose positive rating jumped from 37% last year to 45% today. Democrats’ rating is essentially unchanged, at 65%, while Republicans’ remains below 15%.”

Gallup noted that there are strong age differences in the ratings of capitalism and socialism. Categories of gender, race/ethnicity and household income also show great differences.

Positive ratings of capitalism and free enterprise are higher among older age groups, and positive ratings of socialism are lower. People ages 18 to 34 view socialism (57%) more positively than capitalism (43%), while those 55 and older view capitalism (65%) more positively than socialism (34%). Those ages 35 to 54 view the two systems about the same.

Men tend to view capitalism more positively than socialism, though this trend is reversed for women. Upper-income Americans are more positive than lower-income Americans toward capitalism and free enterprise.

Gallup said that the trends, however, “don’t indicate wholesale movement away from markets and toward socialism.”

“Small business remains nearly universally popular, and free enterprise continues to receive broadly positive ratings — including among Democrats and younger adults, who are more positive toward socialism than other groups,” Gallup said, noting that its recent research has reinforced “a more nuanced picture” and found “widespread support for free-market principles such as economic competition and market choice, even as Americans express concerns about capitalism’s potential to produce inequality and excessive corporate power.”

Gallup surveyed 1,200 adults between Aug. 3-24 with a 4% margin of error.


Source: U.S. News

Texas executes second man convicted in 2005 triple murder

Sept. 23 (UPI) — Texas on Wednesday evening executed the second of two men convicted of committing the same triple murder, marking the state’s sixth execution and the nation’s 28th of the year.

Ker’sean Olajuwa Ramey, 41, was executed by lethal injection at the state penitentiary in Huntsville, located about 70 miles north of Houston. He was pronounced dead at 6:34 p.m. CDT, the Texas Department of Criminal Justice told UPI in an email.

In his last statement, Ramey said that he grew “to become something greater” than the man written about in the newspapers and apologized to his two children for his failures, for not being there “and the things you may have had to go through.”

“I attempted to structure things so you can have a positive male and individuals around you guys moving forward so the knowledge that I started to give to you is not lost,” he said.

Ramey, who was 21 when he entered death row, expressed gratitude to the other inmates he came in prison, who “poured into me and showed what it means to be a man, and didn’t understand what manhood was.”

“I didn’t come from a culture in a healthy sense,” he said. “To my brothers, I can’t name everybody, you know who you are, I greatly appreciate you.”

Ramey was convicted of capital murder and sentenced to death in January 2007 for the murders of Celso Lopez, 38, Tiffani Peacock, 18, and Sam Roberts, 24, on Aug. 24, 2005.

Court records state that Ramey, then 20, and his codefendant, LeJames Norman, who was 19 at the time, broke into Roberts’ home in Edna, Texas, believing he had at least a kilogram of cocaine that they intended to steal. There, they shot and killed Roberts, Lopez and Peacock, then fled the scene.

Investigators received a tip that November implicating Ramey in the murders and he was questioned in December at a Texas detention facility, where he was being held on unrelated charges. Norman was arrested in January 2006 as he was attempting to re-enter the United States from Mexico, where he lived with his girlfriend.

Norman testified against Ramey who was tried first and convicted by a jury that had no Black jurors.

Ramey was executed after the Supreme Court denied his final stay application and certiorari petition earlier Wednesday. He had over the years appealed his conviction on the grounds of racial discrimination in jury selection and ineffective assistance of counsel, though those claims were rejected.

“Ramey’s trial was marred by serious constitutional violations, including the systematic exclusion of all potential Black jurors, the State’s presentation of false testimony and, above all, the abysmal performance of his trial attorney — a full-time dentist and part-time lawyer — who failed to conduct his own investigation or provide witnesses to rebut the state’s case,” the Texas Coalition to Abolish the Death Penalty said in a statement following Ramey’s execution.

Norman was executed by Texas on Sept. 16.

Texas has so far scheduled three more executions for the year.


Source: U.S. News

Hackers say they stole thousands of FBI employee records

Sept. 23 (UPI) — A criminal hacking group claims to have stolen thousands of sensitive records “on almost ALL FBI Agents and individuals who filed an application with the FBI for a job.”

The group, called ShinyHunters, posted the online message Tuesday, saying it breached the FBI’s online jobs portal to obtain the information, which includes agent and applicant names, addresses, phone numbers, spouse names, medical details and other data. That website remains offline Wednesday.

“We have compromised the FBI,” the message said. It was addressed to FBI Director Kash Patel and agency cybersecurity leader Brett Leatherman.

In a statement issued Wednesday, the FBI said that it is aware of the claims but that the point of the breach is still undetermined.

“We are actively and aggressively investigating this matter and working closely with those third-party providers that support FBIJobs.gov to mitigate any and all risk,” the statement said.

ShinyHunters said that it targeted the FBI because of an advisory the agency issued in May. In that advisory, the FBI warned that the group was known to harass hacking victims or family members with “real or exaggerated” claims and extortion attempts.

The group demand the FBI “correct or simply remove” the advisory, which the FBI issued after it identified ShinyHunters as responsible for a hack of the online learning system Canvas.

“We have been severely offended,” the group said in its statement. It gave the FBI a week to change or remove the advisory, although it didn’t say what measures it would take otherwise.

The New York Times reported that the group sent it and other news organizations a sample of what it claimed is the leaked information. “Cross references of some of that sample data against publicly available information online indicated that the materials are most likely legitimate,” The Times reported.


Source: U.S. News

Latest Posts