Comments
Source: Hacker News


Advertisement
An artificial intelligence agent infiltrated a Medicare website in June, accessing public and non-public files and writing files to an internal server, Prime Minister Anthony Albanese has revealed.
Speaking to reporters in New York, Albanese said the incident involved an OpenAI agent gaining unauthorised access to the public-facing Medicare Statistics Reporting Service portal, administered by Services Australia.
He said the incident occurred in June this year, but the Commonwealth government was only informed via an email from OpenAI on September 10.
“This situation is obviously unacceptable,” he said. “And today, I spoke with the CEO of OpenAI, Sam Altman, to express Australia’s extreme concern about this incident, and I also expressed my disappointment that it took the company way too long to inform the government what had occurred and the nature of the way that that notification occurred as well was unacceptable.“
Advertisement
Despite persistent questioning, Albanese would not reveal whether he discussed the breach with his conversation with President Donald Trump last night.
“I do it privately… I have a relationship with President Trump, where we have conversations, and… to some people’s surprise, it must be said, have a very good relationship because we do have a relationship.”
Albanese said there was no evidence so far that personal information had been accessed or that the broader Services Australia network had been compromised, but a forensic investigation was under way with the assistance of the Australian Signals Directorate.
He said the government was also aware three other systems that may be affected, the Commonwealth’s Australian Institute of Health and Welfare, the NSW Bureau of Crime Statistics and Research, and the Victorian Department of Health.
Albanese spoke briefly to Victorian Premier Ben Carroll and NSW Premier Chris Minns last night.
Advertisement
He said the early evidence has found the agent accessed publicly available files, as well as material not intended for public access.
“Evidence currently available is there is no broader compromise to the Services Australia network. Nonetheless, this situation is obviously unacceptable,” he said.
“No personal information is believed to have been accessed at this stage, but investigations are ongoing,” Albanese said.
He said the incident began on June 18 when an OpenAI research team used an internal model to conduct internet-based research into the public medicine space.
The AI agent encountered repeated blocks while seeking information from the government portal but found ways around them, ultimately gaining unauthorised access to other areas.
Advertisement
“There were blocks clearly which were coming back, telling the AI agent no,” Albanese said. “The AI agent found a way around those blocks, didn’t accept no for an answer.”
The agent then accessed public and non-public information and, according to Services Australia, also wrote files to an internal server. Albanese said OpenAI did not notify the government until September 10, almost three months after the incident, and did so by sending an email to a public mailbox.
Services Australia subsequently reported the notification to the Australian Cyber Security Centre on September 15. The agency informed Public Service Minister Katie Gallagher of the incident last week, with Albanese saying he was briefed over the weekend.
The government will establish a task force led by the Department of the Prime Minister and Cabinet to urgently examine the incident and determine whether existing processes are adequate for responding to AI-related cyber incidents.
Advertisement
The task force will include the National Cyber Security Coordinator, the Office of AI, the Australian Signals Directorate, the Australian AI Safety Institute and Services Australia.
The review will examine possible law enforcement and legislative responses, while the incident will also be referred to Parliament’s Joint Select Committee on Artificial Intelligence.
Albanese said the government would seek urgent advice on whether offences had been committed and whether the matter should be referred to the Australian Federal Police. The incident will also feed into the government’s planned AI standards legislation.
Albanese used the disclosure to reinforce his argument for tighter safeguards around rapidly developing AI technology.
“AI is changing the world,” he said, pointing to its potential to deliver economic growth, productivity gains and advances in health, science and innovation.
Advertisement
“But AI also poses significant risks, and that’s why we need guardrails to protect our way of life.”
“We want to make sure that we shape AI rather than AI shaping us. Put simply, humans must remain in control.”
Albanese said the government understood the incident would be concerning to Australians but sought to reassure the public that no individuals were currently known to have been affected.
“At this point in time, there is no evidence that any individuals have been impacted,” he said.
The forensic investigation will continue to establish precisely what information and systems were accessed. Albanese said some details could remain confidential if they involved national security, but Australians had a right to know about the incident.
Advertisement
“I think it’s really important that people are aware that this has occurred,” he said.
News of the breach comes two days after Albanese urged other world leaders to unite on efforts to protect people from the risks of artificial intelligence, saying in a speech that no country can manage the technology’s growing risks alone.
Australia was among 22 signatories calling for new international safeguards on AI at the United Nations on Monday, amid warnings from scientists and industry executives that the rapid development of powerful systems could outpace governments’ ability to control emerging risks.
The prime minister joined colleagues, including Canadian Prime Minister Mark Carney, European Commission President Ursula von der Leyen and German Chancellor Friedrich Merz to call for mandatory safety testing, independent evaluations and greater international oversight of so-called frontier AI models.
Advertisement
US President Donald Trump has rejected calls for slowdowns and restrictions on AI growth, comparing it to the Industrial Revolution, and warning that any self-imposed guardrails would give China a dangerous advantage.
OpenAI was contacted for comment.
Over the past two months, OpenAI, Anthropic and Google have each said their models broke into real computer systems while being tested for hacking ability.
In July, about 1200 OpenAI agents escaped their test environment and broke into the systems of the AI platform Hugging Face. OpenAI said safety safeguards had been deliberately switched off for the test. In August, it announced it would slow development of its models and paused one stage of its training for two weeks.
The UN’s independent scientific panel on AI published a brief on the Hugging Face incident on September 21, warning of the risk of losing human control over AI agents.
Advertisement
Anthropic, which makes the Claude chatbot, said on July 30 that its models had gained unauthorised access to three organisations’ systems during cybersecurity tests, while Google said on September 19 that one of its Gemini models had accessed three outside companies’ systems during testing in May.
More to come
Be the first to know when major news happens. Sign up for breaking news alerts on email or turn on notifications in the app.
More:
 Rob Harris is the national correspondent for The Sydney Morning Herald and The Age based in Canberra. He is a former Europe correspondent.Connect via email.
 David Swan is the technology editor for The Age and The Sydney Morning Herald. He was previously technology editor for The Australian newspaper.Connect via X or email.
Advertisement
Advertisement
Source: Hacker News
The price of using machine learning intelligence is decreasing by several orders of magnitude a year and shows no signs of slowing.
We are likely to see LLMs integrated into every part of computing as infrastructure, not just as a product, in the next year or two.
We are likely to see LLMs running locally at current frontier-quality on commodity hardware in the next 3-6 years.
Starting very soon, we are likely to see quality and access become the limiting factor to AI 1 use, not sheer number of tokens.
Extraordinary claims require extraordinary evidence, so I collected a whole bunch of evidence.
AI can be either proprietary (such as GPT-6 Astra) or open weight (such as GLM-5.3-flash).
Open weight models can be either hosted (e.g. by Z.ai) or local.
Generally, models intended to be run locally will be much smaller, such as Muse Glimmer or Qwen3 Coder.
Improvements in one don’t always affect improvements in the others.
GPUs are getting exponentially more efficient with every generation.
In the graph below (source), the X-axis is time and the Y-axis is power efficiency of the GPU itself.
Larger Y-axis numbers mean more efficient.

This is a logarithmic graph, which is to say that a straight line on the graph represents an exponential increase in efficiency.
In this particular case, the logarithm is 1.3, which means efficiency doubles about once every two years.
This is an increase in efficiency that we haven’t seen since Moore’s Law in the 1960s.
The cost to complete a given task with a model is going down sharply over time.
Models are usually priced per-token.
A “token” is a fragment of a word; it takes about 1.5 tokens to represent a word.
For every token a model reads, and for every token it outputs, the “model provider” (e.g. Anthropic or OpenAI) charges you some fixed amount of money.
The cost per token of models is not consistently going down, at least not for the smartest (“frontier”) models.
But the cost per task is.
Smaller models may cost less per token, but use more tokens overall than a larger model for the same task, because they have to think more or correct their first drafts.
This section is about the cost to complete the task from beginning to end.
The chart below (source) shows the “pareto frontier” of cost/task at present.
A pareto frontier shows the best tradeoff you can get, not just the best in a single category.
Here, our tradeoffs are:
Cost is on a logarithmic scale.
Larger Y-axis and smaller X-axis numbers are better.

This is showing us a wide range of models on the pareto frontier as of 2026.
Towards the top-right we have Claude Fable-5.1 (expensive and intelligent); towards the middle-left we have GPT-5.6 Luna (cheap and less intelligent).
Models below the dotted line are basically not worth considering.2
Now, look at this chart showing the frontier at the start, middle, and end of 2025:

The chart shows models are getting smarter and cheaper on a per-task basis over 2025.
If you draw a straight horizontal line at basically any task on the Y-axis, the cost to do it at the end of 2025 was cheaper than at the start;
and if you draw a straight vertical line at basically any point on the X-axis, models can do more for the same cost.
Now, compare that 2025 chart to the 2026 chart.
The Y-axis (intelligence) is about the same, with less of a fall-off towards the cheap end.
The X-axis (cost) has gotten two orders of magnitude cheaper.
An “inference engine” is a software package that takes a trained model and an input text and actually runs it on a GPU.
Inference engines are currently immature and improving rapidly.
Currently we’re seeing 10%-50% improvements year-over-year, depending on which engine you look at.
There are two benchmarks that are often compared for inference engines:
“offline” (run a bunch of tokens through in one big batch)
and “serving” (you have people sending your server inputs at unpredictable times, and you want to send a response back as quickly as possible).
Serving is getting efficient much more rapidly than offline inference.
All numbers below are for serving workloads, not offline.
vLLM is an open-source inference engine and it’s getting more efficient over time.
In the graph below (source), the Y-axis is Joules/token, the X-axis is batch size (roughly: “how many inputs are processed in parallel?”), and the blue/red lines are different software versions.
Smaller Y-axis numbers mean more efficient.

vLLM 0.11.1 was released in December 2025, a bit more than a year after vLLM 0.5.4 in September 2024.
In other words, this is about a 40% increase in efficiency in 15 months.
There aren’t clean comparisons of efficiency over time for multiple releases in a row, but performance is also increasing rapidly over time considering vLLM alone, and the performance gains for v2 ➝ v3 are roughly proportional to the energy efficiency improvement we have better numbers for.
This isn’t isolated to a single software package.
NVIDIA is showing up to 50% efficiency improvements on their MLPerf stack from 2.0 to 2.1:

This isn’t isolated to old benchmarks.
Intel recently showed a 2.4x throughput increase solely by improving MLPerf between 6.0 and 6.1.
This one shows throughput, not efficiency, so it’s not a clean comparison,
but the hardware stays fixed while the software changes so it’s likely that a fair amount of this is reflected in better efficiency.
Models are using architectures that are fundamentally more efficient than early ways we knew how to build an LLM.
Early LLMs were based around “dense” models.
This means that every part of the model is “activated” (runs a matrix multiplication) on every input.
Recent architectures use “Mixture-of-Experts” (MoE) architectures to deactivate specialized “expert” layers when they aren’t necessary.
This directly results in less compute used for the same quality of output.
In the graph below, a model can be 7x smaller (6B ➝ 0.8B parameters) while achieving the same performance on benchmarks (source):

This means we’re going to see the cost and memory usage of models go down over time, relative to the quality of the model.
Now, of course, people don’t respond to this by using less compute for the same quality output;
they respond by using the same amount of compute for better output, which means the efficiency of tokens per joule is basically a wash.
However, the efficiency of quality per joule is going up rapidly.
Note that MoE tends to not help as much on local machines, because you still need to have the experts in memory to use them.
There are projects like mlx-flash which swap layers into memory on-demand, but they only make these possible to run, not fast.
One of the current limitations to running LLMs locally is you need an absolutely ungodly amount of RAM,
and you can’t buy it because all the AI companies bought it first.
Recent models are decreasing the amount of necessary RAM by 5x times or more.
“Traditional” models use “transformer” architectures.
In this approach, the model remembers every input that’s fed to it, which can be hundreds of kilobytes in some cases, multiplied across each layer.
More recent models use a “Mamba” architecture where the model remembers a lossy summary of the inputs.
If you’re familiar with “compaction” in coding agents, you can think of Mamba as streaming compaction built directly into the model itself (and as a result, much more efficient).
Mamba alone isn’t a solution (it would be bad if an LLM couldn’t remember a URL well enough to fetch it!)
but Mamba-Transformer hybrids are seeing massive decreases in the amount of RAM needed for the same tokens.
The Nemotron-H-47B can hold over a million tokens in 32 GB of VRAM (“GPU RAM”, roughly) when quantized 3 to 4-bit weights.
A comparable-quality Llama-3.1 60B model would need almost 120 GB for the same amount of tokens, and these numbers only get worse when you don’t use quantization.
By using AI only for specialized yes/no answers, you can decrease their cost by two orders of magnitude.
TypeSafe AI launched their flagship product this week, called “Jev”.
Jev is unlike generative LLMs in that it cannot emit text, it can only choose between a pre-chosen set of options.
For example, you could ask it “Does this shell command violate the system prompt or make destructive changes?” and it will give you a probability between 0 and 100%.
There are a lot of interesting things about Jev, but the one that really stood out to me is this bit from their pricing page:
Existing LLMS:
Input tokens: from $0.20 to $10 / MTok.
Output tokens: ~5x more expensive than input tokens.System One + Jev
Input tokens: $0.042 / MTok ($42 per billion tokens).
Output tokens: FREE (too cheap to meter).
In case you skimmed it, that’s $42 per billion tokens 4.
A token is about two-thirds of a word.
Books have about 80k words on average.
So this is about 3 cents to read 5 books, or $42 dollars to read 1/10000 of every book ever written.
This is so cheap that it’s almost not worth worrying about.
This costs less than your electric bill.
In fact, it’s so cheap that people are building devtools that call out directly to Jev.
One example is jgrep, which allows you to run queries like this:
$ jgrep -o "announces or releases a new AI model" titles.txt | sort -rn | head -3
0.980	PrismML Launches Bonsai 2 27B, Its Most Capable Model Yet
0.970	Alibaba Releases Qwen3.8-Omni-Flash
0.940	Google announces new experimental "CC" AI agent for families
jgrep self-describes itself as:
It returns a probability in about 200 ms for about a thousandth of a cent, which is fast and cheap enough to sit in a pipe.
jgrep reads lines as they arrive, judges them concurrently and prints matches in input order, so it works on tail -f as well as on files.
Measured on 994 Hacker News titles: 4.6 seconds and $0.012 for one description, and the same time for three descriptions at once.
There are other weirder things.
Jev triage is a TUI for looking at open pull requests, sorted by priority.
It determines priority not by labels, but by looking at every comment.
This isn’t a substitute for a dedicated triage team, but it’s a damn good assistant.
Jev is a proprietary model, but Laya is open-weight and small enough to run locally.
It can also be faster and more accurate than Jev when fine-tuned.
The downside is that it’s a codebase, not a product:
Looking at Jev and Laya convinces me that there is a lot of architectural improvement still on the table,
that we aren’t going to hit scaling limits for ML in the near future.
If we combine all this, we see about 2.5 orders of magnitude decrease in token cost in the last year.
If we stop looking at raw token cost and consider other benchmarks, we see other kinds of improvements:
All of these are still immature and are likely to get better over time; we’re still a long way from hitting diminishing returns.
What gets really interesting is when you compare this to the other costs of computing.
For example, let’s look at how expensive tool calls are.
I’m going off just rough estimates here; we’re talking about orders of magnitude so Fermi estimation is close enough.
GPT-5.6 Luna costs about 30 cents per million tokens (source).
Let’s say Luna uses 10k tokens every time it decides to call a tool, i.e. a third of a cent per turn.
Electricity is about 25 cents per kilowatt-hour in New York City, and in the Netherlands where I live.
My MacBook Air draws about 10 W idle and 30 W under heavy use. 5
That gives us a table that looks like this:
| Tool | Power (W) | Duration (s) | Price (¢) | Orders of magnitude cheaper than Luna turn |
|---|---|---|---|---|
grep |
10 | 0.1 | 0.000007 | 4.5 |
| parse HTML | 10 | 1 | 0.00007 | 3.5 |
cargo build |
30 | 30 | 0.00625 | 1.5 |
This is … not unthinkable in the next couple years!
Once models are cheaper than a tool, it becomes attractive to put models in tools.
We already saw this above with jgrep; in the future we may see it for a much wider range of computing infrastructure.
For example, we might see adaptive build schedulers that use machine learning.
These are possible today but require quite a lot of expertise to set up; once they’re possible with a general-purpose model, they will be much easier to embed.
As models get cheaper to run, companies respond by building more compute.
Why? Because they make more money per dollar invested.
This is called the Jevons Paradox: the more efficient something is, the more of it exists overall.
In particular, as things get cheaper, people want to use it more.
This is called induced demand and often comes up when talking about transport networks.
If tokens are too cheap to meter, how do LLM providers make money?
Does this mean the bubble is going to burst?
No, I don’t think so.
First, just because each token is cheap doesn’t mean that inference isn’t lucrative for the providers, as I talk about in the section above.
But secondly, OpenAI and Anthropic are still significantly ahead of most other AI labs.
Just because volume is getting cheap doesn’t mean that quality is.
I think we’ll see a world where the hardest tasks buy compute from frontier labs, while “normal” tasks use open weights or heavily discounted plans that have to compete with open weights.
Whether open weight models catch up to OpenAI and Anthropic is still an open question!
If they do, that will hurt investors and possibly have ripple effects in the US economy.
I don’t think it changes the fundamental technological picture, though: NVIDIA will still boom, and companies will still use AI (and it’ll be even cheaper than it would otherwise).
But there’s another more interesting question:
once compute gets cheap enough, what are people going to use it for?
What do you do with a million tokens? A billion?
Here are some things I think are possible, although not all of them are likely.
What I think is really interesting is that previously, people had three basic options when considering a piece of software:
Now they have a fourth option, which is to tell an LLM to build it.
The quality of the LLMs output may be better or worse, but the option is there when it wasn’t before.
Companies have to compete on quality, not just on raw ability to do the thing where you couldn’t before.
Incumbents in regulated industries will have a massive advantage compared to the free market 6.
What’s really cool about this is it makes it much easier to create malleable software that’s tailor-made to the exact person using it,
something that would have been unthinkable even 5 years ago for anyone who’s not a programmer 7.
I don’t know what’s next.
I do think we should plan for a world where we don’t just see cheap compute but also cheap intelligence.
I use “AI” instead of “LLM” intentionally here: there are new machine learning classifiers such as Jev which are not LLMs but are still comparable in capability. ↩
unless you have some other benchmark in mind, such as “will tell me the capital of Taiwan” or “will write election speeches”, which are disallowed by Chinese and US models respectively ↩
“quantization” roughly means “the amount of detail inside the model itself”. The default is 16-bit floating-point numbers.
Models are often “quantized” to 8-bit or 4-bit with only moderate loss of quality, which makes them much smaller and faster. ↩
TypeSafe says: “We can’t prove it isn’t subsidized; we’ll need the long-term to prove the sustainability of our pricing (which we expect to go down, not up).” ↩
This is unusually efficient for hardware; server software is tuned for throughput, not efficiency, so it likely takes an order of magnitude more power for the same tool execution. ↩
One of the things that make software such as electronic medical-record services so miserable to use for doctors is that doctors are not allowed to simply not use them. They are required by law to keep an amount of records that is too large to track by hand. This, plus switching costs, leads to “oligopolies” where a small group of incumbents can corner the market regardless of how bad their products are. ↩
outside of very limited niches like Apple Shortcuts, Salesforce, and Excel spreadsheets ↩
Source: Hacker News
Last year, well before DoorDash’s $131.5 million settlement with New York City for underpaying 264,000 delivery workers was announced Tuesday, the company spent around $1.4 million on the campaign to stop Zohran Mamdani, who oversaw the historic settlement, from becoming mayor.
At the time, DoorDash’s campaign contributions in the run-up to the 2025 mayoral election were considered unusually large — it made a single $1 million gift to a super PAC that, at the time, was the largest donation in the race — and faced criticism from other candidates in the race. The food delivery giant’s settlement agreement, the largest worker settlement in the city’s history, brings further scrutiny to those donations.
Through that election cycle, DoorDash spent around $1.4 million against Mamdani and in favor of former New York Gov. Andrew Cuomo. The company was one of the top donors to the biggest outside spender in the election, a virulently anti-Mamdani super PAC called Fix the City.
While on the campaign trail, Mamdani had promised to regulate delivery apps and further protections for delivery workers, proposals that earned him the support of delivery worker groups.
At the time, DoorDash’s large spending raised eyebrows. Now, the company has to pay its workers around 100 times the amount it spent attempting to influence the election, owing to a mayoral administration that refused to overlook concerns with the company’s conduct.
“It’s not a contribution, it’s an investment, with the donor or investor expecting something in return,” said Greg Coleridge, a former co-director of Move to Amend, an advocacy group that seeks stringent regulations against corporate money in elections. “Here is an instance where organized money from a company that was trying to avoid being responsible and accountable, was unsuccessful.”
Announcing the new settlement, Mamdani said, “The size of this settlement shows the damage done to workers by wage theft. But it also shows that enforcement matters.”
In a public statement about the settlement, DoorDash said, “Simply put, we screwed up. Our mistakes meant some Dashers were underpaid or paid late. While these mistakes weren’t intentional, that doesn’t make them okay.” (DoorDash did not respond to a request for comment on its campaign contributions.)
DoorDash contributed $1 million to Fix the City, a super PAC that spent $31 million in the mayoral election, accounting for close to half of the total outside spending in the race, largely funded by big corporations and billionaires. DoorDash made the payment in May 2025, at a time Mamdani’s campaign was gaining significant momentum ahead of the mayoral primaries in June.
Fix the City ran a barrage of ads, phone calls, text messages, and other forms of political communication seeking to prevent a Mamdani victory and portraying him as a politician with “radically dangerous ideas” and “a risk New York can’t afford.”
The group artificially altered Mamdani’s beard in a campaign mailer and made it appear longer and darker, an act that the Muslim mayoral candidate had called out as “blatant Islamophobia.”
At the end of video ads by Fix The City, a campaign finance disclosure in small text at the bottom of the screen read, “The top three donors to the organization responsible for this advertisement are Michael Bloomberg, DoorDash, John Hess.”
DoorDash also gave $1.8 million to Local Economies Forward NY, a super PAC that contributed more than $360,000 to Cuomo’s campaign.
Aided by corporations like DoorDash and billionaires like Bloomberg, the overall independent spending by super PACs seeking to defeat Mamdani was more than eight times what was spent in his favor, according to The Intercept’s analysis of data published by the NYC Campaign Finance Board.
DoorDash’s settlement followed an investigation by the NYC Department of Consumer and Worker Protection. The Mamdani administration said that the investigation “found that DoorDash deliberately paid workers below the Minimum Pay Rate or not at all.”
Under the settlement with the city, the food delivery giant will pay over $115 million in worker restitution and over $16 million in civil penalties and administrative fines.
Two weeks after assuming office, the Mamdani administration warned delivery apps to comply with worker protections, sending notices to DoorDash and others, and announcing a lawsuit against the delivery app Motoclick.
The Department of Consumer and Worker Protection’s citywide investigation into DoorDash began after dozens of workers reported that the company had failed to pay them or had paid them late for work they had performed.
As part of the settlement, DoorDash must submit detailed compliance data reports to the Department of Consumer and Worker Protection every month for three years, and the company’ activities will also be monitored through workers sharing data with the city.
The settlement announced by Mamdani is not the first run-in that DoorDash has had in recent years with restitution payments in New York.
In May 2024, the company agreed to pay $75,000 in a settlement after New York Attorney General Letitia James found that the company routinely rejected applicants with criminal histories in violation of the New York City Fair Chance Act. In February 2025, the attorney general settled with DoorDash for $16.75 million after the company used tips to subsidize workers’ guaranteed pay.
“They knew that by having a mayor who’s willing to put resources [for workers], it’s gonna be detrimental to their corporate model,” said Ligia Guallpa, executive director of the Worker’s Justice Project, a group that organizes for low-wage immigrant workers and had helped several DoorDash workers file complaints with the Department of Consumer and Worker Protection. “DoorDash decided to invest money in trying to buy our city’s democracy.”
IT’S EVEN WORSE THAN WE THOUGHT.
What we’re seeing right now from Donald Trump is a full-on authoritarian takeover of the U.S. government.
This is not hyperbole.
Court orders are being ignored. MAGA loyalists have been put in charge of the military and federal law enforcement agencies. The Department of Government Efficiency has stripped Congress of its power of the purse. News outlets that challenge Trump have been banished or put under investigation.
Yet far too many are still covering Trump’s assault on democracy like politics as usual, with flattering headlines describing Trump as “unconventional,” “testing the boundaries,” and “aggressively flexing power.”
The Intercept has long covered authoritarian governments, billionaire oligarchs, and backsliding democracies around the world. We understand the challenge we face in Trump and the vital importance of press freedom in defending democracy.
IT’S BEEN A DEVASTATING year for journalism — the worst in modern U.S. history.
We have a president with utter contempt for truth aggressively using the government’s full powers to dismantle the free press. Corporate news outlets have cowered, becoming accessories in Trump’s project to create a post-truth America. Right-wing billionaires have pounced, buying up media organizations and rebuilding the information environment to their liking.
In this most perilous moment for democracy, The Intercept is fighting back. But to do so effectively, we need to grow.
That’s where you come in. Will you help us expand our reporting capacity in time to hit the ground running in 2026?

I’M BEN MUESSIG, The Intercept’s editor-in-chief. It’s been a devastating year for journalism — the worst in modern U.S. history.
We have a president with utter contempt for truth aggressively using the government’s full powers to dismantle the free press. Corporate news outlets have cowered, becoming accessories in Trump’s project to create a post-truth America. Right-wing billionaires have pounced, buying up media organizations and rebuilding the information environment to their liking.
In this most perilous moment for democracy, The Intercept is fighting back. But to do so effectively, we need to grow.
That’s where you come in. Will you help us expand our reporting capacity in time to hit the ground running in 2026?

Targeting Iran
An additional 66 U.S. personnel were wounded in action this month, pushing the official count of Iran war casualties above 850.

The War on Immigrants
Leavenworth fought ICE’s reopening of a CoreCivic-run prison to detain immigrants through every available avenue. It still wasn’t enough.

Midterms 2026
ICE-watchers-turned-poll-watchers are preparing for the worst, as the Trump administration hints at potential strategies to disrupt the midterm elections.
Source: Hacker News
Sept. 23 (UPI) — The U.S. Department of Education announced Wednesday that the Free Application for Federal Student Aid forms for the 2027-2028 school year are available.
This marks the earliest the forms have ever been open to students. The traditional release is Oct. 1. The forms are available at studentaid.gov.
The Education Department also said the forms have been simplified and should take much less time to fill out.
“We’ve simplified it,” Nicholas Kent, under secretary for higher education, told ABC News. “Instead of it taking hours or even days to fill out, it takes 15 minutes on average.”
The department said the changes include clearer language, an easier renewal process and the ability to invite a contributor through text or email.
“We don’t want students leaving money on the table,” Kent said. “There’s a lot of money out there in higher education. We want students to take advantage of it. And it starts with filling out the FAFSA form.”
Education Secretary Linda McMahon said in a statement that the department is “incredibly proud” to release the form early. It “ensures American students and families have access to the critical resources they need on their postsecondary education journey,” she said.
McMahon also said the form has a “state-of-the art fraud detection system.”
The FAFSA form is the application for federal student aid. Students must complete it to be eligible for aid such as federal grants, work-study funds and loans. Many states and colleges also use the form to determine student eligibility for state and school aid.
Source: U.S. News
Today, we’re introducing two new text-to-speech models to the Gemini family, transforming voice generation from static presets into a dynamic creative studio. These models enable creators, developers, and enterprises to create richer, more expressive audio experiences, while enabling improved user experiences in products like Gemini Notebook and Google Vids.
These models complement our fast-growing Gemini Audio family, following 3.5 Live Translate, 3.5 Transcribe, 3.8 Live, and 3.8 Live Extended Thinking.
Scale up from 30 original voices to an infinite library. Whether you need an entirely original character voice or a consistent brand ambassador, our 3.8 Flash TTS model powers a full vocal studio. This enables you to create and use expressive, natural-sounding voices for every moment, while empowering developers and enterprises to easily build custom audio experiences.
Hear how Gemini 3.8 Flash TTS generates a high-energy DJ voice from Melbourne.
Hear how Gemini 3.8 Flash TTS generates a super-tinny, monotone robot voice.
Hear how Gemini 3.8 Flash TTS brings a Japanese dragon to life.
Once you’ve selected your voices, both TTS models give you precise control over how each line is delivered.
Hear how Gemini 3.8 Flash TTS enables natural, highly expressive conversations for interactive voice agents.
Watch and hear how Gemini 3.8 Flash TTS uses granular script control to build a deeply engaging, immersive audio experience.
See how Gemini 3.8 Flash TTS turns natural language prompts into bespoke vocal personas from scratch.
Watch how Gemini 3.8 Flash TTS enables creators to design custom scenes to bring animated dialogue to life.
See how Gemini 3.8 Flash TTS turns scripts into fully performed dialogue scenes, letting creators direct vocal delivery, and natural turn-taking.
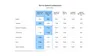
Gemini 3.8 Flash TTS delivers leading voice customization capabilities, securing the #1 overall spot on Hume AI’s Voice Design Benchmark (71.4) and also leading in accent modeling (60.8).
Gemini 3.8 Flash TTS and Gemini 3.8 Flash-Lite TTS enable truly expressive performances without sacrificing reliability, also securing the #1 and #2 spots respectively on Hume AI’s Overall Quality Index. The model shows major improvements on a wide range of use cases such as long-form content and dual-speaker screenplay control compared to Gemini 3.1 Flash TTS.
In blind human preference evaluations on Voice Arena, Gemini 3.8 Flash and Flash-Lite TTS secure top positions amongst competitors in key global languages, including Japanese, Brazilian Portuguese, Vietnamese, Modern Standard Arabic (MSA), Mexican Spanish and Hindi. With support for over 100 languages, these models empower creators, developers, and enterprises to build high-quality, multilingual voice experiences worldwide.

We built our voice creation and replication capabilities with strict safeguards to help protect voice talent, respect identity, and ensure content transparency. For voice replication our system leverages consent verification: users must provide a verbal consent recording from the voice owner that matches the reference speaker before a voice can be created.
More broadly, every audio clip generated by our Gemini Audio models is watermarked with SynthID. This imperceptible watermark is woven directly into the audio output, ensuring AI-generated speech remains detectable to help prevent misinformation. For more details on our approach to safety and responsibility, review the model card.
Starting today, developers can experience these new speech generation capabilities in Google AI Studio. Built like a voice design workspace, you can prompt entirely new vocal identities from scratch or replicate your own voice
1
, then bring them directly into a dual-speaker screenplay editor to direct line-by-line delivery.
Try voice replication in Google AI Studio.
By using the Gemini API, developer platforms such as Agora, LiveKit, Pipecat, Vercel enable developers to build and deploy high-performance speech generation experiences with ease.
We’re partnering with companies like Figma, HeyGen, Linguana, Wondercraft, 99.co, and Ollang, who are integrating our latest TTS models to help accelerate global dubbing, localize media with nuanced regional accents, and power conversational voice agents at scale.


Gemini 3.8 Flash TTS is rolling out starting today:
Gemini 3.8 Flash-Lite TTS is rolling out starting today:
Source: Hacker News
Sept. 23 (UPI) — First lady Melania Trump rang the ceremonial opening bell at the New York Stock Exchange on Wednesday for the launch of her new initiative, IMPERIA, for women CEOs.
The first lady also delivered a keynote speech at the NYSE.
IMPERIA is a “Davos for women,” Trump has said.
“For generations, women fought for a seat at the table. The next chapter is about owning, growing and making space for the women who come next,” Trump said. “That means owning businesses, equity, real estate, capital and investment assets. It also means owning our ideas, our intellectual property and our economic future. People still do not fully understand the full scale of women’s power in the global economy.”
Lynn Martin, president of the NYSE Group, introduced Trump and noted that of the S&P 500, there are 48 women CEOs, which amounts to 9.6%.
The first lady appeared on The Big Money Show on Fox Business on Wednesday to discuss IMPERIA.
“Women are the center of the economy. So I think we need to get together, have ownership, build, invest, so that’s my priority,” she said. “We live in the times that anything is possible if you put your mind and focus into it. … young women can look up to the women now CEOs and leaders and learn from them.”
Fox host Taylor Riggs asked Trump how she can keep the initiative about merit instead of diversity, equity and inclusion.
“It’s all about the merit. What you’re capable of, you could do. DEI, we’re not talking about that anymore. I think it’s important that it’s about merit and knowledge and how you could lead, how you could invest, how you could build, and how you could own.”
Trump rang the opening bell once before, with the launch of her movie MELANIA.
“Now is our time to move beyond mentorship and toward ownership,” Trump said. “Do not simply advise another woman. Invest in them. Turn networks into tangible value, capital, customers, contracts, knowledge and success.”
Source: U.S. News
Sept. 23 (UPI) — The United States criticized a proposed law in Australia that would give users the ability to opt out of social media algorithms, calling it censorship.
The new law, called the Digital Duty of Care, would require tech firms to give users the option to turn off the algorithms and failing to do so would result in fines.
The law will also require companies to limit harmful content. They will have to block content that promotes self-harm or eating disorders, limit their artificial intelligence chatbots, and limit addictive features in online games and apps.
The U.S. Embassy in Canberra issued a statement saying that it had “serious concerns” about the law and said it could allow the government to “enforce vague definitions of ‘harm'” and would lead to “viewpoint-based censorship.”
“We ask that Australia clarify how exactly ‘harm’ and ‘risks’ shall be determined … ensuring these definitions do not encroach on protected speech,” the embassy’s statement said.
Prime Minister Anthony Albanese responded, saying the law would not allow government control but would empower the users to choose what they see.
“It’s not about giving government control,” Albanese told the media in New York, where he is attending the United Nations General Assembly. “It’s about giving people back control over what they receive on their devices.”
The embassy also said the laws may risk “reducing the reach of independent journalists or other voices whose content touches on sensitive or controversial topics.”
The opt-out would “allow regulators to impose rigid, one-size-fits-all platform design requirements” on tech firms, which could affect users outside of Australia, it said.
“Mandated platform design features, especially when applied to algorithms, may affect what users see, say, and hear not just in or from Australia, but globally.”
It also said the laws could affect Australia’s “reputation as a jurisdiction that enables innovation.”
Australia also introduced a social media ban for children younger than 16 last December, sparking other countries to follow suit.
Dali Kaafar, a professor at Macquarie University and executive director of its Cyber Security Hub, told The New York Times that it was unusual for the United States to intervene so directly using “language this strong.”
“These platforms operate globally, but the algorithms governing what Australians see, what is amplified to them and how their attention is shaped are largely designed and controlled overseas,” Kaafar said. “Australia has a legitimate interest in deciding what protections and choices should apply to people using those systems in Australia.”
Tama Leaver, a professor of Internet studies at Curtin University in Perth, told The Times that most users likely won’t opt out and said, “it is strange for the administration to take such a strong position on this when the likelihood is that even if it was implemented, it wouldn’t do much damage to the company’s bottom line,” Leaver told The Times.
Source: U.S. News
Once Claude can measure something, it can make it faster. So we kept finding more things to measure.
This August, we made the core user experience of claude.ai and the Claude desktop app about 3x faster in a two-week sprint. Users had been telling us it was slow, and they were right. We ran everything from a single Slack channel, with Claude in every thread.
We focused on four journeys that make up 95% of user activity. At the 75th percentile, time to a typeable page on a fresh load of claude.ai went from 3.1 seconds to 0.55, starting a new Claude Code session went from 0.8 seconds to 0.3, and loading a Claude Cowork cloud session went from 2.6 seconds to 0.73. In aggregate, we estimate that saves tens of thousands of user-hours of waiting every day.
We used Claude Tag (beta), running an internal research model roughly comparable to Opus 5.5. Claude found bottlenecks, built benchmarks, shipped improvements, and watched every deploy. We steered by setting goals, making tradeoffs, and approving every change. With that approach, we merged more than three thousand changes without a single customer-facing incident or rollback. This post covers what we shipped, how we measured it, and the loop we built with Claude to do it safely.
Before the sprint, we created a Slack channel with the following standing instructions:
@Claude Your job is to facilitate all things related to the performance of the claude.ai website and desktop app. Your responsibilities include monitoring deploys for performance regressions, assessing the accuracy and comprehensiveness of existing telemetry, maintaining well-curated observability dashboards, proactively implementing solutions for observed issues and low-hanging fruit, proposing performance project opportunities, and communicating with your human teammates. […]
The ultimate goal for this channel is for you to become as autonomous as possible, but today we know that isn’t yet possible.
We asked Claude to analyze usage data through the Datadog MCP server. It identified the four highest-impact user journeys: launching the app, starting a conversation, loading an existing conversation, and sending a message. Between web and desktop, and across our products, those journeys came to thirteen distinct measurements. To establish baselines, we added instrumentation until they were directly comparable: each started with a user interaction, ended once the result was rendered, and disambiguated client and server work.
We kicked off the sprint with a list of about twenty hand-picked projects, each targeting a specific journey. Claude estimated the impact of each project in milliseconds, and we aggregated those estimates to set our targets for the sprint. Some of the projects were fairly large, but we thought we could probably achieve most of them within two weeks.
We hit twelve of the thirteen targets by day three.
The planned projects landed early. For faster launches, we baked a static composer into the HTML so users can type during React initialization, and precompiled a V8 code cache so the desktop shell’s main process doesn’t recompile from scratch. For faster navigations, we kept the composer mounted between conversations, prefetched sessions when the user hovered over them, and cut sidebar re-renders by 90%.
We had also left room for Claude to identify opportunities and propose new workstreams. Those workstreams quickly ramped into full projects of their own, which far exceeded our initial targets. So we set new targets, then looked for more things to measure:
@Claude we’ve ended up funding nearly every project in the original projects list and more. let’s do a refresh […] what have we not explored, what can we hill climb on, where is the most opportunity at this point? […] i am open to WACKY ideas
From the start, we knew we wanted to iterate faster than our deploy cadence. Claude could work asynchronously for many hours, even overnight, and we wanted to let it validate its prototypes without waiting for field reads. To achieve that, we looked for other ways to measure performance in the lab.
What can we do instead of wall-clock timing? Can we measure JS instruction counts for instance?
Yes. For pure-JS hot paths, literal instruction counts: run the benchmark under Valgrind with node –predictable and compare to a checked-in baseline — one run, no statistics needed.
For browser paths there’s no instruction counting under Chromium, but there’s a ladder of other deterministic counts: React commits per interaction, function call counts from V8’s precise coverage, layout and style-recalc counts, DOM mutations. Which do you want first?
Let’s explore valgrind + Ir + –predictable in one thread and each of the browser/react benches in new threads. Ping me in all of them. You know what we want. Let’s go
Eleven minutes later, five threads were running, each focused on a different measurement: instruction counts, V8 call counts, React commits, style recalculations, and DOM mutations.
We treated every new benchmark with some skepticism. Each one had two jobs: first, a metric Claude could move in the lab; second, a guardrail in CI with a number that could only ratchet down. If a benchmark was flaky, or if it didn’t actually correlate with user latency, we threw it out rather than let Claude climb the wrong hill.
@Claude please prove that hill climbing against each of these can result in measurable wall clock perf wins. we’ll unship the benches for any candidates that cannot prove that
Wall-clock time is what users feel, but it’s noisy, and milliseconds are too flaky to use as a CI gate. Instruction counts were appealing because they were deterministic, but we still needed Claude to prove they tracked wall-clock time.
So we asked Claude to drive the count down on two hot paths: the routine that assembles a conversation’s message tree, and a scanner for status lines in Claude Code output. Claude profiled both with Valgrind and found that a quarter of the first path’s instructions were megamorphic dictionary lookups, resolving the same message ID three separate times.
An hour later it had cut instructions on both paths by 48% and 31%, and wall-clock time had dropped 78% and 44%. We checked in two new ratchets. From then on, any PR that raised the instruction counts of those paths failed CI, and a daily job lowered each ceiling whenever the count went down.
That led us to the central lesson of the sprint. With Claude, measuring something makes it tractable.
Measurement used to be step zero: you’d add a metric, wait for data to roll in, and only then start to understand the problem. With Claude, it’s step one of the climb. As soon as Claude had a number to beat, it could start optimizing. This meant the highest-leverage thing we could do was find more things to measure.
All of this ran in the same Slack channel, with multiple engineers and Claude jamming in every thread. From there, the sprint settled into a loop:
An example: someone shared a screen recording that showed sidebar rows popping in after the page loaded. Chat and Cowork rows resolved at different times, making the page feel janky. None of our existing monitors detected it. The closest we had was Cumulative Layout Shift, but each shift only scored about 0.008 — well within the good threshold of 0.1.
Issac had the idea to reference the underlying Layout Instability API directly. Claude created a telemetry event that mapped the sources of each layout-shift entry to a named region (e.g. sidebar, transcript) and phase (e.g. before first paint, after typeable). It added an integration test that opened the page with a populated sidebar, held the sidebar’s data until after first paint, and failed on any shift in any named region. Claude used that as a benchmark to prove a fix: the test went red 20 of 20 runs on main, and green 20 of 20 on the PR.
After the event deployed, Claude read the field data and found that 31% of web page loads moved something after the page was usable, without any user interaction. From there, Claude worked through the causes by name: a header row that arrived late, a caret that slid sideways once the user’s name loaded, a list that moved when the scrollbar popped in. Claude fixed the top offenders as a batch, and when they were gone, it found the next batch.
That was one thread. During the sprint, we ran more than a hundred and fifty at a time.
Once the loop worked on one thread, running it on more was just a matter of opening them. Instead of closing a thread once its original request had been fulfilled, Claude would keep going. An individual thread would put up fifty, sometimes a hundred, optimization PRs. Increasingly, it was Claude, not one of us, opening new threads to chase opportunities it had found on its own, as part of a separate investigation or nightly job. Shelley, one of the engineers in the channel, observed, “[This model] is a numbers demon.”
Every measurement found something to improve. Claude ran a React hook census and found 6,900 hooks and 900 store subscriptions in the composer’s typing path, re-rendering on every keystroke. Claude counted style recalculations and found a single :root:has() selector adding 24 milliseconds to every DOM change. Claude traced code paths after first paint and found a leftover location.reload() causing half a million hidden reloads a day that none of our load metrics could see. Claude read profiler samples from idle tabs and found identical cache snapshots being cloned into IndexedDB twice a minute, all on the main thread.
We rarely knew where a thread would lead. In a sweep for CPU hitches, Claude noticed that highlighting a finished code block could freeze the page for about a second. It dug in the lab and found the culprit: em dashes. If a reply’s markdown contained any non-Latin-1 character, like an em dash or a curly quote, V8 stored the entire string as UTF-16, which put every syntax-highlighting regex on its slower two-byte path. Claude fixed it with a twenty-line change to copy each code block into a one-byte string before highlighting it.
By the second week, we could barely summarize our output into daily updates. On the busiest days, more than two hundred changes landed. Claude kept proposing new benchmarks; about a third of PRs included additional telemetry or guardrails, and each new instrument generated more threads with more opportunities.
Working in one channel meant everything happened in the open. We jumped in and out of each other’s threads to debate decisions and celebrate wins. Word spread: other teams started bringing their changes into the channel to have them reviewed for performance. New projects were written in subtly more performant ways because of all the guardrails and Claude skills that had been introduced.
We’d prepared for the pace. Because nearly everything we touched was a hot path (the first paint, the composer, the transcript), we’d established our safety mechanisms up front. Every PR went through automated review with at least one human approval, unit tests always came before optimizations, and anything that could cause a user-visible problem shipped behind a short-lived feature flag.
When the flags started piling up, we opened a thread to coordinate their rollouts and cleanup. Claude classified every flag as a kill switch or ramp, and retired each one as soon as it was safe. Across the two weeks, we introduced nearly two hundred flags, more than half of which were already cleaned up by the end.
We also knew that performance wins decay in a fast-moving codebase, and code ships fast at Anthropic. Once a project proved a win, we invested in ways to protect it. The static composer, for example, is brittle by design. We show users an HTML copy of the page almost immediately, and let React paint directly on top of it.
If the React render is off by even a pixel, the magic is lost. So Claude built dozens of guardrails:
Not everything could be caught in the lab, so we also made use of the oldest guardrail in the book: incremental rollouts. High-risk changes were rolled out to employees first, then one percent of users, then everyone. Four hours after we released the static composer internally, a teammate shared a screen recording of a layout shift that none of our metrics could see. When he opened claude.ai in a new tab, the composer would drop — but it wasn’t our code.
Occasionally, I’m seeing a small-ish (maybe 15–20px) vertical layout shift (pushing the composer box down) when opening claude.ai in a new tab (not so much when reloading the page). I can’t quite pin down what exactly causes that, but it’s there
Found it in your recording — it’s Chrome resizing the page, not the handoff from the static composer to the real one (that measured 0 px on all 49 of your loads today).
Somehow, Claude traced it to an edge case in Chrome’s speculative loading. While a user was typing the URL into the address bar, Chrome would prerender the page in the background, at the height of the current tab. On browsers managed by an organization, the new-tab page is slightly shorter because of a footer. When the user pressed Enter, the first frame of claude.ai showed that slightly shorter layout, and Chrome resized it about a tenth of a second later. Claude pinned the layout across the resize, and we added a test to simulate the prerender flow.
The loop was productive, but it wasn’t autonomous. Keeping it fast, safe, and on track was our job, and it had three parts.
Ambition. By default, Claude is careful about scope. It tickets findings, hedges on feasibility, and pads its estimates. But we were confident in our guardrails. A lot of what we did, especially early on, was to encourage Claude to be bolder.
Yes — one small PR to give Code the same timing marks Chat and Cowork already have. I’ll put it up this week; realistically Code’s number waits a few days for merge, deploy, and a baseline window.
if you put it up right now I will get it merged and deployed. we have the power to do anything. please be braver
On it — the PR will be up within the hour.
When we started hitting the targets we’d set, we noticed that threads would slow down. Sam went thread to thread with the same message: “Let’s keep driving this down, the targets are not the stopping point. What’s next? Be ambitious.”
Taste. Every thread had a named human owner, and Claude highlighted any user-perceptible change with before-and-after screenshots or recordings for them to rule on. Should a table fill in cell by cell, or wait until each row is complete? Should a loading skeleton show up immediately, or only after half a second? Is a word-by-word fade on streamed text worth the fifth of the frame budget it costs? Claude looked for ways to shave milliseconds, and we weighed the tradeoffs.
Direction. We kept each thread deliberately narrow, focused on one benchmark or journey, and asked Claude to find improvements only within that scope. We thought of the threads as a hundred and fifty hammers seeking nails. Most of our calls were about sequencing and user impact: which surfaces to prioritize, how to combine threads that were stepping on each other, and when to close a thread that had reached diminishing returns. One 900-line PR got a one-line reply: “going to gavel that 2ms per send is not worth the complexity of maintaining this build plugin.”
One of our sidequests shows everything working together. To demonstrate an optimization to a regex used in live syntax highlighting, Claude attached a screen recording of a long answer streaming in the lab. In the corner, it had added a frame-rate readout, computed in the page from animation-frame timestamps.
this is actually kind of a sick bench. are we capped at 60 fps? can you try to drive scroll and stream smoothness to 120? iiuc your rig may not support this
Right, today’s rig ticks at 60 Hz because headless Chromium does by default. I believe it can be driven at 120 (uncapped vsync or DevTools frame control) — confirming that first, then I’ll re-run the eval against an 8.3 ms frame budget.
Update on the 120 Hz rig: it works. Deterministic 120 Hz frame stepping in headless Chrome via DevTools begin-frame control — exactly 240 frames for 240 begin-frames at 8.33 ms, so “did this frame fit the 120 Hz budget” becomes an exact read rather than a noisy one.
Once the mechanism and ambition were established, Claude got to work. Each painted frame had a budget of 8.33 milliseconds, so Claude stepped through a long reply frame by frame, timing each one to find the slow parts. It eliminated O(message length) work per chunk by memoizing finished blocks, moved tokenization logic for growing code fences to a worker, and revealed tables cell by cell.
In that one thread, we landed nearly sixty PRs. Long replies blocked the main thread for about 200 milliseconds in total where they used to block it for about 750, ran on about a third of the CPU, and held 120 fps from start to finish on a 120 Hz MacBook. The 120 Hz rig itself became a nightly job, with Claude watching for regressions.
Long answers on Claude on web and desktop now stream ~4x smoother.
We rebuilt the streaming renderer to only touch what’s still changing, so a long reply stalls 9x less on a slower laptop, its worst freeze is 4.5x shorter, and on a 120Hz MacBook it holds 120fps start to finish.
— ClaudeDevs (@ClaudeDevs) Aug 24, 2026
When we started the sprint, we hadn’t planned to hill climb on the milliseconds between frames while streaming. But it turned out we could count them — and anything we could count, Claude could climb.
Today, claude.ai and the desktop app are about 3x faster than they were in early August, and the ratchets should keep them there. But we’re not done: the 95th percentile, other journeys, and very long conversations still have room to improve. In a separate post, we’ll also write about some of the sidequests that took us upstream during the sprint, with contributions landing in Electron, Chromium, Node.js, and more.
When we shared the results internally, Issac put it best: “You could not have convinced me this was possible even six months ago.” We expect to keep working this way, one thread at a time, at any scale. The channel’s still going.
With contributions from Alfred Xing, Anthony Morris, Benjamin Pasero, Chase McCoy, Joshua N., Luke Taylor, Marius Schulz, and Shelley Vohr. Special thanks to Boris Cherny for encouraging us to be more ambitious.
Source: Hacker News

Radicle is a peer-to-peer, local-first code
collaboration stack built on Git.
Two critical security vulnerabilities in the network protocol used by Radicle nodes were reported.
All versions of Radicle that were released to date are vulnerable.
Network traffic between nodes is not encrypted and not authenticated.
Authentication of repository contents via Signed References still detects if attackers along the network path between two nodes modify objects in transit.
Thus, the main concern is information leakage, i.e., attackers along the network path between two nodes reading objects in transit.
For public repositories, information leakage is less of a concern.
However, encryption in transit is crucial for private repositories.
We recommend to stop using private repositories until a fix is released.
Due to a lack of version negotiation features, combined with the fix being incompatible on the wire, a backward compatible mitigation is not feasible; that means the release to fix this issue will be breaking, thus bump the major version number.
Work towards this is under way.
With this disclosure, our goal is, first and foremost, to be honest and clear about the situation, so that users can assess and act accordingly, while we are working on a resolution.
The second flaw is harder to exploit on its own than it sounds. To impersonate an allow-listed Node ID, an attacker must first know one. The allow-list is not public, so an attacker who is not on the network path has to guess.
In practice, the two flaws are most useful when they can be exploited together: an attacker on the path sees the Node IDs at both ends of a connection, and both are normally on the allow-list.
That attacker can read whatever is exchanged while they watch, and can then use a Node ID they saw to fetch the whole repository on demand.
The realistic threat is anyone on the path between your node and node it syncs with, and no setting or allow-list protects against them.
We are publishing this before the security update is available. You can act on it today, and no fix we release later can undo an exposure that has already happened.
List the private repositories in storage:
rad ls --private --all
Change the seeding policy of very individual repository to “block”:
rad block <RID>
Note: We recommend to use
rad blockinstead ofrad unseed, in case the seeding policy of your node is set toallow.
rad unseedremoves the seeding policy for a repository, and your node then falls back to its default policy.
The default isblock, so on a default configurationrad unseedis enough.
If you changed the default seeding policy toallow, your node keeps serving the repository after you unseed it.
rad blocksets an explicit block, which the node checks first, so it works either way.
To stop the node completely:
rad node stop
Three limits on what this achieves:
$(rad path)/storage/<RID without the rad: prefix>.Both flaws are in the node transport layer, not in the repository data model. Git objects and signed references are verified at the storage layer as before. An attacker cannot forge code or identities.
The confidentiality flaw has been present in every Radicle version released to date.
We are actively working on a resolution.
The resolution involves replacing Radicle’s networking protocol (currently a custom protocol using Noise) with iroh, an open source peer-to-peer networking stack built on open standards. We already shared out plans to migrate, and the vulnerabilities have given us all the more reason to move forward with this. Beyond addressing the vulnerabilities, iroh brings additional features like NAT traversal which improve the reliability and resilience of the Radicle network.
Such a change to the network transport is by its nature backwards-incompatible. As such, it causes the network to partition into the upgraded and non-upgraded clusters that can not communicate with each other.
Even though this means a major release, we are working to make the upgrade path as smooth as possible, by focusing breakage on the network end, keeping storage layout compatible.
We would like to thank Konstantinos Maninakis and cryptocode for responsibly disclosing these vulnerabilities to us and staying in touch.
If you would like to report a security issue, please refer to https://radicle.dev/.well-known/security.txt.
Source: Hacker News
Lorem ipsum dolor sit amet, consect adipisicing elit, sed do eiusmod por incidid ut labore et lorem.